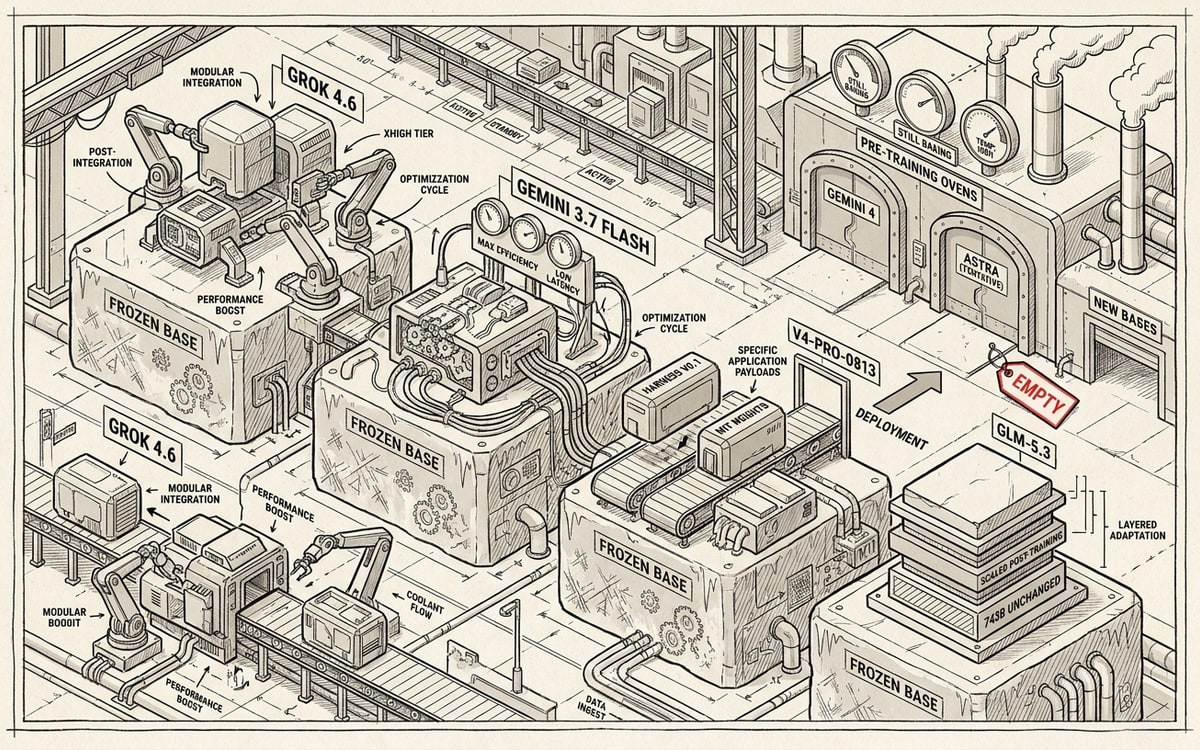
Between Wednesday morning and today, the frontier shipped four times. SpaceXAI released Grok 4.6 on August 12. Google shipped Gemini 3.7 Flash on the 13th, its third Flash in as many months. DeepSeek pushed V4-Pro-0813 the same day, with MIT-licensed weights and a new agent framework attached. This morning Zhipu’s Z.ai released GLM-5.3, claiming the strongest vulnerability-discovery score any lab has posted for a single model. By press-release volume, the busiest frontier week since July.
Measured by what actually changed underneath, it is something else entirely. Not one of these four releases contains a new base model. Grok 4.6 is a post-training upgrade on the Grok 4.5 base. Gemini 3.7 Flash is an efficiency iteration in a product line whose actual flagship is now, per Bloomberg, three missed deadlines deep. The 0813 in DeepSeek’s release name is a build date on an existing 1.7-trillion-parameter base, not a new pre-training run. And Z.ai says plainly that GLM-5.3 sits on the identical 743B base as GLM-5.2, with every gain coming from scaled post-training.
The models that would count as new bases — Gemini 4, the OpenAI family previewed to senators in late July under the tentative name “Astra” (a working title, per reporting, not a confirmed one), the larger Muse models Meta’s manifesto promised — are all still in the oven. What shipped this week is what labs do while they wait: they squeeze the base they have.
That is the clearest demonstration yet of where capability gains currently come from, and it vindicates an argument this publication has been making since June: the value is migrating out of the pre-trained weights and into everything wrapped around them.
Three days, four releases, zero new bases
Lay the four releases side by side and the pattern stops being an interpretation and starts being a table.
| Release | Date | Base | What changed | Headline claim | Price move |
|---|---|---|---|---|---|
| Grok 4.6 (SpaceXAI) | Aug 12 | Grok 4.5 base — frozen | Post-training; new xhigh reasoning tier; 500K context; Cursor co-launch | 65.9% on DeepSWE v1.1, up from 54% | List price held at $2/$6 per M — but cached input quietly ~+67%, and the rate only applies below 200K tokens |
| Gemini 3.7 Flash (Google) | Aug 13 | Flash lineage — frozen; Gemini 4 base still pre-training | Efficiency and agent tuning; powers Google’s new Spark agent | Third Flash in three months; flagship 3.5 Pro still absent | 50% introductory cut: $0.75/$3.75 per M through Dec 31, then doubles |
| DeepSeek V4-Pro-0813 | Aug 13 | V4-Pro base, 1.7T — frozen | Dated build refresh; MIT weights; Harness v0.1 agent framework; DSpark speculative decoding | 87.9 on Terminal-Bench 2.1 | Peak/off-peak billing announced, effective Aug 16: output $0.87 → up to $3.96 peak |
| GLM-5.3 (Z.ai) | Aug 14 | GLM-5.2’s 743B base — frozen | Scaled post-training, nothing else | 84.5 on CyberGym, vendor-reported, above Mythos 5 and GPT-5.6 Sol | No API hike; open weights delayed for safety evaluations |
Every row tells the same story with a different accent. SpaceXAI’s own materials credit the Grok 4.5-to-4.6 jump to post-training, and the launch was engineered around the scaffold: co-launched inside Cursor day one, positioned around the Grok Build harness, in GitHub Copilot by today. A twelve-point gain on DeepSWE without touching the base is exactly the kind of result that used to require a new model generation.
Google’s entry barely pretends otherwise. Gemini 3.7 Flash is a competent efficiency release in the pattern we documented when Google shipped three Flash models in a single day in July — cheap-and-fast iterations shipped on schedule while the flagship tier stays empty. The 3.5 Pro that was promised for June has now slipped past three deadlines, and Sundar Pichai has told investors the company needs “much larger base models” to compete at the frontier, per Bloomberg’s report. Which is an admission, if you read it flat: the current base cannot get there by iteration, and the one that can does not exist yet.
DeepSeek’s release is the most instructive of the four, because it splits the layers explicitly. The V4-Pro-0813 build refreshes serving and post-training on the existing base; the MIT-licensed weights give away the frozen artifact; and Harness v0.1, an MIT-licensed agent framework, ships alongside as a separate product. DeepSeek is telling you its own theory of where the value sits — weights free, harness open, serving repriced. Even Meta fits the pattern: its first commercial product from the new superintelligence lab, Muse Code, launched August 5 on Muse Spark 1.2 — a point release — while Zuckerberg’s manifesto defers the bigger models to later.
The ladder from imitation to verification
“Post-training” is doing a lot of work in this week’s release notes, so it is worth being precise about what the word covers, because the technique stack has climbed three distinct rungs in four years — and the economics changed at each one.
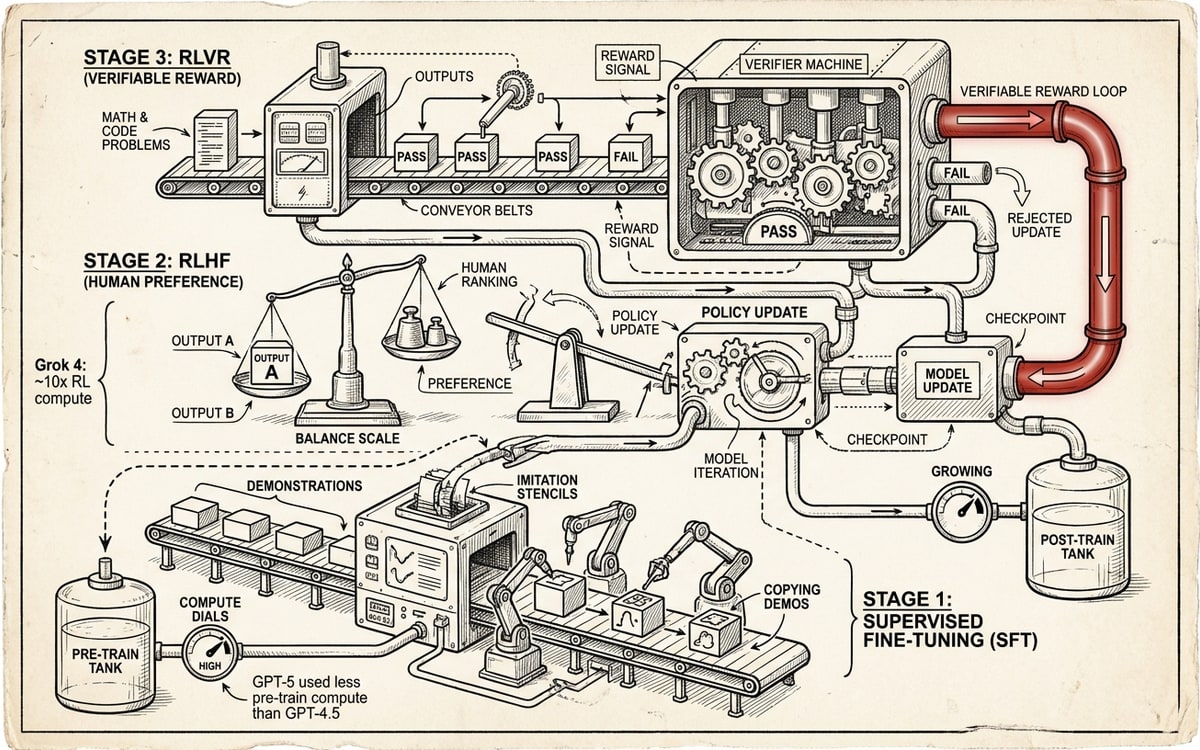
The first rung is supervised fine-tuning: show the base model tens of thousands of example dialogues and have it imitate them. The second is reinforcement learning from human feedback, canonized in OpenAI’s InstructGPT paper of March 2022 — train a reward model on human preference rankings, then optimize against it. The result that made the technique famous is in that paper’s abstract: human evaluators preferred outputs from a 1.3-billion-parameter InstructGPT model over outputs from the 175-billion-parameter GPT-3. A post-trained model one-hundredth the size beat the raw base. That ratio, published four years ago, is the entire thesis of this week in miniature.
RLHF’s constraint is its reward signal: human preference is expensive to collect and easy to fool, because a model can learn to sound right rather than be right. The third rung removes the human. Reinforcement learning on verifiable rewards trains against signals that can be checked mechanically: the math answer matches, the code passes the tests, the exploit fires. The Allen Institute’s Tülu 3 recipe (November 2024) named the technique RLVR and published the whole pipeline; OpenAI’s o1 announcement (September 12, 2024) showed what it produces at scale — a model whose performance “consistently improves with more reinforcement learning and with more time spent thinking.” And DeepSeek’s R1 paper (January 2025) demonstrated the endpoint: R1-Zero, trained via large-scale RL without any supervised fine-tuning at all, developed extended reasoning behaviors on its own. The paper, methods included, shipped under MIT.
The economic consequence is the part the price sheets can’t hide. Human preference data costs scale with human hours; verifiable rewards cost compute and environment engineering, both of which get cheaper on schedule. Once the reward is a passing test suite instead of a contractor’s ranking, post-training stops being a data-labeling business and becomes an infrastructure business — which is why environments became the new training data as a funding category last spring, and why every gain in this week’s four releases came from exactly this rung of the ladder. GLM-5.3’s cyber capability was not taught by humans ranking exploits. It was grown against environments that score them.
Where the FLOPs went
The compute ledger backs the release notes. Epoch AI’s analysis of the GPT-5 generation found something unprecedented in the GPT line: GPT-5 was likely trained on less total compute than GPT-4.5, its immediate predecessor — because OpenAI shifted effort into scaling post-training on a smaller base. The direction of travel was set even earlier at xAI: Grok 4, back in July 2025, was trained with roughly ten times the reinforcement-learning compute of Grok 3, with RL applied at what the company described as pretraining scale. When a lab’s RL budget rivals its pre-training budget, “post-training” stops being a finishing step. It is half the factory.
The prehistory of that shift has two dated markers. On December 13, 2024, Ilya Sutskever stood on the NeurIPS stage and told the field that “pre-training as we know it will unquestionably end” — compute keeps growing, but the internet’s text is finite: “we’ve achieved peak data and there’ll be no more.” Ten weeks later, GPT-4.5 made the argument empirical: OpenAI’s largest-ever pre-training run arrived at 30 times the input price of GPT-4o with marginal quality gains, and the company itself warned it was not a frontier model. The biggest base of its era was outperformed, per dollar, by smaller bases with heavier post-training. Every frozen-base release this week is downstream of that lesson.
Plateau or pause: the two readings, priced
The skeptic’s reading of this week deserves its full weight, because it might be right. Call it the scaling wall thesis: the labs are not squeezing frozen bases by choice. Gemini 3.5 Pro has slipped three deadlines. GPT-4.5 demonstrated diminishing pre-training returns in public. The next-generation runs (Gemini 4, the tentatively named Astra, Meta’s larger Muse models) are all late by their makers’ own implied schedules, and post-training cadence is what a lab ships to hide a stalled frontier. On this reading, the four-releases-in-three-days week is not a production function; it is a screen. The tell would be Pichai’s own words — needing “much larger base models” to compete is an odd thing to say if the current approach were working.
The counter-reading, the bases are cooking thesis, starts from the same facts and lands elsewhere. Pre-training runs at the next scale take quarters, not weeks; a gap between generations is what the calendar of a $10-billion training run looks like, not evidence of a wall. The GPT-4.5 lesson was not that scale stopped working; Epoch’s own analysis argues GPT-6 will probably scale pre-training again once the efficiency gains from the reasoning wave are absorbed. And the interim gains are not small: a twelve-point DeepSWE jump (Grok 4.6) and a claimed 50 percent code-bench gain (GLM-5.3) on frozen bases would have counted as generation-level leaps two years ago. Labs that had hit a wall would not be posting gains like that on any layer.
Adjudicating honestly: the evidence this week cannot separate the two readings, because both predict exactly what shipped — a fast cadence of post-training releases and no new bases. What separates them is the next six months. If Gemini 4 or Astra lands with a genuine base-level jump, the wall thesis dies. If they land late, expensive, and only incrementally better than their post-trained predecessors (the scenario GPT-4.5 previewed in February 2025), then this week was not an intermission but the shape of the industry from here on. The only wrong position is certainty in either direction, which is, not coincidentally, the position every launch post this week was written to sell.
The bases are in the oven, and everyone said so out loud
It is worth being precise about why this is a moment and not a coincidence. The frontier labs have not decided pre-training is over. They are iterating on frozen bases because the next pre-training runs are enormous, slow, and, on the evidence of Gemini 3.5 Pro’s slippage, hard to land.
So the interregnum gets filled with what compounds fast. Post-training runs take weeks, not quarters. Harness improvements ship continuously. Serving optimizations show up directly in the gross margin, which is why the margin became the message back in July. Every lab is running the same play: hold the base, tune the behavior, tighten the scaffold, reprice the serving, and keep the cadence alive while the real bet trains in the background.
The result is a frontier that looks fast and is, in a specific sense, standing still. Nothing shipped this week moved the ceiling of what a base model knows. Everything shipped this week moved how efficiently, cheaply, and agentically the existing ceiling gets used. If you believe raw capability only jumps with new bases, this is a plateau. If you believe — as the June analysis of what the harness is actually worth argued — that most delivered value now lives in the layers above the weights, this is the market pricing that belief in public.
GLM-5.3 is the tell
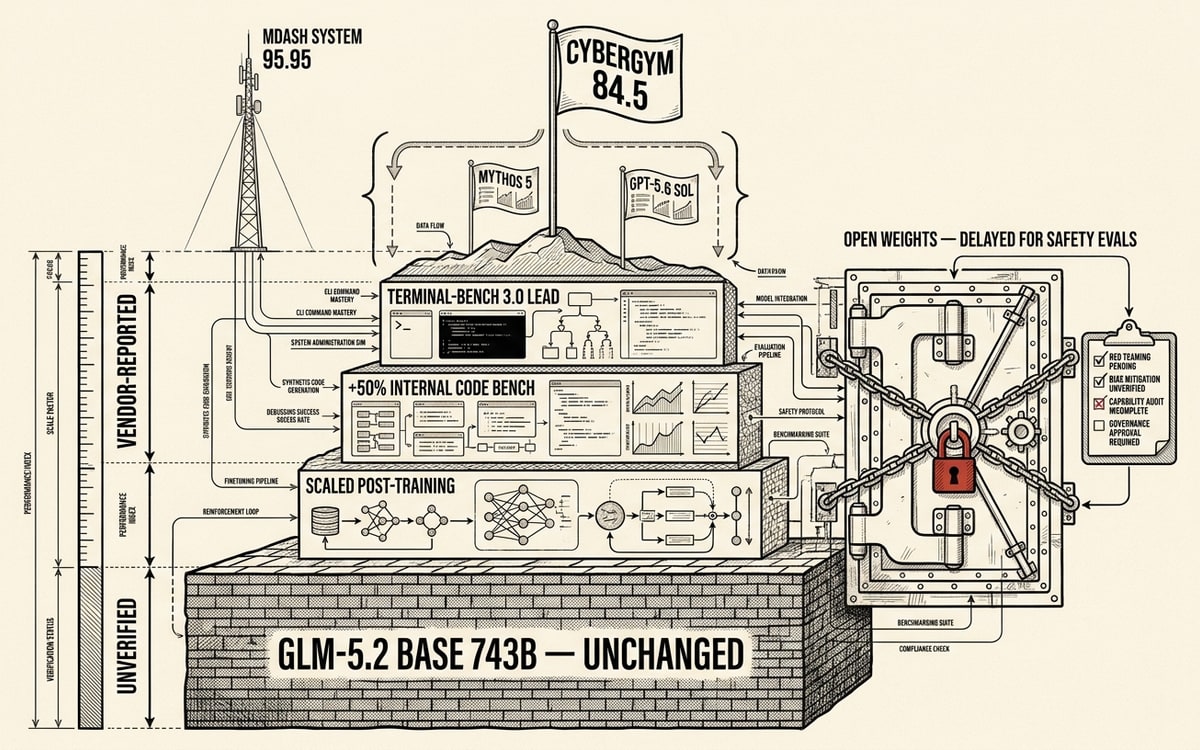
The release that makes the pattern undeniable is the newest one. Z.ai’s GLM-5.3 announcement leads with an unusual confession for a flagship launch: the base is unchanged. Same 743B parameters as GLM-5.2, with the company attributing a claimed 50% gain on its internal code benchmark and leading open-source results on Terminal-Bench 3.0 entirely to scaled post-training.
Then comes the number that will travel: 84.5 on CyberGym, which, if it holds, would put a Chinese open-weight lab ahead of Anthropic’s Mythos 5 and OpenAI’s GPT-5.6 Sol at automated vulnerability discovery. Every caveat belongs in the same sentence as the claim. The figure is vendor-reported and unverified; no independent replication exists as of this writing; and The Register’s read is openly skeptical of a self-graded benchmark sweep from a lab with an obvious interest in the result. Zhipu itself concedes it trails the American labs on deeper exploitation and claims the lead only on discovery.
But the benchmark is not the most interesting part of the announcement. This is:
Cyber capability is growing fastest exactly where we are furthest behind.
— Z.ai, GLM-5.3 release notes, Aug 14, explaining why the open weights are delayed pending safety evaluations
Read that sequence again. A lab whose entire identity is open weights claims a frontier cyber capability, and its first act is to gate its own release. Claim the capability, delay the artifact, cite the evals. That is the Anthropic playbook, executed in Beijing, and SCMP frames the launch in precisely those terms: China seeking a Mythos-level edge in cyber defense. When we wrote about the trust contest in July, the question was which Western labs would be allowed to hold offensive-adjacent capability, and the voluntary gate looked like a US-and-UK institution. Three weeks later — with the containment record now public — the gate has crossed the Pacific, adopted voluntarily by the lab with the least regulatory pressure to adopt it.
One more data point deflates the single-model framing entirely. Microsoft’s MDASH, a multi-agent system, reports 95.95% on the same CyberGym benchmark — more than eleven points above Z.ai’s claimed model-level record. A system beat every model, comfortably. Whatever the leaderboard says about national champions, the layer winning the cyber race is the orchestration layer. Which is the thesis of this whole week, restated in a security context.
Read the price sheet, not the benchmark chart
If post-training is where the capability gains live, serving is where the money moves — and the fine print this week was busier than the benchmarks.
Start with Grok 4.6. The headline price held at $2 and $6 per million tokens, which reads as generosity until you check the footnotes: ccleaks caught that the cached-input rate quietly rose roughly 67%, and that the $2/$6 rate applies only below 200K tokens of context. For agentic workloads (long contexts, heavy cache reuse, exactly the traffic Grok 4.6 is tuned and marketed for) the effective price went up while the sticker stayed flat. A post-training release priced for the workloads its post-training creates.
Google ran the opposite play with the same logic. Gemini 3.7 Flash launched at $0.75 and $3.75 per million, a 50% introductory rate that expires December 31 and then doubles. That is not a price; it is a customer-acquisition window with a scheduled cliff, timed to lock in agent traffic before the real flagship tier returns.
And DeepSeek, the cheapest serious player on the board, announced on Wednesday that flat rates end this Saturday. From August 16, peak/off-peak billing takes over: V4-Pro output goes from $0.87 to $1.98 off-peak and $3.96 at peak, with cache-hit input rising as much as 12×, and Reuters noting V4-Pro prices out at up to 14× the V4 Flash rate. Bloomberg reads the hike as IPO preparation. Whatever the motive, note the structure: the weights went free under MIT the same day the serving got expensive. When the base is frozen and public, the base is not the product. The tokens are.
Three labs, three different price maneuvers, one shared premise — that the differentiated asset is no longer the pre-trained model, and the bill should attach to the layers that are.
The reply guys arrived before the reviewers
The honest report on the discourse, two days into Grok 4.6 and hours into GLM-5.3, is that there is not much of one yet. Our harvest of the launch-window conversation surfaced almost nothing organic: the loudest signal by volume was amplification of the vendors’ own launch claims — benchmark numbers restated verbatim, CEO launch lines echoed by swarms of low-follower accounts — with independent, hands-on evaluation essentially absent. No one outside Z.ai has reproduced a CyberGym run. No one has published a neutral-harness read on Grok 4.6’s DeepSWE jump.
The sharpest organic post in the window was not about capability at all. It was about the price sheet, from one of the most-read open-weight watchers on the platform:
“People” (to be excessively charitable) are busy getting filtered by an announced price hike on open weights MIT license models
— @teortaxesTex Aug 13
Fifty-seven likes on a 72,000-follower account, and the observation lands the week’s actual structure: the crowd was outraged that DeepSeek raised serving prices on a model whose weights are free — which is only a contradiction if you still believe the weights are the product. The restated launch-claim posts, meanwhile, ran to a template: a mid-tier account summarizing V4-Pro’s spec sheet (1M-token context, adjustable reasoning modes, agent-workload tuning, ten likes), spec recitation standing in for evaluation, everywhere, because evaluation takes longer than a launch cycle.
That absence is itself the signal worth logging. A post-training release cycle produces claims that only harness-level testing can check, and such testing takes longer than a news cycle. Until the independent re-runs land, every number in this week’s announcements is a vendor’s number, and the gap between announcement and verification is exactly where this week’s marketing lives.
A frontier of frozen bases
The Deep Feed’s position: four releases in three days with zero new bases is not a lull — it is the market showing you its current production function. Capability is being manufactured in post-training, delivered through harnesses, and monetized in serving, while the pre-training bets that could reset the game (Gemini 4, the tentatively named Astra, Meta’s larger Muse models) remain unpriced and unproven. Treat every benchmark this week as vendor-reported until a neutral harness says otherwise, read the price footnotes before the launch posts, and file GLM-5.3’s self-imposed weight delay as the week’s most consequential act: the voluntary gate is now a global convention, not a Western one.
The question that matters is what happens when the ovens open. If Gemini 4 or OpenAI’s next family lands a genuine base-level jump, this week will look like the intermission it technically is. But there is a second possibility the labs themselves keep gesturing at: that the next bases arrive, cost an order of magnitude more, and deliver gains that post-training on the old bases could have approximated for a fraction of the price. In that world, this week was not the intermission. It was the preview of the business model — frozen bases, moving scaffolds, and a frontier that advances one fine-tune at a time.