Moonshot AI shipped Kimi K3 on July 16, and the number everyone repeated was the wrong one. Two-point-eight trillion parameters. The world’s first open 3T-class model, in the company’s framing — the largest set of open weights any lab has ever posted for download. A genuine milestone, and also the least interesting fact about the release.
The interesting fact sits next to it in the same news cycle: Moonshot is reportedly raising at a valuation around $30 billion. A startup whose pitch to investors rests on being at or near the frontier of a scarce, expensive capability took its single most valuable artifact — the frontier model itself — and gave it away. Not licensed it. Not gated it behind a trusted-partner list. Posted the weights.
That is the tension this piece is about. Not whether K3 is good (it is, at some things, and behind at others), but what it means that the company most aggressively open-sourcing the frontier is the one asking the market to price it like a frontier lab. Either open weights are the strategy that makes the $30 billion real, or they are the concession of a firm that knows it can’t win on access and is monetizing attention instead. The release is legible both ways, and Moonshot is betting you won’t ask which.
A 2.8T MoE, native vision, and two attention tricks
Strip the superlatives and look at the artifact. Kimi K3 is a Mixture-of-Experts model with 2.8 trillion total parameters, a sparse fraction active per token. It has native vision (image understanding built into the base model rather than bolted on) and a 1-million-token context window, now table stakes at the top of the open-weight class. Moonshot’s technical blog frames the model around two architectural claims: Kimi Delta Attention, an efficiency mechanism for the attention layer, and Attention Residuals, a change to how signal propagates through the stack. Both are pitched as the reason a model this large stays trainable and servable at a cost Moonshot’s size can absorb.
On openness, precision matters, because the launch coverage flattened it. These are open weights, not an open-source project in the strict sense — you get the checkpoint, not the training data or the full recipe. Downloadable and self-hostable is a weaker claim than reproducible, but it is worlds apart from the API-only posture of the US frontier. The Next Web went with the flat superlative — “the world’s largest open AI model” — and on the raw parameter count, that is defensible. It is also exactly the kind of marketing-grade claim this publication exists to unbundle.
Because “largest open model” measures size, not capability, and the two have never been the same thing. A 2.8T MoE with a small active fraction can be enormous on paper and merely competitive in practice. The honest version of the headline is narrower: for the first time, a model in the 3-trillion-parameter class exists as a file anyone can pull, and it got there before any US lab published a comparable open artifact. The open tier’s ceiling just moved up a full order of scale. Whether the capability moved with it is the question the parameter count is designed to let you skip.
The number that isn’t the parameter count
Here is the pairing again, because it is the whole story: a reported $30 billion raise, and a decision to open-source the crown jewel.
Moonshot is not the first open-weight Chinese lab to be priced like a scarce asset while giving its best work away. Put the raise next to the only close comparison the corpus can verify, DeepSeek’s first external round, and the pattern is the point.
| Lab | Reported figure | Weights | Round detail |
|---|---|---|---|
| Moonshot AI | ~$30B valuation | Open | Reported raise around the K3 launch |
| DeepSeek | $52–59B valuation | Open | ~$7.4B first external round (Tencent, CATL) |
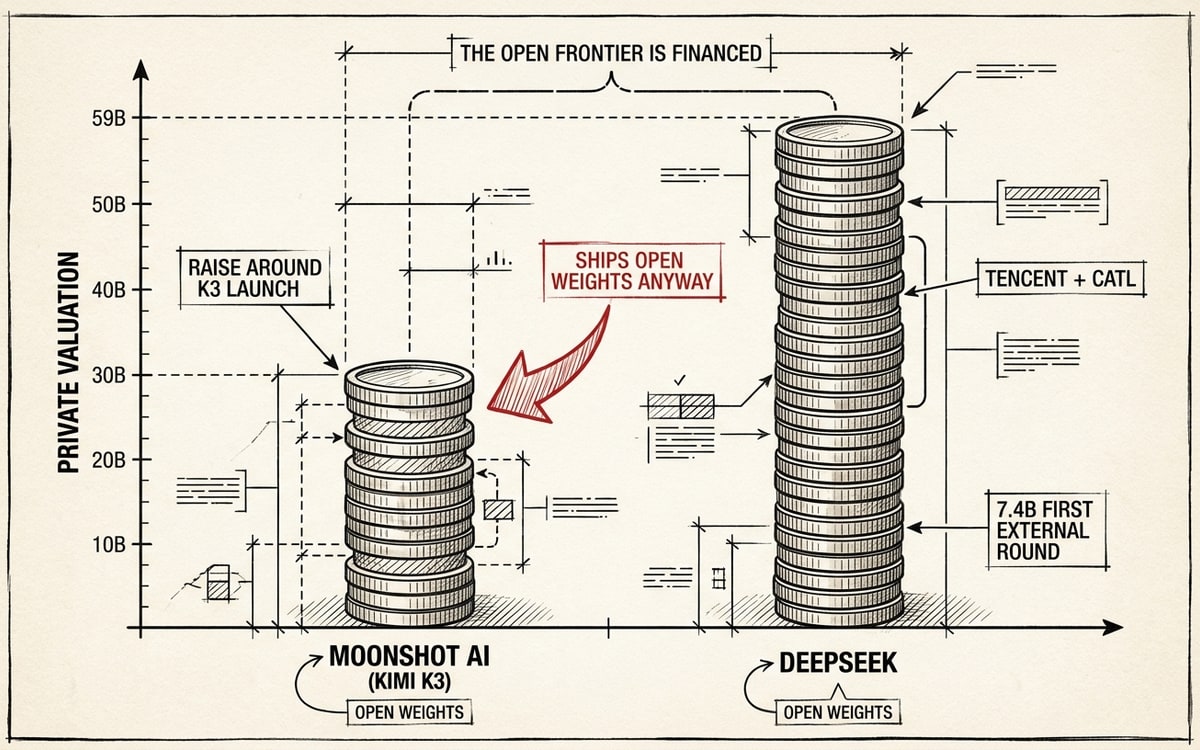
Two open-weight labs, both carrying frontier-scale valuations. Scarcity is what a valuation like that is supposed to buy. Neither is selling it.
A frontier lab’s valuation is, in the crudest terms, a bet on defensible scarcity — that the model is hard to reproduce, expensive to serve, and therefore ownable. OpenAI and Anthropic are priced on precisely that logic, which is why their best models ship behind an API and, increasingly, behind a government-shaped release gate. Access is the moat, and the whole apparatus of the closed frontier assumes that giving the model away would be lighting it on fire.
Moonshot lit it on purpose and is asking for $30 billion anyway. There are two coherent readings of that, and they are not mutually exclusive.
The first is that open weights are the moat — a distribution play. A Chinese lab cannot out-access OpenAI inside the markets that matter to Western enterprise buyers; the export and licensing regime sees to that. What it can do is make its model the default substrate — the thing every downstream builder, every inference host, every fine-tuner reaches for because it is free, capable enough, and un-gateable. Ubiquity is a different kind of leverage than scarcity, and for a challenger it may be the only kind available. In that reading, the $30 billion is a bet on becoming the default layer of the frontier: valuable because everyone runs it, not because no one else can.
The second reading is less flattering. Open-sourcing the crown jewel is what you do when the crown jewel isn’t quite the crown — when you can’t charge frontier prices for frontier access because you’re not reliably the frontier, so you convert the model into a marketing instrument and let the release itself justify the raise. The weights become the pitch deck. In this version, “open” is downstream of “can’t sell it closed.”
The uncomfortable truth is that both readings predict the same move. That is why the move tells you less than it seems to, and why the applause was premature. A company can open-source its best model because open is the winning strategy, or because closed was never on the table — and from the outside, on release day, the two look identical.
It still trails, and that is the tell
The claim that would settle it — that K3 is simply the best model, open or closed — is one Moonshot does not make. On its own blog’s comparison tables, K3 lands ahead of the open-weight field and behind the strongest closed models on the hardest reasoning and agentic suites. Scientific American framed the release as a rise, not a coronation, and that framing is correct. K3 is the new ceiling of the open tier. It is not the new frontier.
The sources support specs and a directional standing, not a clean numeric leaderboard, so that is what the table shows, with “n/d” wherever the number is not disclosed.
| Model | Params (total / active) | Context | Openness | Standing on hard reasoning |
|---|---|---|---|---|
| Kimi K3 | 2.8T / n/d | 1M tokens | Open weights | Trails the closed frontier (per Moonshot’s own tables) |
| Opus 5 | n/d / n/d | n/d | Closed, API-only | Leads (repeatedly rated above K3 on hard coding and reasoning) |
| Fable 5 | n/d / n/d | n/d | Closed, API-only | Competitive (K3 wins some frontend tasks, loses others) |
| GLM-5.2 | n/d / n/d | n/d | Open weights | Competitive (peer open model, strong on coding) |
| Qwen 3.8 Max | n/d / n/d | n/d | Open weights | Competitive (peer open model) |
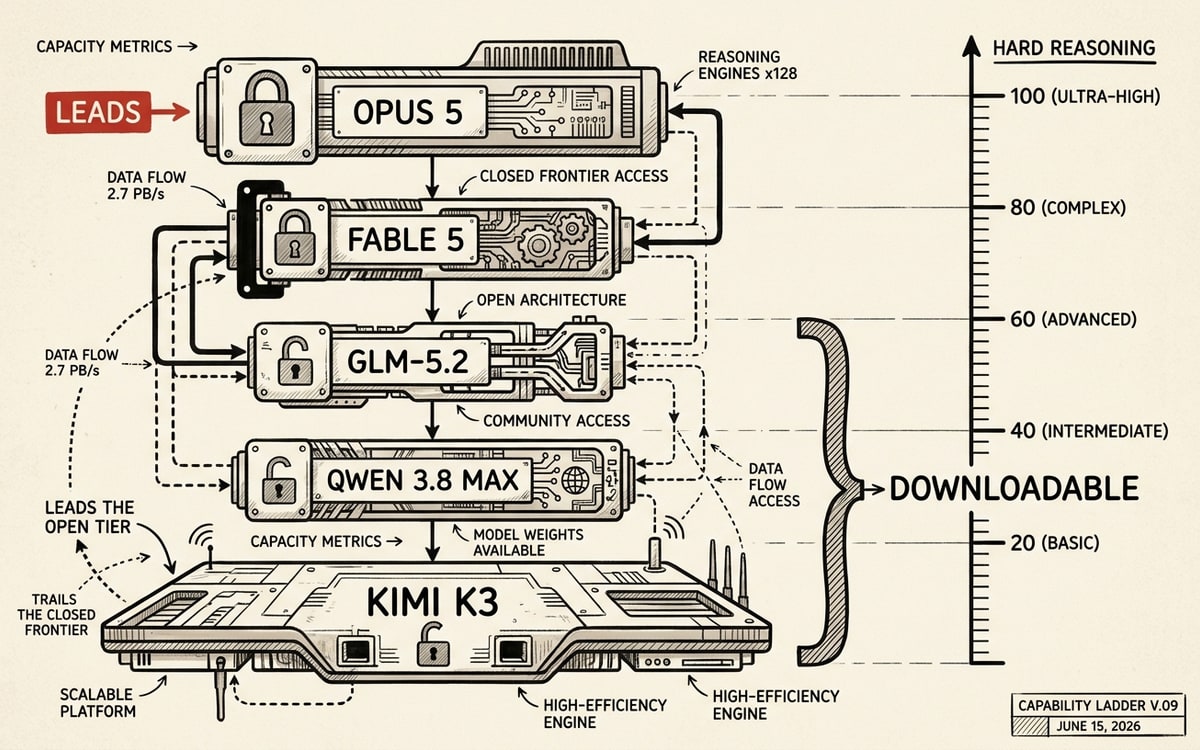
The disclosed specs run in K3’s favor (nothing public matches 2.8T open weights at a 1M context), and the qualitative column runs against it: on the reasoning and agentic work that closed labs charge for, K3 is competitive with its open peers and a step behind Opus-class models. Scale moved. The hard-benchmark lead did not.
That gap is the one to watch, because of where it started. Our June 24 analysis put the open-weight lag at roughly a quarter-year and shrinking. K3 does something that number didn’t anticipate: at the level of raw scale, the open tier now leads. No US lab has published open weights at 3T-class. On the dimension of “how big a model can you download,” the lag isn’t three months — it’s inverted. On the dimension that pays the bills — reasoning, reliable agentic execution — the closed frontier still holds a lead measured in weeks.
This is the pattern worth naming. The open tier is no longer trailing the frontier down a single track at a fixed distance. It is going wide and large in the open while the closed labs go deep and quiet — Moonshot optimizing for reach, the incumbents for a lead they can charge for. K3 trailing on the hard benchmarks isn’t a failure of the open thesis. It is the open thesis — good enough, everywhere, now — running exactly as designed.
The provenance question, handled honestly
No frontier-adjacent Chinese release survives its first week without the distillation accusation — the charge that the model was trained on outputs siphoned from GPT or Claude, making its capability borrowed rather than built. It surfaced for K3 too, and the Interconnects recap treats it with care: on release, there was no way to know from the outside whether any distillation occurred, and the charge is easy to make and hard to prove either direction.
What is worth flagging is the discipline the accusation demands and rarely gets. “It was distilled” is a capability claim dressed as a provenance claim — it lets a skeptic dismiss a benchmark without engaging it. The correct posture is the one we held for LongCat’s domestic-chip claim: the company’s assertions about how the model was built are assertions until someone independently checks them, and the burden runs both ways. Moonshot says K3 is a new architecture trained on its own stack; absent evidence, that is neither proven nor disproven. The interesting fact — that a 3T-class model is now downloadable — is true regardless of how it was built.
The discourse ran on demos, not benchmarks
The discourse after release is where the marketing claim and the market’s read diverge most, and the divergence is itself the signal. The conversation was not, mostly, about the 2.8-trillion-parameter headline. It was about what people could make: 3D worlds from a sentence, playable games from a prompt, Blender scenes wired through MCP. Demo-driven, not benchmark-driven. For a model sold on scale, the public verdict came almost entirely in screen recordings, and the engagement was modest — the loudest Kimi-specific posts landed in the low hundreds of likes, not the thousands.
The strategic read that traveled best came from an old-China-tech hand:
Baseten, Ollama & others will all be adding more compute to not only host GLM-5.2 & Kimi K3, but also all their derivatives & for fine-tuning them. In the future, we will see many small distilled models from these guys. This is what Dario is afraid of. Good enough & cheap LLM.
That is the open thesis stated by the market rather than the vendor: the value isn’t K3 as a product, it’s K3 as a substrate for a thousand cheaper derivatives. Against it ran a more skeptical current — that whatever K3 was, the next closed release would eclipse it:
Kimi K3 and Qwen 3.8 Max Preview genuinely look like bots next to this.
— @OmedVibeCodes Jul 24, on an incoming closed model (178 likes, ~31K impressions)
And then the tell. The distillation accusation showed up — but inverted, as a joke:
China should sanction the US given that Anthropic obviously distilled Opus 5 from Kimi K3.
— @itsoksmit Jul 24
It is a throwaway line with modest reach, but the direction is the point. Six months ago the reflex was “the Chinese model copied ours.” Here it flipped to sarcasm the other way — a small sign that the open tier is good enough that “who copied whom” no longer has an obvious answer. The most sweeping claim came from a researcher watching the reaction, not the benchmark:
Kimi K3 may have had an even greater impact than DeepSeek R1. Few model releases have triggered this level of reaction. Closed frontier AI labs are lobbying against open weights, while researchers, developers, and much of [the field embrace them].
— @HCSolakoglu Jul 24
That one barely registered — three likes — which is its own honest data point. The DeepSeek-R1 comparison is the frame the open camp wants; the market, for now, was too busy generating voxel coliseums to ratify it.
The ceiling that moved before the floor did
The Deep Feed’s position: we read the $30B-beside-open-weights pairing as the second story, not the first. A lab that could reliably sell frontier access closed would not open-source the crown jewel to justify a raise. Kimi K3 is a genuine ceiling for the open tier and a marketing instrument for Moonshot at the same time, and the applause that treated it as a coronation skipped the sentence Moonshot itself declines to write: that it is the best model, period.
Kimi K3 is the first 3-trillion-parameter model you can download, and that sentence will matter for years regardless of how it benchmarks this quarter. The open tier now has a ceiling where the closed frontier has a wall. But the release is not the clean triumph the parameter count invites, and the $30 billion beside it is the reason to stay skeptical.
A lab that gives away its best model is either building the most valuable distribution position in AI or admitting it cannot sell what it makes. Moonshot has arranged things so that both stories fund the same raise. The parameter count is the part they want you to look at. The valuation is the part that tells you which story was true — and that number won’t resolve on the day the weights drop. It resolves the first quarter Moonshot has to show revenue from a model the whole internet already owns for free.