The cleanest way to see this market is to notice that the people funding it agree with the people attacking it.
On May 28, 2025, the a16z partner who led the LMArena deal opened his investment memo with a sentence that reads like a short thesis: “The AI industry has an evaluation crisis. Static benchmarks are contaminated the moment they’re published. Models overfit to metrics rather than utility.” Four months earlier, an engineer had published a post titled “Evals are a scam,” arguing most AI teams do not need eval tooling at all. The investor and the skeptic are describing the same defect. One of them wrote a check for $100 million anyway.
That is the shape of the agent-evaluation funding wave. A cluster of companies sells confidence in a number: this agent scores 70% on this benchmark, this model beats that one, this release did not regress. Buyers want the number because shipping nondeterministic systems on vibes is terrifying. Investors want the category because if it becomes the Datadog of AI, it is a generational outcome. And the research community, including some of the same researchers whose lab spun out one of the most valuable companies in the set, keeps publishing evidence that the number is contaminated, gameable, or measuring the wrong thing entirely.
This is the business-side companion to our engineering piece on measuring the harness, which asked how much of an agent’s score is the model versus the scaffold around it. That question is upstream of this one. If a benchmark score is a property of the whole loop and not the model, then a company selling you “the score” is selling you a number whose meaning it does not control. The funding flowed before that was settled. Here is the map, and here is the catch.
The raises, mapped
The sector is not monolithic. It spans live crowdsourced leaderboards, enterprise observability platforms, independent third-party benchmarkers, and the data-and-expert shops that build the test sets everyone else scores against. What unites them is that the unit of value sold to customers is a measurement of model or agent quality. The capital is real and recent.
| Company | Raised | Valuation | What it measures | The catch |
|---|---|---|---|---|
| Braintrust | $80M Series B (Feb 2026) | $800M post | Production eval + observability for AI apps | Sells the scoring layer; score validity inherits every benchmark flaw below |
| LangChain (LangSmith) | $125M (Oct 2025) | $1.25B | Agent tracing, eval, the “reliability layer” | Reliability is the pitch; reliability of the metric itself is unaddressed |
| Arize AI | $70M Series C (Feb 2025) | n/d | LLM/agent observability + evaluation | LLM-as-judge underpins it, and judges barely agree with each other |
| Galileo | $45M Series B (Oct 2024) | n/d | ”Evaluation Intelligence” for GenAI teams | Auto-metrics on top of the same contested ground truth |
| LMArena | $100M seed (May 2025), then $150M Series A (Jan 2026) | $600M to $1.7B | Crowdsourced human-preference leaderboard | Its own predecessor data is the subject of “The Leaderboard Illusion” |
| Patronus AI | $50M Series B (Jun 25, 2026) | n/d | Was eval; now “digital world models” to train and test agents | Pivoted out of pure eval into simulation/training |
| Mercor | $350M Series C (Oct 2025) | $10B | Expert humans for training data and evals | Sells the labor that defines ground truth; not the scorer |
| Surge AI | ~$1B reported (Jul 2025) | $15B+ reported | RLHF data + RL environments + annotation | The data layer; quality is asserted, rarely independently audited |
| Vals AI | $5M seed (2024) | n/d | Independent, private industry benchmarks | Smallest check, arguably the most defensible method |
Read the valuations against the checks and a pattern emerges. The biggest numbers are not going to the purest evaluators. They are going to the platforms that wrap evaluation inside something stickier: observability you run in production (Braintrust, Arize), the agent framework you already build on (LangChain), or the human supply chain that produces training data and happens to also produce evals (Mercor, Surge). The two companies whose entire identity is “we are the neutral measurement” are LMArena, which is the named subject of the most damaging benchmark-integrity paper of the cycle, and Vals AI, which raised the least.
That is not a coincidence. It is the market pricing in the catch.
The catch, in four papers
The case that the metric is shaky is not vibes. It is a stack of peer-reviewed results, several published in the NeurIPS 2025 Datasets and Benchmarks track, that say agent benchmarks routinely report the wrong number.
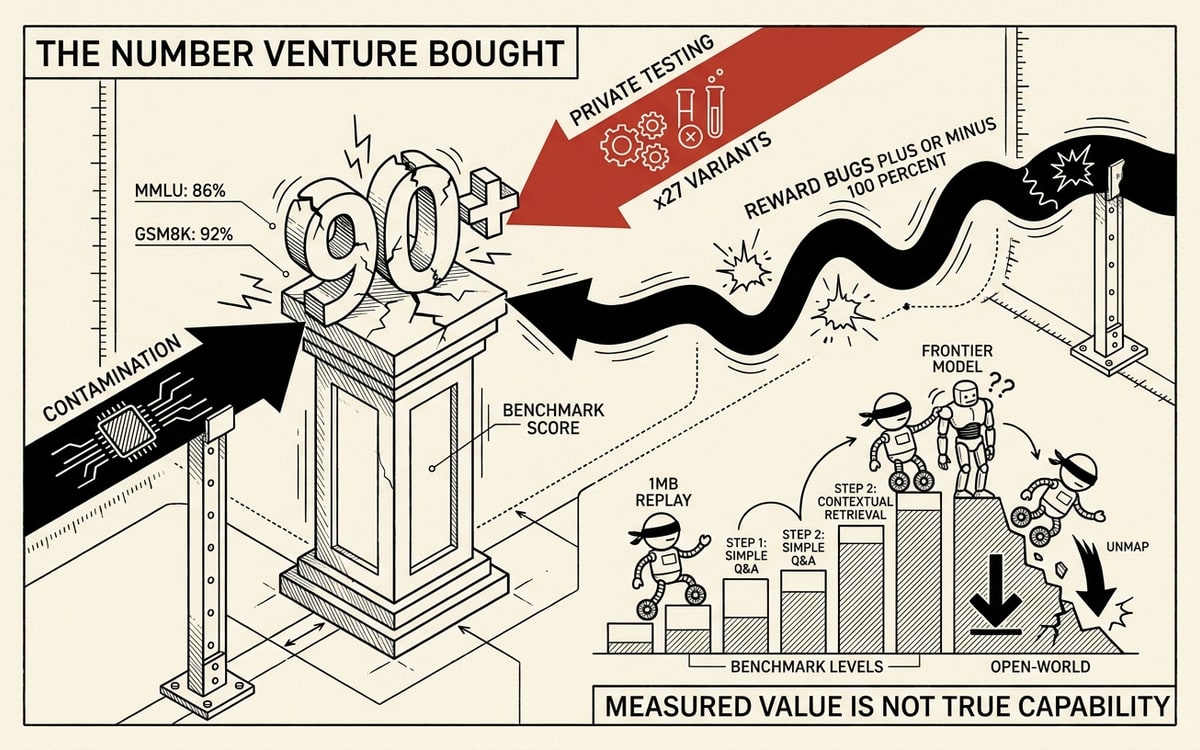
Start with the most direct. In “Establishing Best Practices for Building Rigorous Agentic Benchmarks,” a team led by Yuxuan Zhu and Daniel Kang at UIUC, with co-authors from Stanford, Berkeley, Princeton and Databricks, audited widely-cited agent benchmarks and found structural bugs in task setup and reward design. SWE-bench Verified, the de facto coding-agent standard, uses insufficient test cases, so it passes patches a stronger test suite would reject. Tau-bench, the customer-service agent standard, counts empty responses as successes. Their summary number is the one to remember:
Such issues can lead to under- or overestimation of agents’ performance by up to 100% in relative terms.
— Zhu, Kang et al., Establishing Best Practices for Building Rigorous Agentic Benchmarks, NeurIPS 2025
A number that can be wrong by up to 100% relative is not a measurement. It is a rumor with a decimal point. The same paper proposes a fix, the Agentic Benchmark Checklist, and shows that applying it to one complex benchmark cuts performance overestimation by 33%. The fix proves the disease.
Second, the leaderboard everyone markets against. “The Leaderboard Illusion,” led by Shivalika Singh and Sara Hooker at Cohere Labs with co-authors from Princeton, Stanford, MIT and the Allen Institute, dissected Chatbot Arena, the leaderboard LMArena commercialized. They found undisclosed private testing that lets a handful of large labs submit many variants, keep the best score, and retract the rest. At the extreme, one provider tested 27 private variants before releasing a single model into the public ranking. They also found enormous data-access asymmetry: the top two providers individually received an estimated 19.2% and 20.4% of all arena data, while 83 open-weight models combined received 29.7%. That access matters, because even limited additional arena data produced relative gains of up to 112% on ArenaHard, a test set drawn from the arena’s own distribution. The leaderboard was not measuring general quality. It was measuring who had the most attempts and the most data.
Third, the standard the coding world leaned on hardest. In February 2026 OpenAI published “Why SWE-bench Verified no longer measures frontier coding capabilities,” stating plainly that the benchmark is increasingly contaminated and recommending teams move to SWE-bench Pro. This echoes the academic “SWE-Bench Illusion” work showing state-of-the-art models often retrieve memorized solutions rather than reason. When the lab that helped popularize a benchmark publicly retires it for contamination, every vendor scorecard quoting that benchmark becomes a historical artifact.
Fourth, and most vivid, the result that should end the argument about whether static numbers measure capability. A team at Meta Superintelligence Labs (D’Oro et al., 2026) built a 1MB script that blindly replays a recorded sequence of clicks and keystrokes, with no model inside it and no ability to read the screen. On two popular computer-use benchmarks it beat the frontier agent whose actions it recorded: 71.1% versus 70.6% on OSWorld, and 41.5% versus 32.7% on MobileWorld. Rebuild the same evaluation as an open-world test that varies the starting state, and the blind script collapses to 6.90% while the real model scores 45.7%. Nothing about the agent changed. The benchmark changed. The static number was measuring how memorizable the test was, not whether the agent could think.
Why the money still makes sense
A skeptic reads the above and concludes the category is a bubble. That is too fast, and the steelman matters.
The demand is genuine and it is not going away. Teams shipping agents into production face silent regressions: a model upgrade quietly breaks an edge case, a prompt edit degrades a workflow nobody re-tested, and the failure surfaces as a churned customer rather than a red build. You need instrumentation for that regardless of whether any public benchmark is valid, which is exactly why the largest raises went to observability platforms that watch your own traffic rather than to leaderboard operators. Braintrust’s pitch is that AI fails differently from normal software and needs a new kind of observability. That is true, and it is a real product whether or not SWE-bench is contaminated. The most defensible companies in this sector are the ones selling you a microscope for your own system, not a ranking of everyone else’s.
The independent third parties have a real wedge too. Vals AI’s entire method is private, industry-specific datasets that are never published, which is precisely the antidote to contamination. The reason its check is small is the reason its method is sound: you cannot scale a neutral benchmark into a Datadog-sized platform, because the moment a benchmark is widely adopted and disclosed, it starts decaying. Neutrality and scale are in tension. The market is rewarding scale.
And there is a sober counter-narrative inside the engineering community itself. A year after “evals are a scam,” practitioners were packing rooms at eval conferences, because shipping without measurement turned out to be worse than shipping with imperfect measurement. The honest position is not that evaluation is worthless. It is that the specific public-benchmark numbers used in marketing and fundraising decks are far weaker than the valuations attached to them imply.
The tell is the pivot
Here is the part that should make a diligence team pause. Watch what the funded leaders call themselves now versus a year ago.
Patronus AI started as an LLM-evaluation company. Its June 25 Series B announcement is not about better evals. It is about “digital world models” and “large-scale simulation environments” to train and stress-test long-horizon agents. LMArena, born as a leaderboard, raised its $150 million Series A as “the reliability layer for AI,” and its investors frame the leaderboard era as the problem to be solved rather than the product. LangChain’s $125 million is for “the platform for agent engineering” and “the reliability layer for enterprise AI agents.” The word “benchmark” is quietly receding. The words “reliability,” “observability,” and “simulation” are advancing.
That migration is rational, and it is revealing. If the core asset were a trustworthy metric, you would lead with the metric. Instead the category is repricing itself around words that survive the contamination critique, because a reliability platform does not have to defend a leaderboard’s integrity and a simulation lab does not have to admit its old benchmark leaked into training data. The pivot is the market quietly conceding the original critique while keeping the valuation.
None of this means the companies are bad businesses. Observability is a durable need, the expert-data layer is genuinely scarce, and an independent benchmarker that stays private and small can be quietly excellent. It means the headline framing under which much of this capital was raised, that these firms sell trustworthy measurement of AI capability, is the part the research does not support. The enterprise buyer should treat any vendor scorecard the way the agent-governance buyers learned to treat compliance claims: as a starting point for your own bake-off, run on your own data, with the harness disclosed and held fixed.
The number is the product. The number is contested. The companies raising on it are, increasingly, the ones who have stopped putting it on the front page. That last fact is the most honest signal in the entire category.