Three weeks ago we argued that the open-weight coding frontier had caught Claude, and that it spoke Mandarin. The honest read then was that the gap was real and small on independent leaderboards, but that the marquee “we beat the frontier” coding numbers were mostly the labs grading their own homework. Coding is the easy case to celebrate, because a passing test is a passing test. Reasoning is harder to fake and harder to argue about, which is exactly why the more interesting question is whether the same convergence shows up on general reasoning and agentic evals.
As of mid-June 2026, it does. And this time the headline number is not a self-reported benchmark. It is a measurement of time.
The gap is 3.4 months, and someone graphed it
On June 16, Z.ai (formerly Zhipu) released GLM-5.2 to open weights under an MIT license. Within days, Artificial Analysis, the most-cited independent evaluator, made it official: GLM-5.2 is the leading open-weight model on the Intelligence Index v4.1, scoring 51, ahead of MiniMax-M3 (44), DeepSeek V4 Pro (44) and Kimi K2.6 (43). Two days later, a milestone that has nothing to do with China-vs-US framing and everything to do with where the floor now sits: GLM-5.2 became the first open-weight model to rank ahead of every Google model on that index.
Points are slippery across index versions. The more durable number is lag. An independent analysis scraped from Artificial Analysis’s open-source leaderboard plots every open-weight model that ever pushed the open frontier against the date a proprietary model first reached the same Intelligence Index. The result is the cleanest single chart of this entire story.
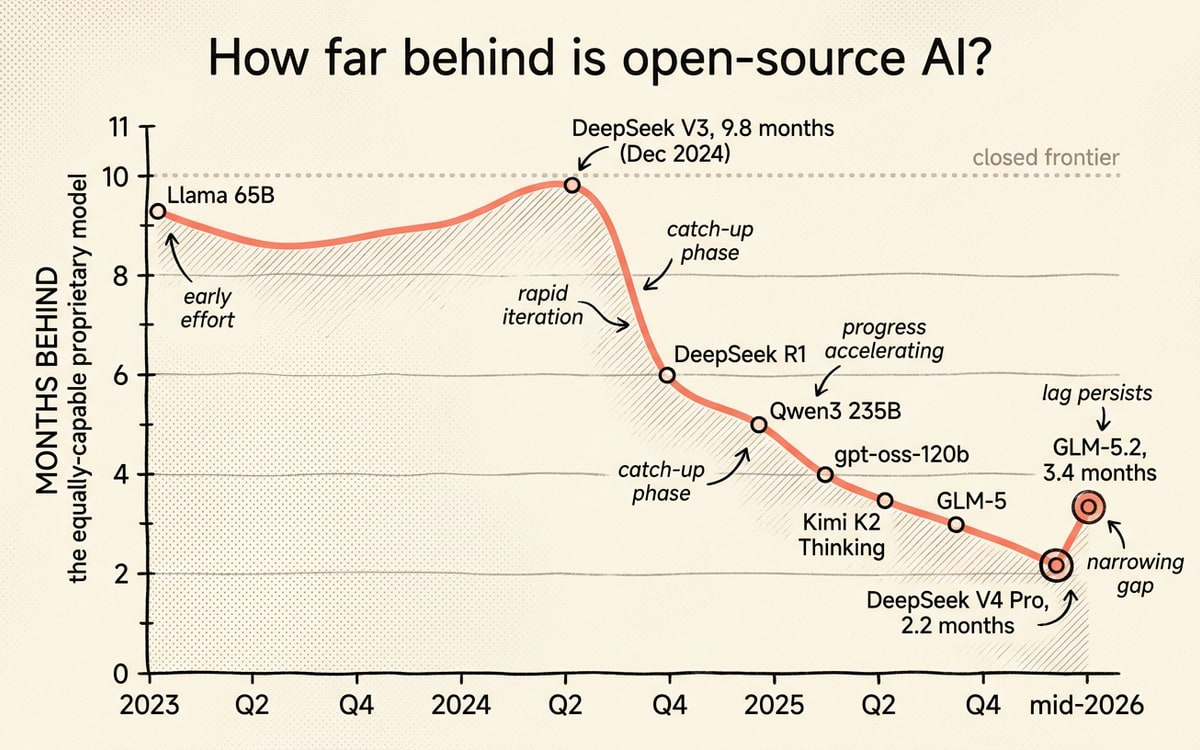
The shape is the argument. The gap peaked near 10 months around DeepSeek V3 in December 2024 and has since tightened to roughly 2 to 3.5 months. GLM-5.2 (Intelligence Index 51) matches the capability GPT-5.4 reached 3.4 months earlier. DeepSeek V4 Pro, released in April, set the record at 2.2 months, matching Claude Sonnet 4.6 from February. For context, eighteen months ago the same open frontier was a model that matched Claude 3 Opus, a model that was already nine and a half months old.
That is the headline of 2026 in one sentence: the reasoning lead the closed labs owned outright has compressed from most of a year to about a quarter of one.
Reasoning, not just coding
The skeptic’s first move is to say that GLM-5.2 is a coding model wearing a reasoning costume, and that the index is flattered by agentic coding benchmarks. The v4.1 index did reweight toward agentic workloads in June. But the GLM-5.2 gains are concentrated precisely in the hard scientific-reasoning evals that are not coding.
Per Artificial Analysis, GLM-5.2 improved Humanity’s Last Exam by 12 points to 40%, SciCode by 7 points to 50%, and CritPt by 16 points to 21%. On GDPval-AA, a long-horizon knowledge-work benchmark, it reached 1524, comparable to proprietary GPT-5.5 at 1514. Its AA-Omniscience accuracy rose to 25.1% while its hallucination rate fell to 28.1%, a number worth holding onto, because reliability under uncertainty is where the open tier has historically been weakest.
DeepSeek V4 Pro fills in the rest of the reasoning picture. The 1.6-trillion-parameter MoE (49B active, 1M context, MIT) posts vendor-reported GPQA Diamond of 90.1% and LiveCodeBench of 93.5%, and Artificial Analysis independently ranks it third among open models on the index. Kimi K2.6, a trillion-parameter vision-language model from Moonshot, sits right behind it and “falls just behind top closed models” in The Batch’s framing. The pattern is no longer one lucky release. It is a cohort.
Here is the field as the independent index measures it, separated into open and closed, so the gap is legible at a glance:
| Model | Type | License | Intelligence Index v4.1 | Notable reasoning marks | Price (in/out per 1M) | OSS lag |
|---|---|---|---|---|---|---|
| Claude Fable 5 | Closed | Proprietary | 60 (top, now offline) | Launched #1; pulled June 12 | $10 / $50 | — |
| GPT-5.5 (xhigh) | Closed | Proprietary | ~55 | Frontier reasoning | $5 / $30 | — |
| Gemini 3.1 Pro | Closed | Proprietary | below GLM-5.2 on v4.1 | Strong GPQA | varies | — |
| GLM-5.2 | Open | MIT | 51 | HLE 40%, SciCode 50%, GDPval 1524 | $1.40 / $4.40 | 3.4 mo |
| DeepSeek V4 Pro | Open | MIT | 44 | GPQA 90.1%, LiveCodeBench 93.5% | $0.435 / $0.87 | 2.2 mo |
| MiniMax-M3 | Open | Open weights | 44 | 1M context, multimodal | sub-$1 tier | 3.4 mo |
| Kimi K2.6 | Open | Open weights | 43 | Just behind top closed | mid-tier | 2.4 mo |
The closed frontier still leads on raw capability: Claude Fable 5 launched at the top of the index, and on the absolute scale it sits roughly nine points above GLM-5.2. But two of those rows deserve an asterisk that cuts the other way. Fable 5, the model defining the absolute frontier, was pulled offline on June 12 under a US export-control directive, with Opus 4.8 as the fallback. The single best reasoning model in the world is, at the time of writing, one that nobody outside Anthropic can use. The single best reasoning model you can download and run forever is GLM-5.2. That is a strange inversion of the 2024 status quo, and it is the real story under the benchmark math.
The DeepSeek moment for agents
The qualitative read from people who run these models in harnesses, rather than on leaderboards, has shifted in the same direction. Nathan Lambert, who has spent a year arguing that open models live in perpetual catch-up, changed his framing for this one:
GLM-5.2 is the “DeepSeek moment” for agents. We enter a new world where the top end of agentic capabilities are available in open models.
— @natolambert, Jun 2026
His longer argument is that GLM-5.2 is the first open-weight model that simply works as a general agent inside a real coding harness, rather than topping a static benchmark and then falling apart in a multi-turn loop. That distinction matters more than any single eval, because the thing buyers actually deploy is the agent, not the score. When the most respected independent voice on open models calls it a threshold moment on par with DeepSeek R1, the burden of proof has shifted: the question is no longer “did open weights catch up on reasoning?” but “what is the catch?”
There are two, and both are real.
Catch one: cheap per token is not cheap per task
GLM-5.2’s pricing looks like a rout. At $1.40 input and $4.40 output per million tokens, it undercuts GPT-5.5 ($5/$30) and Claude Opus ($5/$25) by roughly a sixth on output. But the index data carries a quieter number that erases part of that advantage. Artificial Analysis measured GLM-5.2 burning 43,000 output tokens per Intelligence Index task, of which 37,000 is reasoning, well above GLM-5.1 (26k), MiniMax-M3 (24k), Kimi K2.6 (35k) and DeepSeek V4 Pro (37k).
A model that thinks three times as long to reach the same answer is not as cheap as its per-token sticker suggests once you multiply by the tokens it actually emits. For a single query the difference is invisible. For a production agent running thousands of long-horizon tasks a day, token-efficiency is the whole cost model, and it is the axis where the open tier still trades capability for verbosity. The MIT license removes the access barrier; it does not remove the inference bill, and at scale the inference bill is most of the cost. The honest framing is that the open tier has caught the closed frontier on capability per task while still lagging on capability per token.
Catch two: the jurisdiction the benchmark cannot see
The second catch is the one no eval scores, and it is the through-line from the coding piece. Four of the five leading open reasoning models, GLM-5.2, DeepSeek V4 Pro, MiniMax-M3 and Kimi K2.6, are Chinese. The open-weight reasoning crown is not a US asset; it is a Chinese one, and it arrives wrapped in the same structural risk we have been tracking all month.
The colder counterweight remains the US government’s own evaluation. In May, NIST’s Center for AI Standards and Innovation judged DeepSeek V4 Pro to lag the frontier by about 8 months on its aggregate-capability scale, a number that sits awkwardly next to the 2.2-month figure from the index-matched lag chart. Both can be true: the index measures aggregate Intelligence at a given capability level, while CAISI weights a different basket including refusal behavior, security, and the high-stakes domains where a 28% hallucination rate is still 28% too high. The 2.2 months is the optimistic frame. The 8 months is the procurement frame. The gap between those two numbers is, almost exactly, the gap between what a benchmark rewards and what a regulated enterprise will sign.
And the jurisdiction risk does not require a demonstrated incident to be real. Self-hosting the MIT weights mitigates it; routing through a Chinese API endpoint, the default path for most developers, does not. The same week GLM-5.2 took the open crown, the absolute frontier model was switched off by a government letter. Both events point at the same conclusion: in 2026, “which model is best” and “which model can I actually run, legally, on data I control” have become two different questions with two different answers.
Where this leaves the reasoning frontier
The contrarian position is not that the convergence is hype. It is measured, it is fast, and 3.4 months is the honest number for how far open weights now trail the closed reasoning frontier at a matched capability level, down from nearly ten months eighteen prior. On general reasoning and agentic evals, the open tier has done what it did on coding, except this time the proof is an independent time-series rather than a vendor’s slide.
The contrarian position is narrower: the points-gap is small and the time-gap is shrinking, but the decision-gap is not collapsing at the same rate. Token-inefficiency keeps the open tier from being as cheap as it looks where it matters most, at production scale. Jurisdiction keeps the regulated buyers contracting with the same Western labs they always did, even as one of those labs just had its best model turned off. The reasoning spec sheet has commoditized exactly the way the coding one did: a frontier-class, MIT-licensed, million-token reasoning model now costs a dollar-forty per million tokens and ships every few weeks. What stays scarce is verification you can trust and jurisdiction you can live with.
So the frontier got caught on reasoning, in the aggregate, on the independent index. The number that matters for the second half of 2026 is not the nine-point capability gap to a model nobody can run. It is the 3.4-month gap to one anybody can, and whether the buyers with the most to lose decide that a quarter-year behind, fully owned and fully auditable, beats a quarter-year ahead on an endpoint a government can switch off.