SuperServe’s landing page makes four promises, stacked in a row like a scoreboard: Firecracker hardware isolation, sub-200ms startup, a versioned filesystem, infinite session length. It is a clean pitch for a real problem. Agents need computers, those computers need to be isolated, fast, and cheap to leave idle, and most teams building agents would rather rent that substrate than operate it.
The scoreboard is also untested by the people reading it. A spec sheet is a claim a vendor makes about itself. Nobody clicks “get started” with a stopwatch and a list of edge cases.
So we did. Over roughly a week, we drove the live production API at api.superserve.ai through 24 numbered test phases and two SDK suites, about 356 automated assertions in total, all passing. We booted every system template and recorded what was actually installed. We measured boot times. We ran nine agent and coding runtimes inside sandboxes with real API keys. We executed a multi-agent swarm end to end and re-ran its output independently. We tried to break the egress firewall, the metadata limits, the pause/resume cycle, and the template builder. And we wrote down every place the substrate behaved differently from the scoreboard.
This is the field report. It is not a tutorial and it is not a review. It is the thing a spec sheet can never be: a record of what one agent runtime does when you push on every surface it exposes.
Why a field report is the only honest runtime evaluation
For two years the bottleneck in building with AI was the model. A weak model wrote code that did not compile, summaries that hallucinated, plans that fell apart. You evaluated a model and you were mostly done, because the model was where the risk lived.
That has changed, and we have argued the case at length elsewhere: the model is no longer the binding constraint. The environment the agent runs in is. An agent can now write a thousand lines of correct code and still fail to ship them, because shipping needs a place to run. It needs a filesystem, secrets, a network it can reach, a way to run the tests and try again, and a way to do all of that without the agent’s mistakes leaking into the host. That place is the runtime, and a whole category of companies now sells it. We mapped 23 of them in May. SuperServe was one row in that table.
Here is the problem with evaluating that category from the outside. Every vendor publishes the same shape of pitch: a hero number for cold-start latency, a word like “persistent” or “stateful” or “versioned,” an isolation primitive (Firecracker, gVisor, a container), and a code snippet that always works on the first try. The pitch is true in the sense that it is not false. It is also useless for a decision, because the things that actually determine whether you can build on a runtime are never on the landing page. What happens when a process you backgrounded outlives the call that spawned it? Does the file SDK throw a typed error or crash when you read a missing path? Does a deny-all egress rule also kill your DNS? Which of the eight templates actually has Python in it?
You cannot learn those things by reading. You learn them by driving. A field report (drive every surface, assert on the success signal, write down the failures) is not a nice-to-have supplement to the spec sheet. For infrastructure an agent will run unattended, it is the only evaluation that means anything.
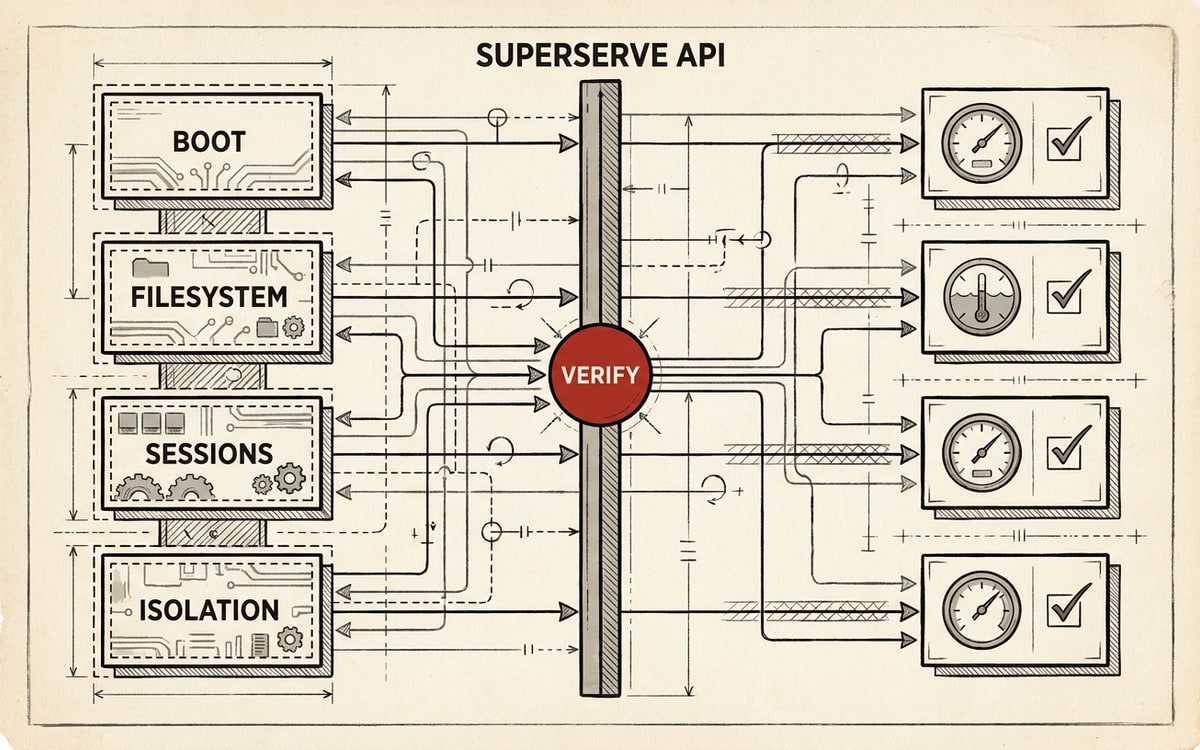
Everything below was verified against the live API and both official SDKs: @superserve/sdk for Node and superserve for Python, version 0.7.3 at time of testing. Where a claim rests on a measurement, the measurement is stated. Where the substrate diverged from the documentation, the divergence is named. No capability is asserted that did not produce a transcript.
What SuperServe is, precisely
SuperServe launched on February 6, 2026 as, in its own words, “a production hosting platform for AI agents… solving the gap between a working prototype and a production service.” The core is open source under Apache 2.0. The superserve-ai/superserve SDK repo carries a few hundred GitHub stars, and the underlying superserve-ai/sandbox Go control plane is public, with a visible commit history that includes a v2 API rework adding an internet toggle, hard timeouts, and immutable metadata, plus a lifecycle rearchitecture that lets sandboxes survive control-plane restarts. The names that recur in that history are Pavitra Bhalla, Amit Patil, and Jitendra Nirnejak. This is a real, actively engineered system, not a thin wrapper over someone else’s VMs.
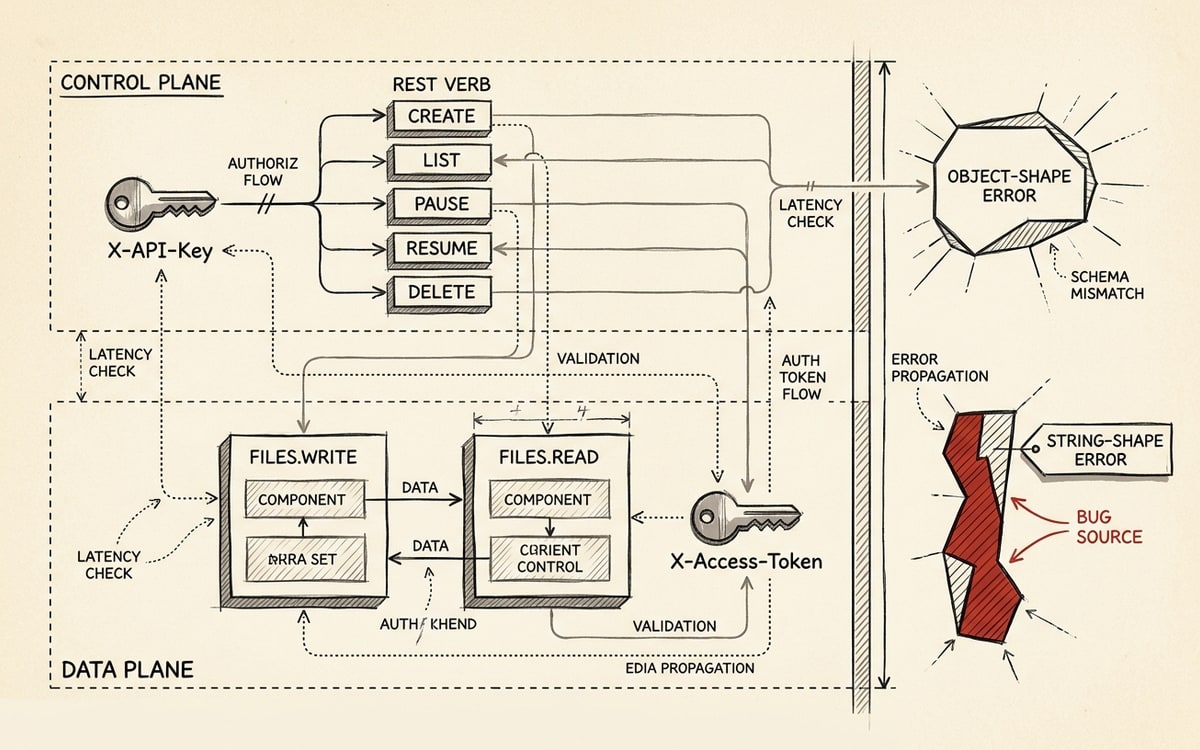
Architecturally, SuperServe splits cleanly into two planes, and understanding the split explains most of the API.
The control plane is a REST API at https://api.superserve.ai. It creates, lists, inspects, pauses, resumes, and destroys sandboxes and templates. It authenticates with a header, X-API-Key: <key>, and here is the first sharp edge: an Authorization: Bearer header, the thing every developer reaches for by reflex, is rejected with a 401. There is a GET /health endpoint that needs no auth and returns {"status":"ok","version":"0.1.0"}, which is the cheapest possible smoke test.
The data plane is separate and SDK-managed. It is how files move in and out of a running sandbox, and it authenticates with a different credential: an X-Access-Token that the control plane hands back when you create, activate, or resume a sandbox. You rarely touch the data plane directly; the SDK does it for you when you call files.write or files.read. But the split matters, because the two planes report errors in different shapes, and that difference is the root cause of one of the bugs we will get to.
Every sandbox is a real Firecracker MicroVM. We confirmed the same guest kernel, 4.14.336, on every template, which is the fingerprint of a shared Firecracker base. The default execution identity inside a fresh sandbox is root (uid 0) with a working directory of /home/user.
The eight templates: what is actually inside
A sandbox boots from a template, and SuperServe ships eight system templates. The spec sheet describes them in a sentence each. We booted all eight and ran the same probe script inside every one (identity, kernel, CPU, memory, disk, and the full toolchain inventory). The result is the table the documentation does not have:
| Template | vCPU / MiB / Disk | Base OS | Python | Node | Notable preinstalled |
|---|---|---|---|---|---|
superserve/base | 1 / 1024 / 4096 | Ubuntu 24.04.4 | none | none | git 2.43, curl, tini only |
superserve/python-3.11 | 1 / 1024 / 4096 | Debian 13 (trixie) | 3.11.15 | — | pip 24 |
superserve/node-22 | 1 / 1024 / 4096 | Debian 12 (bookworm) | — | v22.22.3 | npm 10.9.8 |
superserve/python-ml | 2 / 2048 / 4096 | Debian 13 | 3.11.15 | — | numpy, pandas, scipy, scikit-learn, matplotlib, jupyter, gcc 14 |
superserve/code-interpreter | 2 / 2048 / 8192 | Debian 13 | 3.11.15 | — | full JupyterLab 4.5, pillow, gcc/make |
superserve/claude-code | 2 / 2048 / 8192 | Ubuntu 24.04.4 | 3.12.3 | bundled | the Claude Code CLI 2.1.153 (a 239MB standalone binary), gcc/make |
superserve/hermes | 2 / 2048 / 8192 | Ubuntu 24.04.4 | embedded 3.11.15 | — | tmux, Hermes 0.14.0 |
superserve/openclaw | 2 / 2048 / 8192 | Ubuntu 24.04.4 | 3.12.3 | v24.15.0 | npm 11.12.1, tmux, OpenClaw 2026.5.18 |
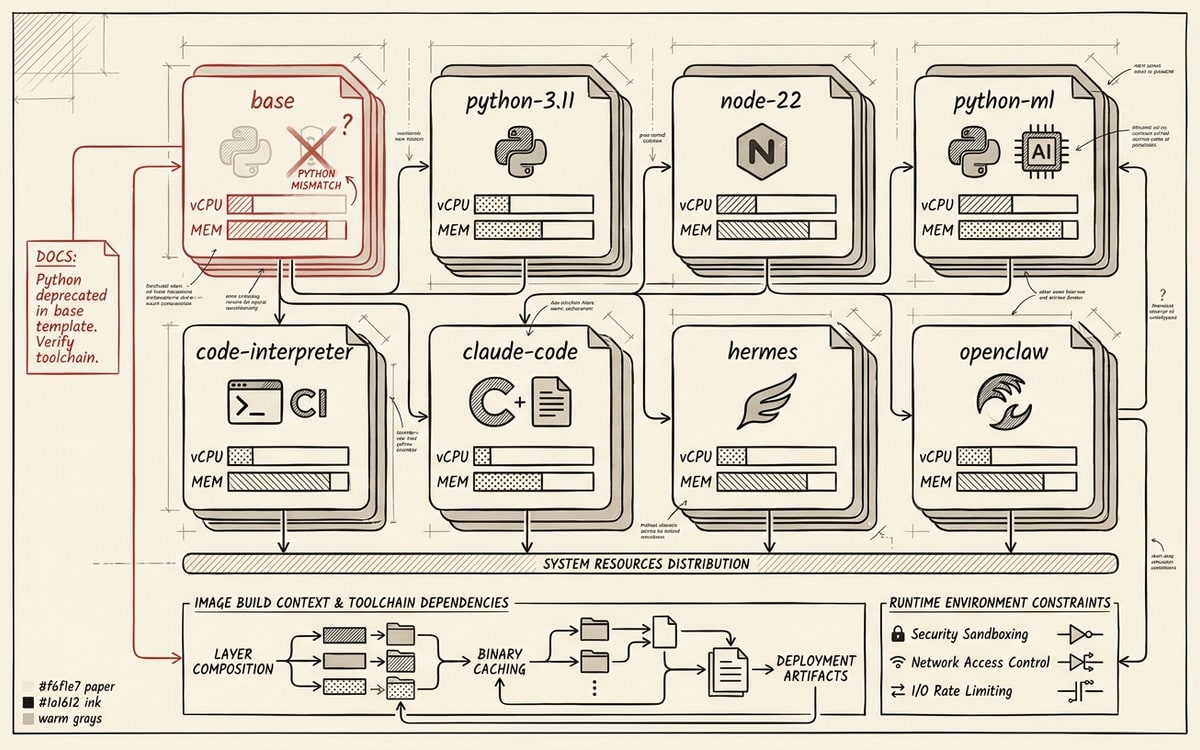
Two findings here are worth pulling out of the table. First, the VM shape (vCPU, memory, disk) is inherited from the template and cannot be overridden per sandbox. The snapshot dictates the geometry. If you need 2 vCPUs you pick a 2-vCPU template; you do not ask for a bigger box at create time. Second, and more pointedly: the introduction docs describe superserve/base as shipping “Python 3.12, Node.js 22, and common dev tools.” The production superserve/base we booted (twice, to be sure) has neither Python nor Node. It has git, curl, and tini, and nothing else. If you want a language runtime, you pick the template that names it. This is the kind of thing you only find by booting the box and running which python3.
The first promise: sub-200ms startup
Cold-start latency is the headline number for every sandbox vendor, because it is the one that feels like magic in a demo and the one that determines whether per-request sandboxing is viable in production. SuperServe advertises sub-200ms.
What we measured: server-side VM boot lands in the 300 to 500 millisecond range from the POST /sandboxes call to a usable VM. Wall-clock time as observed by a remote caller, including TLS negotiation and the round trip, was closer to a second.
Both of these can be true at once, and the gap is not a gotcha so much as a lesson in reading spec sheets. A sub-200ms startup claim is almost always measuring the narrowest possible slice: the Firecracker VM coming up, measured from inside the vendor’s own network, possibly with a warmed template overlay. The control-plane repo has an open line of work on exactly this, “overlay-mode templates for fast sandbox create,” which is the standard technique for pushing cold starts down. The number a developer experiences is the full round trip from wherever their code runs, through TLS, to a sandbox that will actually accept an exec. That number is real and it is excellent. Sub-second cold boots of genuinely isolated MicroVMs are the thing that makes per-tenant and per-request isolation economically sane. But it is not 200 milliseconds from your laptop, and you should size your timeouts for the second, not the marketing figure.
The honest framing: SuperServe’s boot speed is one of the genuinely delightful things about it. It is also not the number on the box, and the difference is the difference between a benchmark and a budget.
Creating a sandbox: the exact payload, and the trap in it
Here is the smallest thing that works, and the smallest thing that does not.
# Works. Note the field name.curl -X POST https://api.superserve.ai/sandboxes \ -H "X-API-Key: $SUPERSERVE_API_KEY" \ -H "Content-Type: application/json" \ -d '{ "name": "demo", "from_template": "superserve/python-3.11", "metadata": {"purpose": "field-report"}, "env_vars": {"OPENAI_API_KEY": "sk-..."} }'# Returns 201 Created, body includes id, status:"active", and an access_tokenThe trap: the template field is from_template, not template. Send template, or any other field the schema does not recognize, and you get a 400 bad_request with the message “Request body is not valid JSON or contains unknown fields.” The API is strict about unknown fields, which is good discipline and a five-minute debugging session the first time it bites you.
Note the env_vars in that payload. This is how you get secrets into a sandbox: you inject them at create time and they live in the VM’s environment, in memory, never written to a committed file. They are visible to every exec and every process those execs spawn, and, importantly, they survive a pause/resume cycle. Inject the model API key here and the agent runtimes inside the box pick it up automatically.
The full verified status-code map is worth committing to memory, because consistent HTTP semantics are one of the things that make an API pleasant to automate against:
| Operation | Status |
|---|---|
| create sandbox | 201 |
| get / list / exec / resume / activate | 200 |
| pause / patch / delete | 204 |
| create template / rebuild | 202 (async build) |
| missing resource | 404 not_found |
| validation failure | 400 bad_request |
| state conflict (resume an active box, double-pause, patch a paused network, delete a referenced template) | 409 conflict |
| bad / garbage / Bearer / empty key | 401 auth_failed |
The error codes are stable and machine-readable, which matters more than it sounds: you can branch on error.code instead of regex-matching error strings, and the codes mean the same thing across endpoints.
Running commands: the process-tree gotcha that breaks daemons
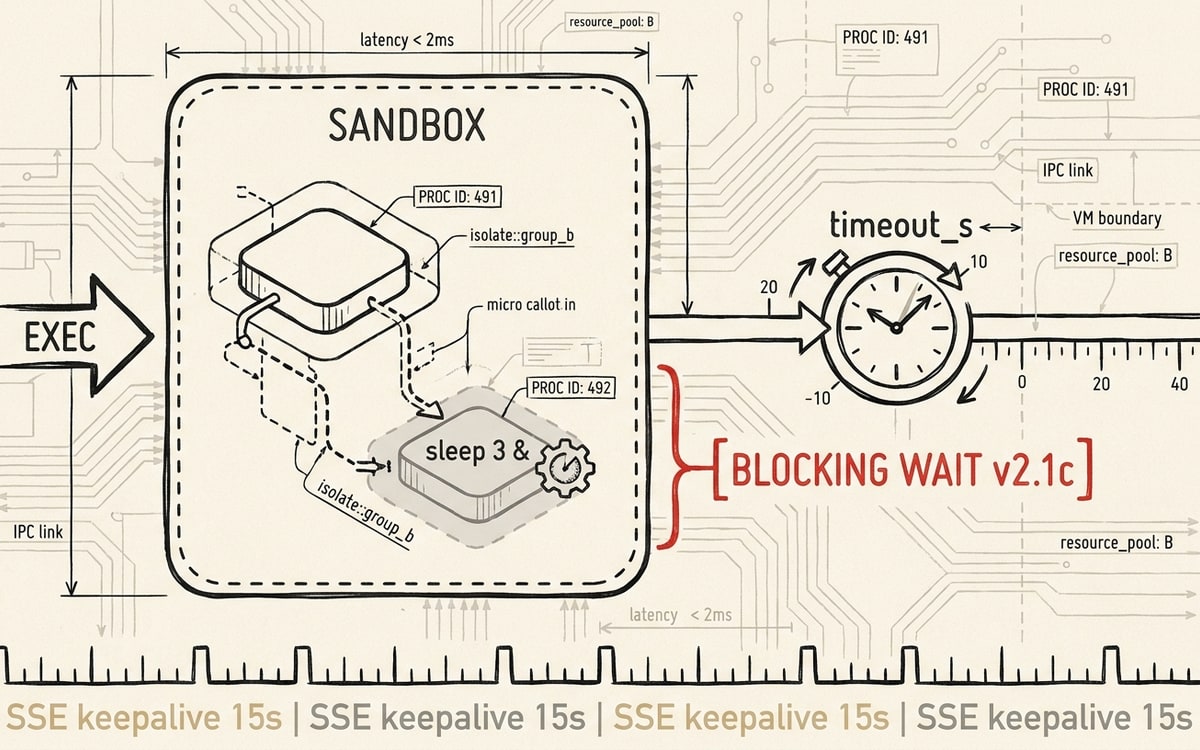
The control plane exposes two ways to run a command: POST /exec for a synchronous call that returns {stdout, stderr, exit_code}, and POST /exec/stream for a Server-Sent Events stream of the output as it happens.
Both behave the way you would hope. Sync exec captures stderr, propagates non-zero exit codes, honors a working_dir override and a per-call env map (which wins over the sandbox-level env_vars), and kills a runaway with timeout_s (exit code 124). The SSE stream emits ordered data: events with stdout and stderr chunks, sends a : keepalive comment every 15 seconds so proxies do not hang up, and finishes with a clean finished:true and the exit code.
There is one behavior that is not on any spec sheet and will absolutely bite anyone who tries to start a long-running server with exec:
execwaits for the entire process tree. A backgrounded child (sleep 3 &) keeps the call open until that child exits. Leftovers are reaped at the timeout.
This is correct, defensible behavior. It is also the opposite of what you want if you are trying to start a daemon. If you exec something like python -m http.server 8000 & expecting the call to return while the server keeps running, the call instead blocks until the server dies. The consequence is a rule:
Persistent processes must be started via a template
start_cmd, or inside a terminal multiplexer like tmux. Never as a one-shot backgroundedexec.
Get this wrong and you will spend an hour wondering why your exec call hangs. Get it right, by baking the server into the template’s start_cmd, and something genuinely impressive happens, which we will come to in the section on templates.
One more small mercy worth knowing: hitting /exec on a paused sandbox auto-resumes it. You do not have to manage the resume yourself for the common case of “I just want to run something.”
The second and third promises: versioned filesystem and infinite sessions
These two claims are really one mechanism, snapshots, viewed from two angles.
The filesystem moves over the data plane, through the SDK: files.write, files.read, files.readText. We round-tripped text, a 2KB all-byte-values binary, and a 3MB random binary, all byte-exact, with the 3MB transfer completing in about a third of a second. Nested paths are created automatically. The canonical pattern (write a CSV and a script in, exec the script, read the result out) works exactly as you would design it.
Infinite session length is the snapshot story, and it is the most important thing SuperServe does, so it is worth being precise about what survives and what does not.
When you pause a sandbox, the platform snapshots it: status flips to paused and a snapshot_id appears. When you resume, it restores from that snapshot, the status flips back to active, and you get a fresh access token. (activate is the idempotent “make sure this is running and give me a token” call.) The economic point is that a paused sandbox costs nothing to keep around: you stop paying while it is idle and resume it with its state intact when the next request arrives. For a per-user agent, this is the whole game. Idle users are nearly free, active users resume in well under a second.
What survives the cycle is unambiguous: disk files and env_vars are preserved. We verified both.
What requires care is live-process continuity, and this is the distinction the phrase “infinite sessions” papers over:
Only processes started via a template
start_cmdare captured live in the snapshot and resume already serving. Processes you launched ad hoc withexec &are not preserved as running processes. They are gone, and the disk state they wrote is what remains.
So “infinite session” does not mean “a VM that runs your process forever.” It means “a disk and memory image you can freeze and thaw indefinitely, where the documented mechanism for a persistent process, the template start_cmd, comes back alive.” If your mental model is “I started a server with exec and pause/resume will keep it running,” you will be surprised. If your model is “persistent things go in the start_cmd, ephemeral things write their state to disk,” everything behaves.
The fourth promise: isolation, and the egress firewall that fights DNS
Firecracker hardware isolation is the one claim that is simply, structurally true. Every sandbox is a separate MicroVM with its own kernel, which is the strongest isolation primitive in the category short of separate physical hardware. There is nothing to debunk here; it is the foundation the rest of the value rests on.
What is testable is the network control on top of that isolation, and it has the single most important gotcha in the entire platform.
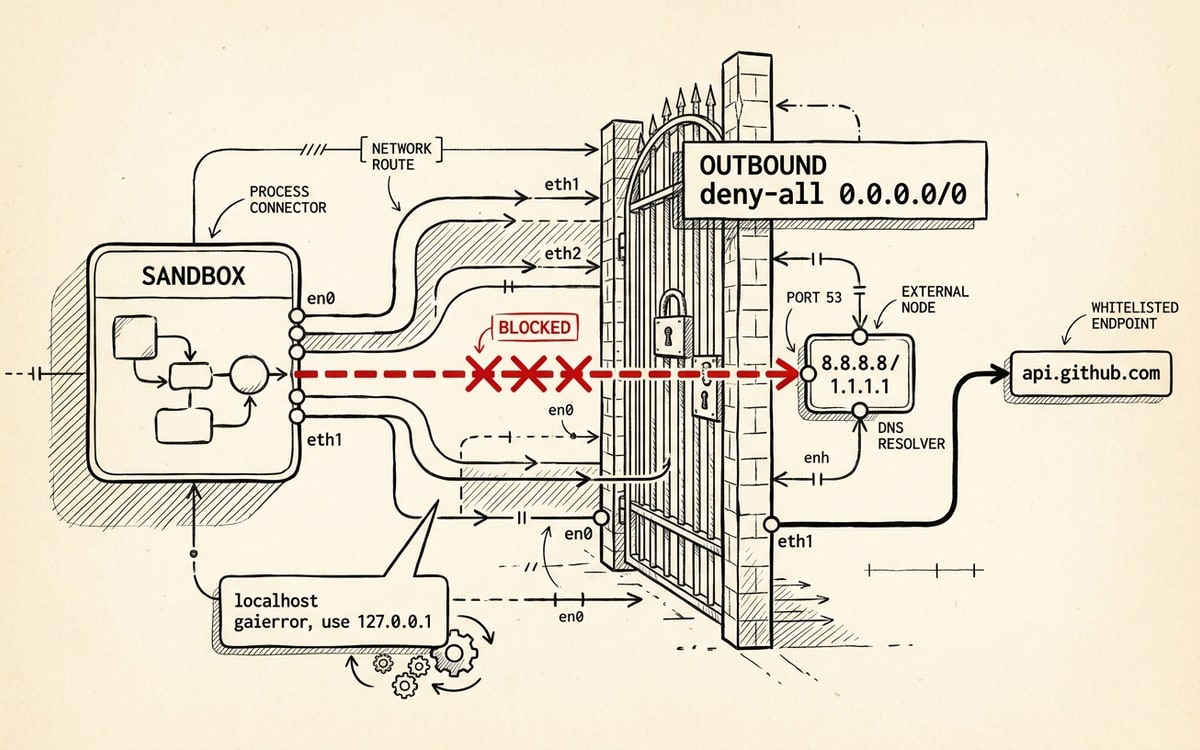
Egress is controlled with allow and deny rules. deny_out: ["0.0.0.0/0"] blocks all outbound traffic. Link-local and private ranges (169.254/16, 10/8, and so on) are always blocked regardless. CIDR allows work precisely: list 8.8.8.8/32 and it is reachable while 1.1.1.1 is not. Network rules can be patched on a live sandbox, but only an active one. Patching a paused sandbox’s network returns a 409.
Now the trap. Suppose you want a locked-down sandbox that can reach exactly one domain, say api.github.com, and nothing else. The intuitive rule is “deny all, then allow that domain.” It does not work, and the failure is silent and baffling, because:
Sandboxes resolve DNS through public resolvers.
1.1.1.1and8.8.8.8are in/etc/resolv.conf. Under a deny-all policy, DNS itself is blocked. The domain rule can never resolve, because the lookup that would resolve it is the first thing the firewall kills.
The fix is to also allow the resolver IPs: 1.1.1.1/32 and 8.8.8.8/32. With those open, domain allow-listing works as designed. This is, in retrospect, exactly why SuperServe’s own documentation examples list 8.8.8.8/32 in their allow_out arrays. But the docs never explain why, and if you do not notice it you will spend real time convinced the firewall is broken when it is doing precisely what you told it to.
There is a sibling trap in the same family, and it has bitten enough people to deserve its own line: localhost does not resolve inside a sandbox. The /etc/hosts file is empty, so localhost produces a gaierror. Use 127.0.0.1. This one silently breaks naive start_cmd and ready_cmd health probes that hit http://localhost:PORT. The server is fine, the probe just cannot find it.
Templates and builds: where the boot-speed magic actually pays off
You can build custom templates from OCI images, and this is where two of the platform’s strengths compound. The build is declarative: a BuildSpec with steps that run shell commands, set env key/value pairs, set a workdir, set a user (optionally with sudo). Each of these becomes a runtime default for sandboxes booted from the template. A build workdir becomes the default cwd, a build user becomes the default exec identity, build env becomes runtime environment.
A few build facts worth knowing before you start. The source from image must be linux/amd64, and Alpine is rejected at create time with a 400, so plan on a glibc base. Setting user.sudo: true writes a NOPASSWD sudoers entry, but note that the sudo binary itself is not installed on minimal bases like python:3.11-slim, so the entry is inert until you install sudo. Builds are async: create template returns 202 and the build runs in the background, streaming an SSE log of system/stdout/stderr frames with step boundaries and a terminal finished:true status:ready|failed|cancelled. A failed step sets status to failed with an error_message prefixed step_failed:. Rebuilding an unchanged spec produces a new build id but the same build_spec_hash, which is how the platform knows nothing changed.
Here is the part that connects back to boot speed. A template can declare a start_cmd and a ready_cmd. The start process is captured live in the snapshot. Which means:
A sandbox booted from a template with a
start_cmdHTTP server comes up with that server already responding. Not “starts the server on boot.” The server is already running in the restored image, the instant the VM is active.
This is the answer to the daemon problem from the exec section, and it is genuinely excellent engineering. You bake your agent, your tool server, your whatever into a template once; every sandbox from that template boots in well under a second with the service live. The combination of sub-second cold boot and a pre-warmed start_cmd is what makes “a fresh isolated computer per request, with my stack already running on it” a real option rather than an aspiration. We verified it: a custom template that baked in the Opencode CLI plus a config file booted with the binary symlinked into place and ran a real coding task on first exec.
One template footgun worth the warning: the template’s env PATH is not applied to exec. If you install a CLI during the build, symlink it into /usr/local/bin so exec can find it, rather than relying on a PATH entry that will not be there.
The agent layer: nine runtimes, driven live
A sandbox that runs commands is useful. A sandbox that runs agents is the actual product, and SuperServe ships templates with agent runtimes pre-installed. We drove nine of them with real API keys (OpenAI and Anthropic) injected as sandbox env_vars. Egress to the model APIs is open by default, so the keys just work.
The point of this exercise was not “does it print something.” It was to confirm each runtime could do the full loop: reason, write a file, run a shell command, generate and execute code, and, where applicable, hold memory across turns. Every one of these has a transcript behind it.
| Runtime | Template | Result | The evidence |
|---|---|---|---|
| OpenAI Agents SDK | python-3.11 | real model call | returned 391 for “what is 17 × 23” |
| Codex CLI | node-22 | wrote and ran code | created fib.js, ran it → 0 1 1 2 3 5 8 13 21 34 |
| OpenClaw | openclaw | full agent turn | reasoning, file creation, shell, code-gen, multi-turn memory |
| Opencode | node-22 | real model call | opencode run → 391 |
| Kilocode | node-22 | installed and ran | CLI v7.3.16 |
| Hermes | hermes | full real-world suite | 12 of 12 capabilities, via the Anthropic provider |
| Claude Code | claude-code | real coding task | wrote fib.py, ran it → 0 1 1 2 3 5 8 13 21 34 |
| Claude Agent SDK | claude-code | real model call | query() succeeded |
| Mesa (virtual FS) | base | CLI installs | mesa 0.33.0; mount needs a Mesa account key |
That 0 1 1 2 3 5 8 13 21 34 shows up twice for a reason: it is the success signal for “the agent wrote real code and the sandbox actually executed it,” and asserting on the output of executed code rather than on the agent’s chat reply is the difference between testing the runtime and testing the model’s manners. The Codex transcript is representative:
FILE:const fib = (n) => { ... };RUN:0 1 1 2 3 5 8 13 21 34A handful of integration notes that will save anyone driving these runtimes headless an afternoon each:
- Codex does not use the
OPENAI_API_KEYenvironment variable forcodex exec. You must pipe it through login:printenv OPENAI_API_KEY | codex login --with-api-key. Then run with--dangerously-bypass-approvals-and-sandbox, because the MicroVM already is the sandbox. - Claude Code refuses
--dangerously-skip-permissionswhen running as root, which is the default sandbox identity. Use--allowedTools Write Bash Readfor non-interactive tool use instead. Andclaude-agent-sdkneedspip install --break-system-packageson the Ubuntu-based template. - OpenClaw local turns need a session selector (
--session-id,--agent, or--to) or they have nowhere to route. - Hermes has the most consequential quirk. The provider id for an OpenAI key is
openai-api, notopenai. But the bigger issue: in version 0.14.0, theopenai-apione-shot path returns empty final text. The OpenAI request itself succeeds, but a Hermes-internal rendering quirk swallows the output. The fix is to use theanthropicprovider, which works end to end. Our full 12-of-12 Hermes real-world suite ran on Anthropic for exactly this reason.
The orchestration proof: a swarm that actually executed
Most “multi-agent” demos show you a diagram. We wanted to know whether SuperServe could host a real orchestration: agents decomposing a goal, working in parallel, gating on each other, and producing a verified deliverable, without a human in the loop.
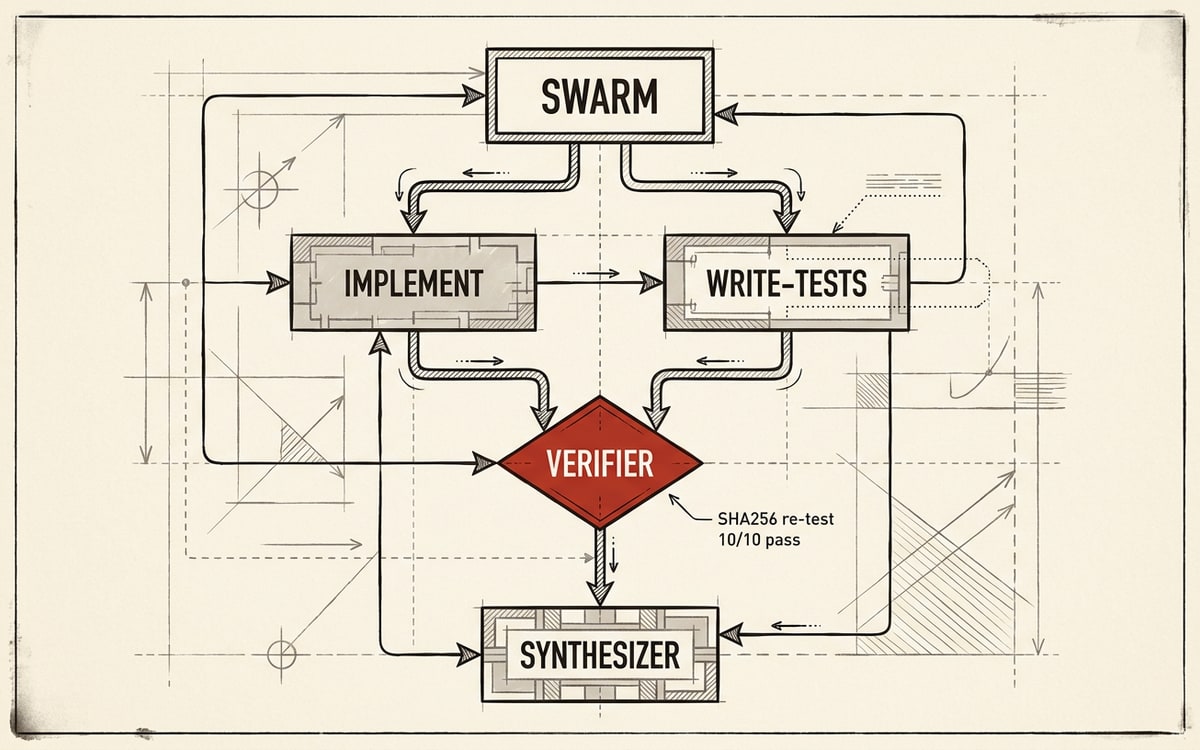
Hermes has a durable kanban swarm. hermes kanban swarm "<goal>" creates a crash-recoverable DAG in a local SQLite database: a root card, N parallel worker cards, a verifier gated on all workers, and a synthesizer gated on the verifier. In an earlier phase we created such a DAG and watched the tasks sit in “ready” forever, which is the failure mode that makes people dismiss agent swarms as vaporware. The missing piece turned out to be the dispatcher: hermes kanban dispatch (one tick) or hermes kanban daemon (a loop) is what actually spawns an agent process for each ready task.
With the dispatcher running, the swarm executed. The goal was “build a Python add(a, b) function with a pytest test.” The DAG came up:
✓ t_398a5892 done Swarm: Build a Python function add(a,b) with a pytest test● t_0ec87e40 running Implement● t_1d19db5f running WriteTests◻ t_79ec778f todo Verify swarm outputs◻ t_a206cf41 todo Synthesize swarm outputsBoth workers ran in parallel in isolated workspaces. The verifier fired only after both workers finished: the gate held. And the deliverable was real, not a status flip. The implement worker wrote add.py and a 10-case pytest suite, and the verifier re-ran that suite independently, confirming 10 of 10 passing and SHA256-matching the artifacts against the implementer’s handoff. To remove all doubt, we re-ran the produced test suite ourselves, outside the swarm entirely:
.......... [100%]10 passed in 0.02sThat is a multi-agent system, hosted in a Firecracker MicroVM, decomposing a goal and shipping verified working code with a gated quality check. It is the most concrete evidence in the whole report that SuperServe is a substrate for autonomous work and not just a remote shell.
There is one setup trap that will crash every synthesizer spawn until you fix it, and it is exactly the kind of thing only a field test surfaces. Hermes 0.14.0’s default synthesizer auto-attaches a community skill called avoid-ai-writing that is not among its built-ins. Without it, the synthesizer dies with Unknown skill(s): avoid-ai-writing. The one-time fix is to install it (hermes skills install "skills-sh/conorbronsdn/avoid-ai-writing/avoid-ai-writing" --yes) or bake it into the swarm template. Once installed, the full five-node DAG completes on the first run with zero crashes.
The closing loop: a sandbox that delivers its own work to a human
A runtime that can produce work is only half a product if the work is trapped inside it. The last thing we tested was whether a sandbox could deliver a finished deliverable out to a human, from inside the MicroVM.
It can. A superserve/base sandbox produced a small verified deliverable, ran its own tests against it, and then emailed it out. The send originated inside the sandbox, via a Composio-brokered Gmail connection, with the host only orchestrating. The success was real, with a returned Gmail message id and a "successful": true:
{"data":{"response_data":{"id":"...","labelIds":["SENT"],"threadId":"..."}}, "successful":true,"error":null}And the negative control (a malformed recipient address) failed cleanly with "successful": false and an explicit Invalid email format error, which is exactly what you want: the success path and the failure path are distinguishable, so a caller can branch on the result instead of guessing. The precise claim, stated narrowly because that is how field reports earn trust: outbound delivery is proven for email via Composio. Slack, Telegram, and the rest of the channel surface are documented but were not exercised headless in this round.
Six bugs the spec sheet will never tell you about
This is the section that justifies the whole exercise. None of these are on the landing page. All of them are things you would hit in production, and knowing them in advance is the entire value of a field report.
-
The Python SDK crashes on a missing file. Call
files.readorfiles.read_texton a path that does not exist and the Python SDK raisesAttributeError: 'str' object has no attribute 'get'instead of a properNotFoundError. The root cause is the two-plane architecture: data-plane errors arrive as{"error": "<string>"}while the SDK’s error mapper assumes the control-plane object shape{"error": {...}}. The Node SDK handles this correctly and raises a typedNotFoundError. If you are on Python, wrap your reads. -
The base template does not match its docs. As covered above,
superserve/baseships neither Python nor Node despite the introduction claiming “Python 3.12, Node.js 22.” Use the language-specific templates. -
localhostdoes not resolve. Empty/etc/hosts; use127.0.0.1. Silently breaks naive health probes. -
Domain egress needs the resolver IPs allow-listed. A deny-all policy kills DNS; allow
1.1.1.1/32and8.8.8.8/32or no domain rule can ever resolve. -
Hermes
openai-apione-shot returns empty text in v0.14.0. The request succeeds; a Hermes-internal rendering path eats the output. Use theanthropicprovider. This is an upstream Hermes issue, not a SuperServe one, but it is exactly the kind of integration reality a field test catches and a spec sheet omits. -
DELETE is asymmetric between the API and the SDK. A REST
DELETE /sandboxes/{missing}returns 404, but the SDK’skill_by_id/killByIdswallows the miss and is an idempotent no-op. Minor, but the kind of thing that matters when you are reconciling state.
None of these are damning. A Python SDK error-mapping bug, a stale docs sentence, and four documented edge cases is a short list for a four-month-old platform driven this hard. The point is not that SuperServe is buggy; it is notably solid. The point is that you could read every word of the documentation and not learn a single item on this list.
The substrate, the economics, and the lesson that outlives the vendor
Strip away the news peg (that SuperServe exists, that it launched in February, that it is one of two dozen companies selling agents a computer) and there is still a durable argument here, in two parts.
The first is about what this substrate makes buildable. The combination SuperServe delivers (per-tenant Firecracker isolation, sub-second boot, pause/resume where idle costs nothing, egress lockdown, and custom templates that bake your stack in) is not a grab bag of features. It is precisely the unit economics that the most-hyped startup category of 2026, the “AI-native service company,” requires. If your business is selling the outcome (a finished research brief, a shipped pull request, a resolved support thread) rather than the tool, then you need to run an agent per job or per customer, in hard isolation, and you cannot afford to pay for idle compute between jobs. One sandbox per tenant, paused when idle and resumed on the next request, with the agent and its skills baked into the template, is that architecture. We did not theorize this; we ran a Research-as-a-Service app on exactly this shape and a multi-agent swarm that delivered verified code. The substrate is ready for the business model before most of the businesses are.
The second, and the one that outlives any single vendor, is about evaluation. The agent-runtime category is going to consolidate, because substrates always do, and the way teams will choose between survivors is the question this report is built around. A spec sheet tells you what a vendor wants to be measured on. It told us sub-200ms and we measured a second. It told us the base template had Python and it did not. It said nothing about the process-tree wait that breaks daemons, the DNS trap that breaks egress, or the SDK that crashes on a missing file. Every one of those is something you would only discover after you had already built on it, unless someone drove it first.
That is the case for the field report as a genre. As agents take over more of the work of building software, the infrastructure they run on will increasingly be chosen by agents and for agents, on the basis of machine-readable claims that no human verifies. The discipline that protects against that is old and unglamorous: boot the box, run the command, assert on the output, write down what broke. SuperServe holds up well under that discipline, better than most things four months old have any right to. But the reason we know that is not that the landing page said so. It is that we counted to 34, ten Fibonacci numbers at a time, 356 times.