 The difference between fighting Codex and flowing with it is two TOML keys.
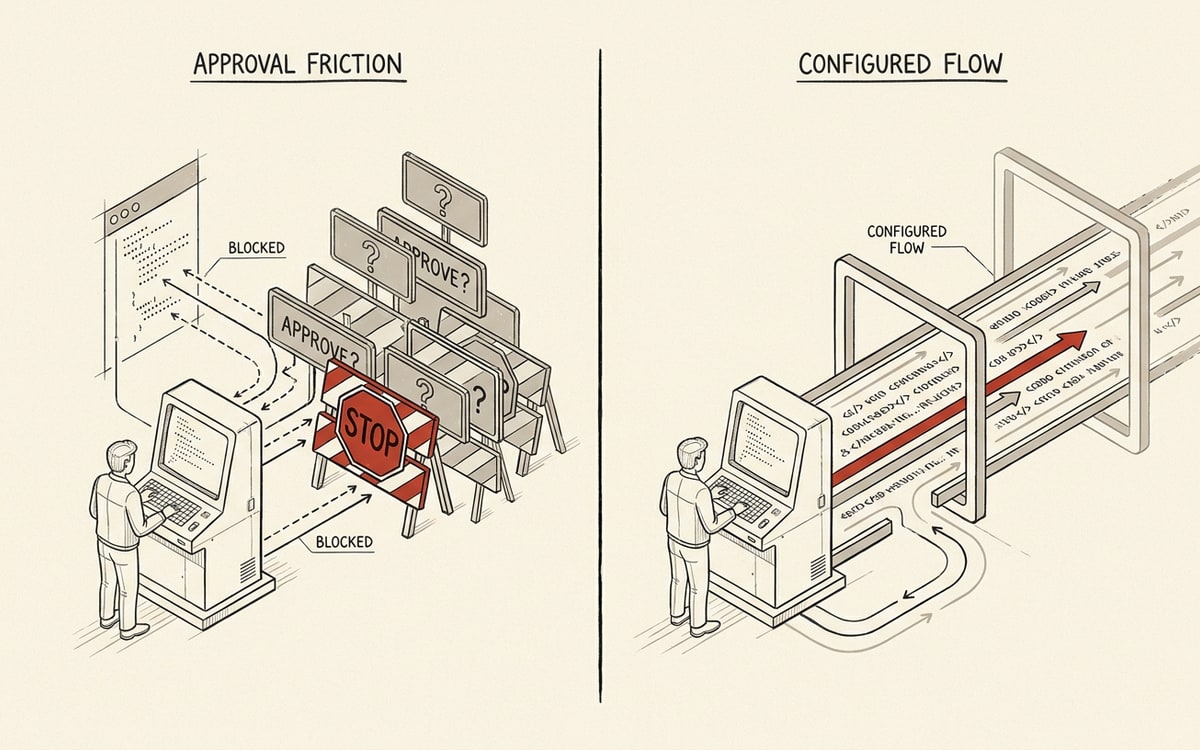
The most common thing a new Codex CLI user does is rage-quit over approval prompts. They install it, ask it to run the test suite, and watch it stop to ask permission before every single command — read this file, run that test, read the next file. The GitHub issue tracker has the receipts: “asking permission for every single file read”, “Approval prompt shown for almost every command”, thread after thread of people hitting the same wall. The reaction is almost always to blame the tool. The actual problem is that Codex CLI is sandbox-first by design, and nobody read the two config keys that turn the friction off.
Codex CLI is OpenAI’s open-source coding agent — a single Rust binary, Apache-2.0 licensed, that as of June 2026 sits at roughly 89,000 GitHub stars on release rust-v0.137.0. It was rewritten from TypeScript to Rust in mid-2025 precisely so it could enforce OS-level sandboxing without a Node runtime in the way. That sandbox is the whole personality of the tool: secure by default, and noisy until you tell it what you trust. This guide is about telling it.
Every config block below is copy-pasteable and traces to the official Codex docs, the config schema (92 documented keys), or the repository. Where the community argues about Codex versus Claude Code, and that argument is the loudest in the field right now, the quotes are real and sourced.
TL;DR
- Two dials, not one.
sandbox_modecontrols capability;approval_policycontrols how often it asks.workspace-write+on-requestis the daily-driver combo. - Config is
~/.codex/config.toml. TOML, not JSON. The MCP key ismcp_serversin snake_case;mcpServerssilently does nothing. - Profiles are the killer feature. Define a high-reasoning profile, a fast one, and a zero-retention one; switch with
--profile. - Tune reasoning per task.
model_reasoning_effortrunsminimaltoxhigh. Low for plumbing, high for architecture. Wrong setting is half the “it’s too slow” complaints. AGENTS.mdis the memory. Merged root-to-leaf, 32 KiB cap. A tight one stops Codex from over-engineering.codex execis the CI mode. Headless,--jsonevents, read-only sandbox by default. Wrap it withopenai/codex-action@v1.- Reach for a model that fits. GPT-5.5 for most work, the
*-codexvariants for long coding runs. The picker depends on your plan.
The 5-minute setup
Install, authenticate, and drop in a config that ends the prompt-nagging on day one.
# 1. Install (any of these)curl -fsSL https://chatgpt.com/codex/install.sh | sh# or: npm install -g @openai/codex   |   brew install --cask codex
# 2. Authenticate — sign in with ChatGPT (uses your plan) or an API keycodex                       # first run walks you through sign-in
# 3. Scaffold project memorycd my-projectcodex                       # launch the TUI/init                       # writes AGENTS.md from your codebase
# 4. Drop in a real ~/.codex/config.toml (full version below)$EDITOR ~/.codex/config.toml
A starter ~/.codex/config.toml that picks a sane model, sets the two dials so Codex stops asking about every read, and tunes reasoning for real work:
model = "gpt-5.5"approval_policy = "on-request" # ask only when it needs to escalatesandbox_mode = "workspace-write" # edit + run inside the project freelymodel_reasoning_effort = "medium" # raise to "high" for hard problemsThat single change, workspace-write plus on-request, is the difference between an agent that interrupts you forty times and one that works through a task and only stops when it genuinely needs to touch something outside the project or reach the network.
The mental model: two dials, not one
Almost everyone misunderstands Codex’s permission system because they think it is one setting. It is two, and they are orthogonal:
sandbox_modedecides what Codex is technically capable of doing. It is enforced by the operating system — Apple Seatbelt on macOS, Landlock plus seccomp on Linux. Even if the model decides to delete your home directory, the sandbox physically prevents it.approval_policydecides when Codex pauses to ask you. It is a workflow choice layered on top of the sandbox.
The reason this matters: cranking one does not fix the other. People set approval_policy = "never" to stop the prompts, then wonder why the agent can’t write files — because the sandbox is still read-only. Or they open the sandbox to danger-full-access and leave approvals on untrusted, and get prompted constantly anyway. You configure both, deliberately.
The values, exactly:
sandbox_mode | What it allows |
|---|---|
read-only | Read and reason only. Every edit or command needs approval. (Default.) |
workspace-write | Edit files and run commands inside the project. Network off by default. .git/ stays read-only. |
danger-full-access | Full disk and network, no walls. For trusted containers only. |
approval_policy | When Codex asks |
|---|---|
untrusted | Asks for anything not on a known-safe list. |
on-request | The model asks only when it wants to escalate. |
on-failure | Runs in the sandbox; asks only if a command fails. (Deprecated.) |
never | Never asks. codex exec always uses this. |
The presets in the TUI map onto these: Read Only (read-only + ask), Auto (workspace-write + on-request, the default inside a git repo), and Full Access (danger-full-access + never, labeled “extremely risky” for good reason).
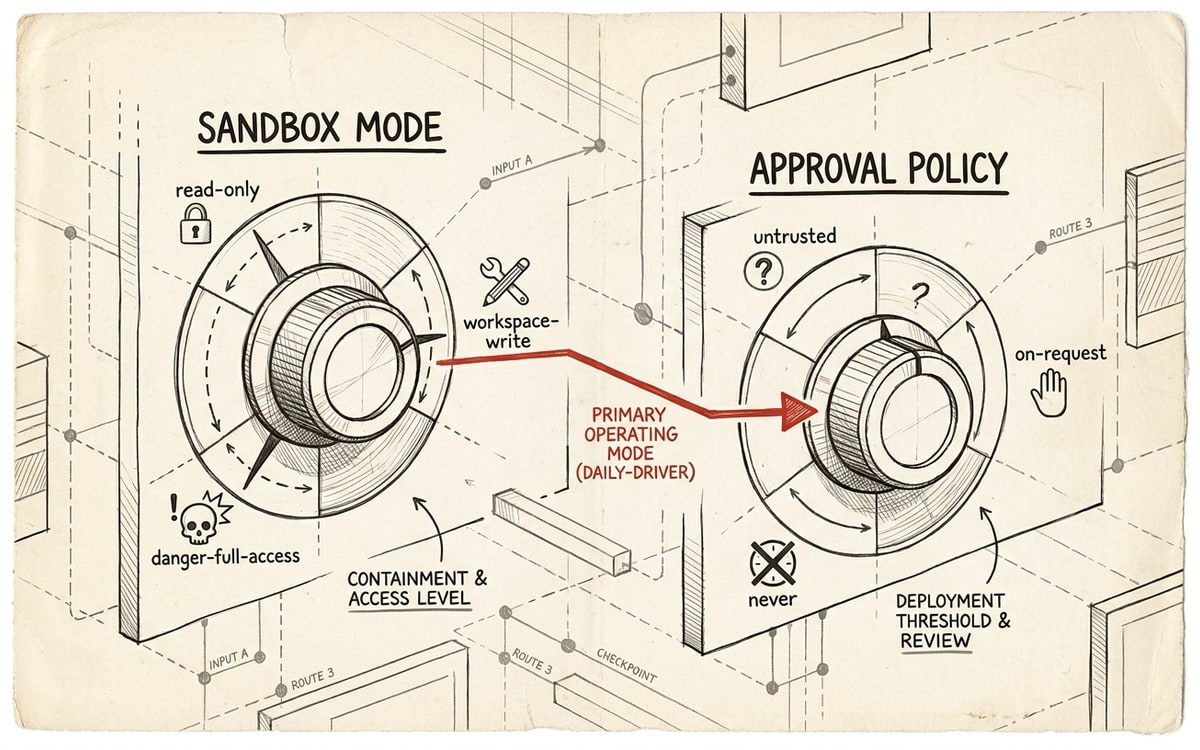 The two orthogonal dials. Setting one without the other is why people fight Codex.
config.toml: the keys that matter
Codex reads ~/.codex/config.toml (the CODEX_HOME env var relocates it). A project-local .codex/config.toml is loaded only for trusted projects, and it ignores a handful of keys for safety (model_provider, model_providers, profile, profiles, notify) that must be set at the user level. Precedence runs: CLI flag beats profile beats config.toml beats the built-in default.
The full sandbox configuration, with the workspace-write sub-table that most people never discover:
model = "gpt-5.5"approval_policy = "on-request"sandbox_mode = "workspace-write"
[sandbox_workspace_write]network_access = false # flip to true if the task needs the internetexclude_tmpdir_env_var = falseexclude_slash_tmp = falsewritable_roots = ["/Users/you/.pyenv/shims"] # extra paths to allow writesNetwork access being off by default inside workspace-write is the source of the second-most-common confusion, right after approvals: npm install or pip install will stall until you either approve it or set network_access = true. That is a feature, since it stops a compromised package’s install script from phoning home, but you have to know it’s there.
Reasoning and verbosity, the dials that fix “Codex is too slow” and “Codex writes a novel”:
model_reasoning_effort = "high" # none | minimal | low | medium | high | xhighmodel_reasoning_summary = "auto" # auto | concise | detailed | nonemodel_verbosity = "low" # low | medium | high (GPT-5 family)One commenter’s complaint captures why this matters: “If you use the low or medium reasoning it’s garbage. If you use high, it’ll think for up to five minutes on something dead simple.” That is not a flaw, it’s an un-tuned tool. Set minimal or low for mechanical edits, high or xhigh for genuine design work, and stop asking one setting to serve both jobs.
Profiles: a model loadout one flag away
Profiles are the most underused feature in Codex, and they are the cleanest answer to “I need different settings for different jobs.” Each profile is a named bundle of config; you switch with --profile.
model = "gpt-5.5"profile = "fast" # the default profile when none is passed
[profiles.fast]model = "gpt-5.5"model_reasoning_effort = "low"approval_policy = "on-request"sandbox_mode = "workspace-write"
[profiles.deep]model = "gpt-5.1-codex-max"model_reasoning_effort = "xhigh"model_reasoning_summary = "detailed"approval_policy = "on-request"sandbox_mode = "workspace-write"
[profiles.zdr]model = "gpt-5.5"disable_response_storage = true # zero data retentionapproval_policy = "untrusted"sandbox_mode = "read-only"Now codex --profile deep "redesign the auth layer" gives you a max-reasoning coding model, codex --profile fast "rename this variable everywhere" keeps plumbing cheap and quick, and codex --profile zdr runs locked down for sensitive code. One config file, three working postures, zero re-typing of flags.
AGENTS.md: the memory, and the cure for over-engineering
Codex’s project memory is AGENTS.md — the same open convention several agents now share. Codex builds its instruction set at startup by discovering these files and merging them root-to-leaf: a global ~/.codex/AGENTS.md, then the project root, then deeper directories, with closer files overriding and a default cap of 32 KiB. /init scaffolds one from your codebase.
## Conventions- TypeScript strict mode. No `any`. Run `pnpm typecheck` before done.- Prefer the smallest change that solves the problem. Do not refactor adjacent code unless asked.
## Commands- Test: `pnpm test`- Lint: `pnpm lint --fix`
## Boundaries- Never edit `db/migrations/` — generated.- Never add a dependency without flagging it first.That “prefer the smallest change” line is doing real work. The single most-cited criticism of GPT-5-class models in coding is a tendency to over-build. As one developer put it on Hacker News: “GPT-5 is very prone to a style that would for most codebases be overengineering”. A tight AGENTS.md with explicit scope discipline is the most effective counter — far more than fighting it turn by turn. You can also point Codex at fallback filenames if your team already standardized on something else:
project_doc_fallback_filenames = ["CONTRIBUTING.md", ".agents.md"]project_doc_max_bytes = 65536MCP servers: TOML, and the key name that bites everyone
Codex is an MCP client. Servers go in config.toml under mcp_servers — and the single most common config mistake is writing mcpServers (camelCase, the way other tools spell it), which Codex silently ignores.
# Correct: snake_case, mcp_servers[mcp_servers.playwright]command = "npx"args = ["-y", "@playwright/mcp@latest"]
[mcp_servers.github]command = "npx"args = ["-y", "@modelcontextprotocol/server-github"]env = { GITHUB_TOKEN = "ghp_..." }startup_timeout_sec = 20
[mcp_servers.grep]url = "https://mcp.grep.app" # url = streaming HTTP; command/args = stdiorequired = false # true makes `codex exec` fail hard if it can't startA server with command/args runs over stdio; one with url is a remote HTTP server. The required flag is the one to know for CI: set it true and a codex exec run aborts with a non-zero exit if the server can’t initialize, which is exactly what you want in a pipeline and exactly what you don’t want interactively. As with any agent, restraint pays — every server’s tool list is context the model carries every turn, so install the few that earn their keep and lean on bash-callable CLIs (gh, psql) for the rest.
codex exec: the headless mode built for CI
The interactive TUI is for you. codex exec is for everything automated. It runs non-interactively, streams progress to stderr and the final answer to stdout (so it pipes cleanly), and defaults to a read-only sandbox and approval_policy = "never".
# One-shot, read-only, pipe the resultcodex exec "summarize what changed in the last 10 commits" > summary.md
# Let it actually fix things in a controlled sandboxcodex exec --sandbox workspace-write "fix the failing tests in src/auth"
# Machine-readable event stream for toolingcodex exec --json "audit deps for known CVEs" | jq 'select(.type=="item.completed")'
# Resume the previous runcodex exec resume --last "now open a PR with those fixes"
Authentication for headless runs uses CODEX_API_KEY (note: this variable is read only in codex exec, and as of v0.36.0 plain OPENAI_API_KEY is no longer picked up implicitly — a breaking change that surprised a lot of CI pipelines). The --json event stream emits structured objects (thread.started, turn.completed, item.*, error) that you can drive a dashboard or a gate off.
For GitHub specifically, the official openai/codex-action@v1 wraps codex exec with privilege controls:
- uses: openai/codex-action@v1 with: openai-api-key: ${{ secrets.OPENAI_API_KEY }} prompt: "Review this PR's diff for security regressions and comment." safety-strategy: drop-sudo # drop-sudo (default) | unprivileged-user | unsafeCodex versus Claude Code: what the switchers actually say
No tool guide written in 2026 can ignore the rivalry, because it is the most active migration in developer tooling. The short version: after GPT-5 and the gpt-5-codex models landed, a wave of heavy Claude Code users moved to Codex, and the reasons they give are consistent and specific.
The headline claim, from a team that tracked its spend:
We were heavy users of Claude Code ($70K+ spend per year) and have almost completely switched to codex CLI. I’m doing massive lifts with it on software that would never before have been feasible for me personally, or any team I’ve ever run.
— mmaunder, Hacker News
The mechanism, repeatedly, is instruction-following — Codex does what you said, where Claude Code is more eager to expand on the request:
Not suddenly, it’s been better since GPT-5 launched… With Claude Code, you can use less prompting, and Claude will get token happy and expand on your request. Great for greenfield/vibing, bad for iterating on existing projects. With Codex CLI, GPT-5 seems to handle instructions much more precisely. It won’t just go off on its own.
— jumploops, Hacker News
But the honest picture includes the counter-case, and it lands on exactly the friction this guide opened with — plus a UX gap Claude Code genuinely still wins:
the Claude Code UI is still so much better, and the permissioning policy system is much better… sick of Codex asking for approval to run tests for each test instance.
— maherbeg, Hacker News
That complaint is real, and it is also, mostly, a configuration problem — the approval nagging is precisely what workspace-write plus on-request fixes. The fair summary is that Codex rewards precise instructions and tight scope, Claude Code rewards loose greenfield prompting, and the pendulum between them flips with every model release. Pick the one whose defaults match how you work, then configure away the friction. Do not pick based on last week’s benchmark; both teams ship monthly.
Practical workflows that compound
- Plan before full-auto. Use
/planor a read-only first pass to get an approach, approve it, then switch the sandbox toworkspace-writeand let it execute. Cold-starting an agent in full-auto on a vague prompt is how you get over-engineering. - Esc-Esc to backtrack. In the TUI, double-Escape forks the conversation from an earlier message — cheaper than re-explaining when the agent went down the wrong path.
/reviewbefore you commit. Codex’s built-in review runs with no side effects and follows yourAGENTS.md. Setreview_modelto a stronger model than your daily driver if you want a tougher reviewer.- Lower reasoning for mechanical work. Renames, formatting, mechanical refactors:
--profile fastwithloweffort. Savexhighfor design. - Use the ChatGPT plan for cost. Signing in with a ChatGPT subscription instead of metered API keys is a large part of why the cost-conscious switchers moved; for heavy daily use the math is very different from per-token billing.
Anti-patterns: stop doing these
- Setting
approval_policy = "never"to stop prompts while leavingsandbox_mode = "read-only". Now it can’t edit anything. Set the sandbox too. - Expecting
npm installto work inworkspace-write. Network is off by default. Setnetwork_access = truefor that task or approve it. - Writing
mcpServers. It’smcp_servers. The camelCase version is ignored without error. - Running everything at
xhigh. You’ll wait five minutes for a variable rename. Match effort to the task. - Skipping
AGENTS.md. Without scope discipline written down, GPT-5-class models over-build. The file is the cheapest fix. - Relying on implicit
OPENAI_API_KEYin CI. Since v0.36.0,codex execwantsCODEX_API_KEY. Update your pipelines.
Troubleshooting and gotchas
- Approval prompt for every command. You’re in
read-onlyoruntrusted. Move toworkspace-write+on-request. This is issue #14936 and friends: overwhelmingly a config issue, not a bug. - Commands fail silently in the sandbox. A command needs network or a write outside the workspace. Check
network_accessandwritable_roots. git commitkeeps prompting..git/is read-only underworkspace-writeby design, so commits escalate. Approve them, or commit yourself.- Tests fail only under Codex. The sandbox blocks something the tests need (a socket, a temp path). Add the path to
writable_rootsor enable network for that run. - Config edits seem ignored in a project. Project-local
.codex/config.tomlignoresmodel_provider,profiles,notify, and similar — set those in~/.codex/config.toml. - CI auth broke after an upgrade. v0.36.0 stopped reading
OPENAI_API_KEYimplicitly incodex exec. UseCODEX_API_KEY. - Linux container can’t sandbox. Landlock/seccomp may be unavailable in some containers; run in a hardened container with
--dangerously-bypass-approvals-and-sandbox, never on a real machine. - Inspect what’s happening.
codex debug seatbelt(macOS) andcodex debug landlock(Linux) show exactly what the sandbox is enforcing.
The drop-in starter pack
A complete ~/.codex/config.toml that combines everything above — a default fast profile, a deep-reasoning profile, a locked-down profile, sane sandbox defaults, and two MCP servers that earn their place:
model = "gpt-5.5"approval_policy = "on-request"sandbox_mode = "workspace-write"model_reasoning_effort = "medium"model_verbosity = "low"profile = "fast"
[sandbox_workspace_write]network_access = false
[profiles.fast]model = "gpt-5.5"model_reasoning_effort = "low"
[profiles.deep]model = "gpt-5.1-codex-max"model_reasoning_effort = "xhigh"model_reasoning_summary = "detailed"
[profiles.zdr]model = "gpt-5.5"disable_response_storage = trueapproval_policy = "untrusted"sandbox_mode = "read-only"
[mcp_servers.playwright]command = "npx"args = ["-y", "@playwright/mcp@latest"]
[mcp_servers.grep]url = "https://mcp.grep.app"required = falsePair it with a tight AGENTS.md, start hard tasks in --profile deep, keep plumbing in --profile fast, and run CI through codex exec --json. The approval prompts that make people quit Codex in the first hour are not the tool being broken. They are the tool asking you to tell it what you trust. Answer once, in TOML, and it stops asking.
Sources & credits
Configuration synthesized from the official Codex CLI docs, the config reference and schema, and the openai/codex repository at release rust-v0.137.0. Timeline from OpenAI’s Codex announcements and the Rust rewrite discussion. Community sentiment from the linked Hacker News threads; approval-friction reports from the cited GitHub issues. Model names reflect the lineup as of June 2026; the picker’s contents vary by plan and change often.