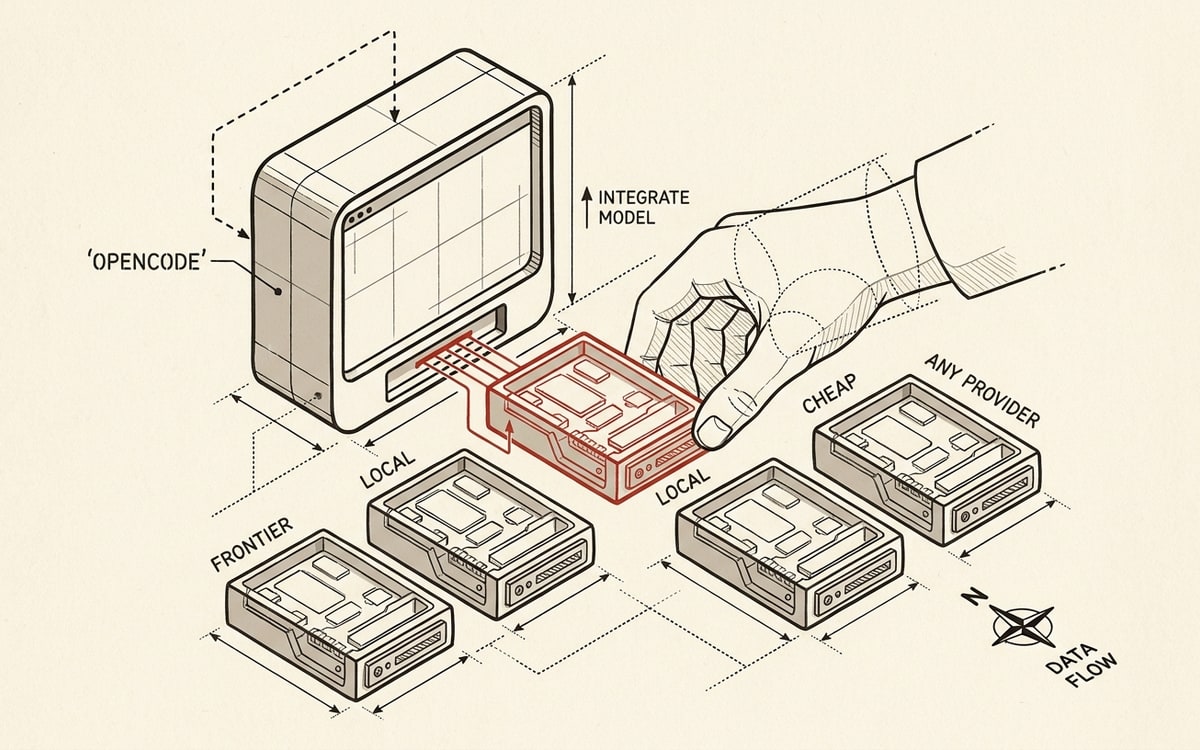
 One interface, any model. OpenCode treats the model as a config value, not a lock-in.
In January 2026, Anthropic flipped a server-side switch and a generation of developers learned what vendor lock-in feels like. Subscription credentials that had quietly worked inside third-party coding agents started returning a single sentence: “This credential is only authorized for use with Claude Code.” If your agent was a closed, single-vendor CLI, there was nothing to do but wait. If your agent was OpenCode, you opened one config file, changed the model string, and kept working. That difference is the entire reason this tool is worth configuring properly. Not a benchmark, not a demo: a config line.
OpenCode is the open-source terminal coding agent built by Dax Raad (@thdxr) and Adam (@adamdotdevin). It is MIT-licensed, it runs against any model from any provider, and as of June 2026 it sits at over 171,000 GitHub stars with roughly 947 contributors and a release cadence that pushes multiple versions a week. It is also the tool most people use wrong — they install it, point it at CLAUDE.md, and treat it as a free Claude Code skin. That works, and it wastes the one thing OpenCode does that no closed CLI can: it makes the model a setting you control.
This is the setup, end to end. Every config block below is copy-pasteable and traces to the official docs or the repo at release v1.16.2. Where the community disagrees about OpenCode, and it does so loudly, the disagreement is quoted directly with the source attached.
TL;DR
- Set two models, always.
modelfor real work,small_modelfor titles, summaries, and compaction. The cheap model handles the housekeeping the agent does dozens of times a session. - Two config files, not one.
opencode.jsoncontrols behavior;tui.jsoncontrols theme and keybinds. Theme keys inopencode.jsonare deprecated and silently migrated — set them intui.json. - Lock permissions before the first run. Defaults allow everything except reading
.env. On untrusted code, setbashandedittoask. - Use the Plan agent to think, the Build agent to do.
Tabcycles between them. Plan is read-only; Build has every tool. - Write an
AGENTS.md, commit it./initscaffolds one. It is the project memory every session loads. - Install MCP servers deliberately. Local (
stdio) for system access, remote (HTTP) for hosted tools. Each one is permanent context the model pays for every turn. - Run a server, attach clients.
opencode serveonce, thenopencode run --attachfor instant headless calls without re-booting MCP. - The model is config. When a provider changes the rules, you change a string. That is the whole pitch.
The 5-minute setup
If you read one section, read this. Get a working power-config, then come back for the why.
# 1. Install (any of these)curl -fsSL https://opencode.ai/install | bash# or: npm i -g opencode-ai   |   brew install sst/tap/opencode
# 2. Authenticate a provider (interactive picker)opencode auth login          # pick Anthropic, OpenAI, OpenRouter, Google, etc.
# 3. Scaffold project memorycd my-projectopencode                     # launches the TUI# inside the TUI:/init                        # writes AGENTS.md from your codebase
# 4. Drop in a real global config (full version below)mkdir -p ~/.config/opencode$EDITOR ~/.config/opencode/opencode.json$EDITOR ~/.config/opencode/tui.json
A starter ~/.config/opencode/opencode.json that already does the two-model trick and a sane permission baseline:
{ "$schema": "https://opencode.ai/config.json", "model": "anthropic/claude-sonnet-4-5", "small_model": "anthropic/claude-haiku-4-5", "autoupdate": true, "permission": { "bash": { "*": "ask", "git status": "allow", "git diff *": "allow", "ls *": "allow" }, "edit": "ask" }}And the matching ~/.config/opencode/tui.json:
{ "$schema": "https://opencode.ai/tui.json", "theme": "tokyonight", "keybinds": { "leader": "ctrl+x" }}That is a defensible default: a strong model for work, a cheap one for chatter, and an agent that asks before it runs a shell command or edits a file. Everything past this point is about earning more from the same tool.
The mental model: OpenCode is a server with swappable faces
The single most clarifying fact about OpenCode is buried in a Hacker News reply Dax Raad wrote a month into the project’s life:
the cli is client/server model - the TUI is our initial focus but the goal is to build alternative frontends, mobile, web, desktop, etc. we think of our task as building a very good code review tool.
— @thdxr, Hacker News, July 2025
Internalize that and the rest of the tool stops being surprising. There is a server, the agent engine that talks to models, runs tools, and holds session state, and there are clients that attach to it: the TUI you usually see, a web UI, a desktop app, an SDK. opencode serve starts the server on its own; opencode starts a server and a TUI together. This is why headless automation is fast once a server is already running, and why “build your own frontend” is a real option rather than a slogan.
The second clarifying fact is that OpenCode owns no model. Model metadata (context windows, pricing, capabilities) comes from the open Models.dev catalog, and the model you use is just a provider/model string. Claude Code is Anthropic’s product running Anthropic’s models. OpenCode is a harness, and the model is fuel you choose at the pump.
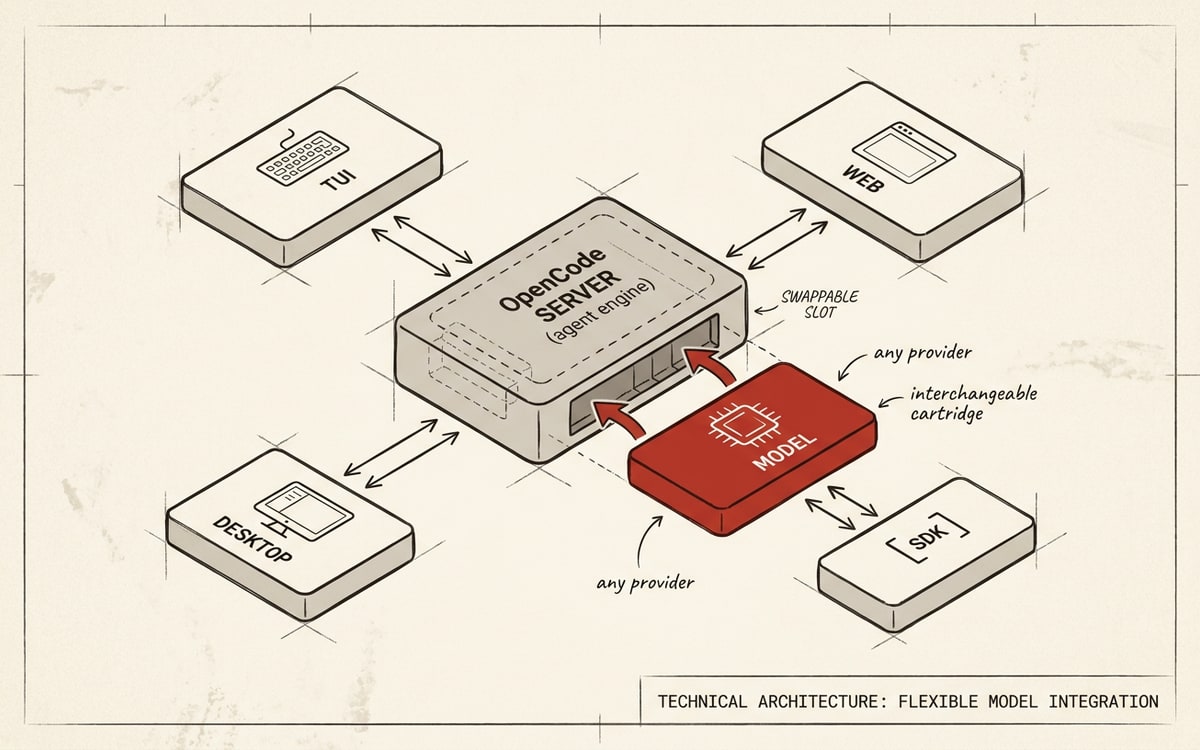 One server, many faces, and a model slot you swap. The architecture is the argument.
| OpenCode | Claude Code | |
|---|---|---|
| License | MIT, open source (171K+ stars) | Closed, proprietary |
| Models | Any provider, any model (provider/model string) | Anthropic models only |
| Cost control | Split frontier + small_model; route cheap models for bulk work | One vendor’s pricing |
| Architecture | Client/server — TUI, web, desktop, SDK frontends | Single closed CLI |
| Headless / CI | opencode serve once, attach often; machine-readable output | claude -p one-shot |
| Memory file | AGENTS.md (reads CLAUDE.md as fallback) | CLAUDE.md |
| Config | opencode.json + tui.json, layered/merged | settings.json |
| Permissions | Per-tool keys (edit, bash, webfetch…) + doom_loop guard | Allow/deny lists |
| MCP servers | Yes | Yes |
| When a vendor cuts access | Change one string, keep working | Wait for the vendor |
| Best when | You want model choice, cost control, no lock-in | You want Anthropic’s models with zero setup |
How the config actually resolves
OpenCode merges config from many places, and the order matters because the files are merged, not replaced — a project config does not wipe your global one, it layers on top. From lowest to highest precedence:
- Remote config served at a repo’s
.well-known/opencode - Global:
~/.config/opencode/opencode.json - The path in the
OPENCODE_CONFIGenvironment variable - Project:
opencode.json(or.jsonc) in the project root - Any
.opencode/directories walking up from the cwd - Inline JSON in
OPENCODE_CONFIG_CONTENT - Managed/enterprise files (
/etc/opencode/on Linux, the equivalent on macOS and Windows)
Two practical consequences. First, put personal defaults (your model, your theme, your keybinds) in the global file and project-specific rules (permissions for that repo, custom commands) in the project file — they combine cleanly. Second, the subdirectory names OpenCode looks for are plural: agents/, commands/, modes/, plugins/, skills/, themes/. A single-named agent/ directory is invisible, and this trips up nearly everyone once.
Both config files take a $schema line. Use it — it gives you autocomplete and validation in any editor with a JSON language server, and it is the single cheapest way to avoid inventing keys that do not exist:
{ "$schema": "https://opencode.ai/config.json" } // behavior{ "$schema": "https://opencode.ai/tui.json" } // theme + keybindsTwo models, not one: the setting that pays for itself
Most people set model and stop. The move that pays for itself is to set small_model as well. OpenCode uses the small model for the work you never think about: generating session titles, summarizing, and running compaction when context fills. That work happens constantly. Paying frontier prices for it is pure waste.
{ "$schema": "https://opencode.ai/config.json", "model": "anthropic/claude-sonnet-4-5", "small_model": "anthropic/claude-haiku-4-5"}The model ID is always provider_id/model_id. You can disable providers you never want to see in the picker, and the deny list wins over the allow list:
{ "$schema": "https://opencode.ai/config.json", "disabled_providers": ["amazon-bedrock", "azure"]}This is also where OpenCode’s whole reason for existing pays off. The same harness will run Sonnet for architecture, a local Qwen-Coder for bulk refactors, and DeepSeek for cheap throughput — by changing strings, not tools. More on that in the cost section.
Permissions: assume the worst, then loosen
OpenCode’s default permission posture is permissive: it will read, edit, and run shell commands without asking, and the only thing it refuses out of the box is reading .env files. On your own trusted projects that is fine and fast. On anything you cloned, anything with untrusted contributors, or anything an agent might run unattended, it is the wrong default and you should change it before the first prompt.
Permissions take three values (allow, ask, deny) and you can scope them per command with glob patterns. The rule that matters: last match wins, so order from general to specific.
{ "$schema": "https://opencode.ai/config.json", "permission": { "bash": { "*": "ask", "git status": "allow", "git diff *": "allow", "ls *": "allow", "cat *": "allow", "rm *": "deny", "git push *": "deny" }, "edit": "ask", "webfetch": "ask" }}The full set of permission keys is read, edit, glob, grep, bash, task, skill, lsp, question, webfetch, websearch, external_directory, and doom_loop (the last fires when the agent appears stuck in a repeating cycle). There is a --dangerously-skip-permissions flag. It exists for sandboxed VMs and CI containers, and using it on your laptop is how you let a poisoned dependency’s instructions run rm with your credentials. Don’t.
The two agents you actually use: Plan and Build
OpenCode ships primary agents you cycle through with Tab, and two of them carry the workflow:
- Build is the default. Every tool available: read, edit, bash, the works.
- Plan is read-only. It can read, search, and reason, but edits and shell commands flip to
ask. It is for thinking before touching.
The high-value pattern mirrors the best practice from every serious agent workflow: plan first, build second. Start a session in Plan, let the model read the codebase and propose an approach, argue with it until the plan is right, then Tab to Build and let it execute against a plan you already trust. To make Plan your default so you never accidentally let a cold model start editing:
{ "$schema": "https://opencode.ai/config.json", "default_agent": "plan"}Below the primaries sit subagents you invoke with @ or that the model calls automatically:
- General: full tools, used for parallel chunks of work.
- Explore: fast, read-only codebase search.
- Scout: external research across docs, dependencies, and the wider world.
You can define your own agent as a markdown file in ~/.config/opencode/agents/ with frontmatter, which is the clean way to encode a repeatable role:
---description: Reviews diffs for security issues and over-engineering. Read-only.mode: subagentmodel: anthropic/claude-sonnet-4-5temperature: 0.1permission: edit: deny bash: deny---
You are a senior reviewer. Read the diff. Flag security issues, missingerror handling, and any change more complex than the problem requires.Do not edit files. Output a numbered list, most serious first.AGENTS.md: the memory file, and the fallback that hides it
OpenCode’s project memory lives in AGENTS.md at the repo root. /init writes a first draft by reading your codebase; you commit it so the whole team shares one source of truth. A global ~/.config/opencode/AGENTS.md holds rules you want everywhere. You can split rules across files and pull them in with @-references:
- Use Bun, not npm. Run `bun test` before declaring anything done.- Never edit files in `generated/` — they come from codegen.- Commits: conventional-commit prefixes, no co-author trailers.
@docs/architecture.md@docs/api-conventions.mdHere is the catch that the whole title is about. OpenCode reads CLAUDE.md and ~/.claude/CLAUDE.md as a fallback when there is no AGENTS.md. That is a thoughtful migration feature — your Claude Code setup works on day one. It is also the trap: people drop OpenCode onto an existing CLAUDE.md, get a familiar experience, and never write an AGENTS.md or learn the Plan/Build split, the two-model trick, or the permission model. If you want to force yourself off the training wheels:
export OPENCODE_DISABLE_CLAUDE_CODE=1Using OpenCode as a Claude Code clone is using a multi-model harness as a single-model skin. The fallback is a bridge, not a destination.
MCP servers: deliberate, not maximal
OpenCode is an MCP client, and you wire servers into opencode.json under the mcp key. Local servers run as subprocesses with system access; remote servers are hosted over HTTP and OAuth is handled for you.
{ "$schema": "https://opencode.ai/config.json", "mcp": { "playwright": { "type": "local", "command": ["npx", "-y", "@playwright/mcp@latest"], "enabled": true }, "grep-app": { "type": "remote", "url": "https://mcp.grep.app", "enabled": true }, "github": { "type": "remote", "url": "https://api.githubcopilot.com/mcp/", "enabled": true, "headers": { "Authorization": "Bearer {env:GITHUB_TOKEN}" } } }}Note {env:GITHUB_TOKEN}: OpenCode expands {env:VAR} and {file:path} in config, so secrets stay in your environment instead of your committed config. The discipline that matters with MCP is restraint. Every server’s tool descriptions are injected into context on every turn, so each one you add is a permanent token tax the model pays whether or not it uses that server. Install the few that earn their place (a browser driver, a code-search server, your issue tracker) and resist the rest. CLI tools the model can already call via bash (gh, aws, psql) often beat an MCP server that does the same thing at context cost.
Bring your own model: local, cheap, and lock-in-proof
This is the section a Claude Code guide cannot write. Because OpenCode is provider-agnostic, you can point it at a model running on your own machine. The official Ollama setup:
{ "$schema": "https://opencode.ai/config.json", "provider": { "ollama": { "npm": "@ai-sdk/openai-compatible", "name": "Ollama (local)", "options": { "baseURL": "http://localhost:11434/v1" }, "models": { "qwen3-coder:30b": { "name": "Qwen3 Coder 30B" } } } }, "model": "ollama/qwen3-coder:30b"}Any OpenAI-compatible endpoint works the same way: LM Studio, llama.cpp’s server, a cloud provider you’d rather use, a gateway you run yourself. Maintainer rekram1-node, asked which open models actually drive the agent well, named Kimi K2 and Qwen3-Coder, a useful starting point if you’re routing work to non-frontier models. The practical pattern that most teams converge on is tiered: a frontier model on model for genuinely hard reasoning, a cheap or local model on small_model and for bulk subtasks, and a hard ceiling on what you spend per session because the expensive model only runs when it has to.
The point is not that local models match Sonnet. They don’t, yet. The point is that the choice is yours, per task, per repo, per budget — and it survives any single vendor deciding to change the terms.
Headless and CI: serve once, attach often
For automation, opencode run executes a single prompt without the TUI:
# One-shot, machine-readable outputopencode run --format json "summarize the changes in the last 5 commits"
# Continue the previous sessionopencode run -c "now write release notes from that summary"
# Pick the model and agent explicitlyopencode run -m anthropic/claude-sonnet-4-5 --agent plan "audit auth.ts for issues"
The speed trick is to keep a server warm and attach to it, so you skip the MCP cold-boot on every call:
opencode serve & # start the server onceopencode run --attach http://localhost:4096 "run the test suite and fix failures"For GitHub, opencode github install wires the agent into your repository, and opencode github run drives it in Actions. The server also exposes an HTTP API (opencode serve, with OPENCODE_SERVER_PASSWORD for basic auth) if you want to build your own frontend against it — which, per the architecture, is the intended endgame.
The feud that proves the thesis
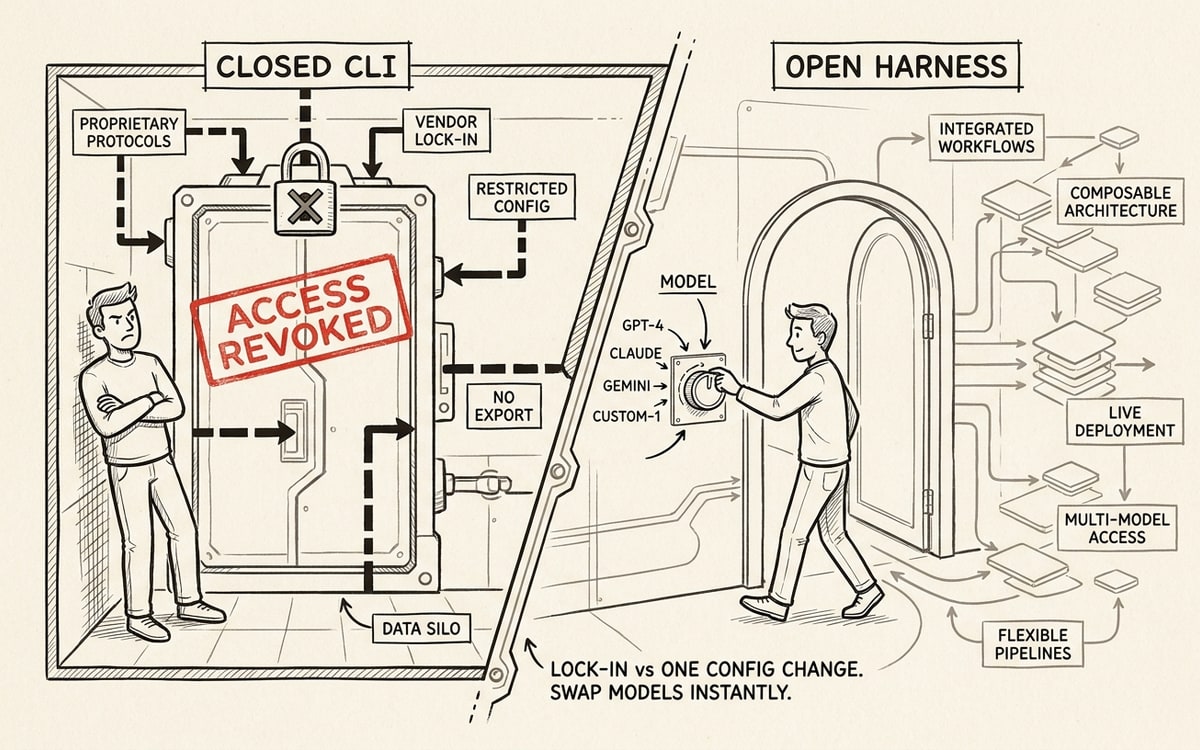 Closed CLI versus open harness: one is a locked door, the other is a dial.
OpenCode’s defining moment was not a feature. In January 2026, Anthropic began server-side blocking Claude subscription credentials used inside third-party agents, returning “This credential is only authorized for use with Claude Code.” Over the following weeks the restriction was formalized into the terms of service. In March, OpenCode merged PR #18186, titled flatly “anthropic legal requests,” stripping Anthropic prompt files, provider hints, and the built-in Claude-auth plugin from the codebase. The community reaction is recorded in the reactions on that pull request: 518 thumbs-down. Dax Raad’s summary, posted when the auto-loading Claude plugin was removed, was that the team tried to convince Anthropic to support developer choice and got lawyers instead.
This sat on top of an older fight over the OpenCode name itself, which the Charm CEO laid out publicly:
they forked the repo, moved it into their company’s GitHub org, retained the OpenCode name, took over the AUR package, and redirected the domain they owned.
— @meowgorithm Charm CEO, June 13, 2025
You can read that as a project born in controversy. You can also read the scoreboard: the TypeScript OpenCode that came out of that split is now past 171,000 stars while the original stalled, having won by out-shipping. And where Anthropic sent legal requests, OpenAI did the opposite:
we are working with openai to allow codex users to benefit from their subscription directly within OpenCode
— @thdxr January 9, 2026
One vendor treated an open agent as a threat to be walled off; another treated it as distribution. For a developer, the lesson is not about who was right. It is that if your tool is a single company’s closed CLI, that company’s business decisions are your problems. If your tool is an open harness, they are a config change.
Praise, and the criticism worth heeding
The praise for OpenCode is specific and it is about the feedback loop, not the novelty:
I was blown away, primarily by the feedback loops… first time I felt like I could write up a large prompt, walk away from my laptop, and come back to a lot of work having been done.
— jeremy_k, Hacker News, July 2025
I found out about OpenCode through the Anthropic feud. I now spend most of my AI time in it… the most complete solution I’ve found.
— solarkraft, Hacker News
The criticism is just as specific, and worth taking seriously before you adopt the tool as core infrastructure. The most credible complaint is about the release cadence — the same velocity that ships features weekly also ships regressions:
the development practices of the people developing it are suboptimal at best; they’re constantly releasing at an extremely high cadence, where they don’t even spend the time to test or fix things… it often uses 1GB of RAM or more. For a TUI.
— logicprog, Hacker News
Both things are true at once. OpenCode is the most complete open coding agent available and it is moving fast enough to be occasionally unstable. The mitigation is boring and effective: pin a version you’ve tested for anything you depend on, and let the bleeding edge be a choice rather than an accident.
Anti-patterns: stop doing these
- Running with default permissions on code you don’t trust. Allow-everything-but-
.envis a fine default for your own repos and a bad one for anything else. Lockbashandedittoaskfirst. - Setting only one model. No
small_modelmeans you pay frontier rates for every title and summary. Set both. - Treating it as a Claude Code reskin. If you never write an
AGENTS.mdand never touch the Plan agent, you bought a multi-model harness to run it like a single-model toy. - Installing every MCP server you find. Each is permanent context cost. Five that earn their place beat fifteen that don’t.
- Putting theme keys in
opencode.json. They’re deprecated there and silently migrated. Theme and keybinds live intui.json. - Auto-updating production tooling. The cadence is a feature for explorers and a hazard for people shipping. Pin what you depend on.
Troubleshooting and gotchas
- A custom agent or command isn’t found. The directories are plural:
agents/,commands/,themes/. Check the name. default_agentsilently falls back to Build. An invalid agent name doesn’t error; it reverts. Verify the name matches a real agent.- Theme changes do nothing. They’re in the wrong file. Theme and keybinds belong in
tui.json, notopencode.json. - Huge monorepo, runaway disk or CPU. OpenCode keeps an internal git snapshot repo for undo/redo. On very large trees, set
"snapshot": false(you lose in-session undo). - Local model gives short, truncated answers. Raise the context window (
num_ctx) on the Ollama/llama.cpp side — small defaults choke long agent turns. - CI pulling a raw file 404s. The default branch is
dev, notmain. Adjust raw URLs and Actions refs. - A
ghcr.io/sst/opencodeimage stopped resolving. The project moved orgs; images are now underghcr.io/anomalyco/opencode. Update old references left over from the rename. - Inspecting state. Logs live in
~/.local/share/opencode/log/; runopencode --log-level DEBUGto trace a misbehaving session.
The drop-in starter pack
A complete, opinionated ~/.config/opencode/opencode.json that combines everything above — two models, a locked permission baseline, three MCP servers that earn their keep, Plan as the default, and secrets read from the environment:
{ "$schema": "https://opencode.ai/config.json", "model": "anthropic/claude-sonnet-4-5", "small_model": "anthropic/claude-haiku-4-5", "default_agent": "plan", "autoupdate": "notify", "share": "manual", "permission": { "bash": { "*": "ask", "git status": "allow", "git diff *": "allow", "git log *": "allow", "ls *": "allow", "cat *": "allow", "rg *": "allow", "rm *": "deny", "git push *": "deny" }, "edit": "ask", "webfetch": "ask" }, "mcp": { "playwright": { "type": "local", "command": ["npx", "-y", "@playwright/mcp@latest"], "enabled": true }, "grep-app": { "type": "remote", "url": "https://mcp.grep.app", "enabled": true }, "github": { "type": "remote", "url": "https://api.githubcopilot.com/mcp/", "enabled": true, "headers": { "Authorization": "Bearer {env:GITHUB_TOKEN}" } } }}The matching ~/.config/opencode/tui.json:
{ "$schema": "https://opencode.ai/tui.json", "theme": "tokyonight", "keybinds": { "leader": "ctrl+x", "command_list": "ctrl+p" }}Run it in Plan, argue the approach, Tab to Build, and let a model you chose execute against a plan you trust — on a tool no single vendor can switch off. That last clause is the only one that matters. Every other coding agent is a bet on a company. OpenCode is a bet on the format, and the format is the one thing a lawyer can’t revoke.
Sources & credits
The configuration in this guide is synthesized from the official OpenCode docs at release v1.16.2, the repository at anomalyco/opencode, and the threads and posts cited inline. Naming-dispute account from the Charm CEO’s statement; the Anthropic access timeline from issue #7410 and PR #18186; community sentiment from the linked Hacker News threads. Model recommendations reflect maintainer commentary and are a starting point, not a benchmark.