On June 7, 2026, Peter Steinberger told 536,000 followers to stop prompting their coding agents. Within a day the sentence had a name, a blog post, a backlash, and a place in a four-rung ladder of engineering disciplines that did not exist eighteen months ago. The name was “loop engineering,” and by the time it reached LinkedIn it was already being sold as the thing that made harness engineering obsolete.
We have watched this movie before. Prompt engineering became context engineering became harness engineering, each transition announced as a paradigm shift, each one mostly a rename of the layer the previous term had already been pointing at. So this time we did not write the explainer. We opened a sandbox, installed Claude Code with a live Anthropic key, and ran 47 agent loops to find out which of the claims behind the new word are measurable and which are vibes.
The short version: the naming is churn, and three of the underlying technical claims are real. One of them is real to the cent. This piece is the receipts for both halves.
The ladder, and why each rung looks like the last
Here is the lineage the discourse itself assembled, in its own words. Mike Taylor laid it out as a timeline:
2021: prompt engineering 2025: context engineering 2026: harness engineering also 2026: loop engineering
— @hammer_mt Jun 7, 2026
Carlos Perez posted the same chain with a question mark on the newest link, which is the more honest version:
Context Engineering -> Harness Engineering -> Intent Engineering -> (Loop Engineering?)
— @IntuitMachine Jun 8, 2026
Each term has a real origin. Context engineering was written up by Simon Willison in June 2025, crediting Tobi Lütke and Andrej Karpathy for popularizing it as the successor to prompt engineering. Harness engineering surfaced in March 2026 when Anthropic published “Harness design for long-running application development” and LangChain formalized Agent = Model + Harness. The Deep Feed shipped its own harness-engineering piece in May. Loop engineering crystallized on a single day in June.
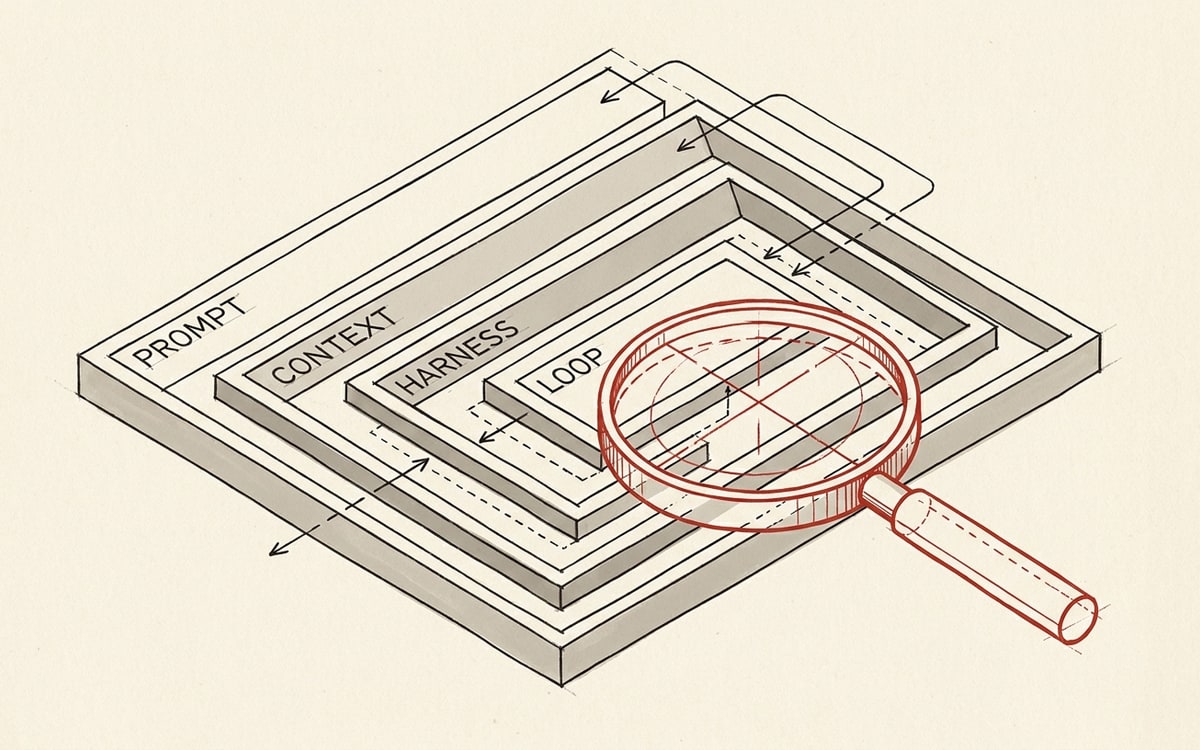
The reason each rung looks like the last is that each one names a thinner slice of the same object. A coding agent is a model wrapped in a loop that calls tools, carries context between iterations, and decides when to stop. “Context engineering” pointed at what you put in the window. “Harness engineering” pointed at the whole wrapper. “Loop engineering” points at the iteration structure inside the wrapper. These are not four disciplines. They are four zoom levels on one diagram, relabeled as the industry’s attention moved inward.
The clearest evidence that the labels are unstable is that the people coining them cannot agree on the order. The viral framing puts loop engineering after harness engineering, the newer and therefore more advanced rung. But Boris Cherny, who runs Claude Code at Anthropic, gave a year-by-year ladder that puts loops below harnesses, as a 2025 step that 2026 builds on top of:
Boris Cherny outlined how AI-assisted development has evolved each year: in 2023 you wrote code, in 2024 you prompted Claude to write it, in 2025 you wrote loops that prompted Claude, and in 2026 you build the harness that runs the loops.
— @TraffAlex Jun 7, 2026
So in the meme, loop engineering succeeds harness engineering. In the account of the person who builds the most-used coding agent on earth, the loop is the rung beneath the harness. Both cannot be the frontier. When a field cannot decide whether its newest term is above or below the term it replaced, the term is doing branding work, not technical work.
The shift under the rename, stated plainly
Strip the naming and there is a real shift underneath, and it is worth saying precisely so we can test it. Steinberger’s original line is the cleanest statement of it:
Here’s your monthly reminder that you shouldn’t be prompting coding agents anymore. You should be designing loops that prompt your agents.
— @steipete Jun 7, 2026
The unit of human work is moving up one level. You used to write the prompt. Now you write the thing that writes the prompt, runs the tool, checks the result, and decides whether to go again. That is genuinely different from prompt engineering, and the difference is not rhetorical: the artifact you maintain changes from a string to a control structure with a termination condition. Wei Zhan put the consequence well: the code stops being the thing you tune.
design the loop, define the verification function, set the routing policy, and let the agents fight it out. Code is the artifact — the loop is the product.
— @zench4n Jun 7, 2026
This is real, and it is also not new in 2026. The reason-act loop is ReAct, from 2022. The self-prompting autonomous loop is AutoGPT, from 2023. The “wrap an agent in a bash while-loop until the task is done” pattern got the nickname “Ralph” inside the HumanLayer community over a year ago. What changed in 2026 is not that loops exist; it is that the models got good enough that running an unsupervised loop is no longer a party trick, and that two frontier labs started telling people to do it on the same week. That coincidence is what gave the term its legs:
Anthropic and OpenAI both encouraging “writing loops” can’t be a mild coincidence
— @andrewqu Jun 7, 2026
So our test is not “is the loop new.” It is “are the specific engineering claims people are making about the loop true, and can you feel them in real numbers.” We picked the four claims that came up most, turned each into an experiment, and ran them.
How we tested: 47 loops in a disposable machine
The setup is deliberately reproducible. We booted a SuperServe Firecracker microVM from the claude-code template, which ships Claude Code 2.1.163 preinstalled, and injected an Anthropic API key as an environment variable so nothing touched disk. Every experiment ran Claude Code in headless mode with structured output, which is the part that makes this measurable rather than anecdotal:
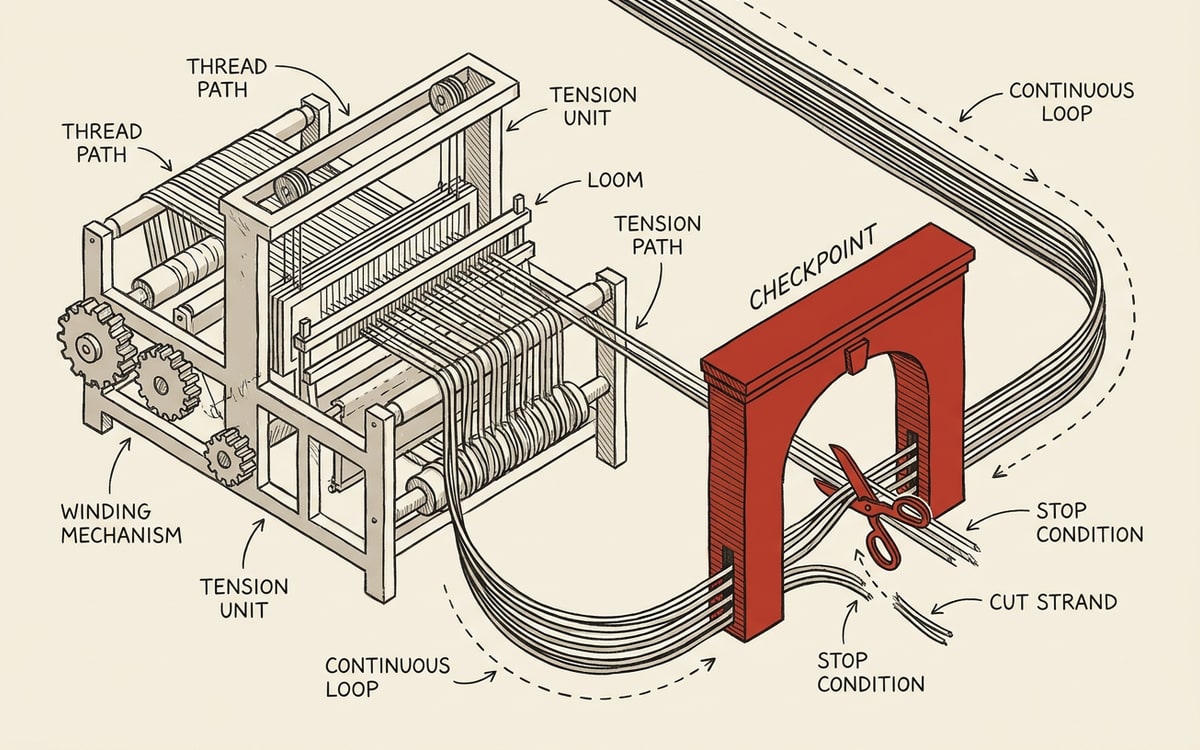
echo "PROMPT" | claude -p --model sonnet \ --allowedTools Write Bash Read \ --output-format jsonThe --output-format json flag turns each run into a record with three fields that matter: num_turns (how many times the loop went around), total_cost_usd (the actual Anthropic spend, to seven decimal places), and duration_ms. The model reported itself as claude-sonnet-4-6. Forty-seven runs across five experiments cost $1.77 of real tokens. Nothing below is simulated; every number came out of the CLI’s own accounting.
A note on honesty before the numbers: a sandbox study with a handful of repeats per arm is an existence proof, not a benchmark. Where an effect is small or noisy we say so. The point is not to publish a leaderboard. It is to check whether the claims behind a viral word survive contact with a real agent doing real work.
Claim 1: “the stop condition is the product”
The single best line in the entire discourse came from Aakash Gupta, and it is the one worth engineering around:
Writing the loop is the easy part. The hard part is the thing the loop checks before it decides to stop. A loop that prompts Claude answers one question on every pass: good enough, or run it again?
— @aakashgupta Jun 7, 2026
To test it we gave Claude Code the same task two ways. The task: parse a CSV of transactions and return the total. The two harnesses differed only in their stop condition.
The weak-stop version is how most people actually prompt:
echo "Write a function to parse a CSV of transactions and return the total.Put it in solution.py. Fix it until it works." \ | claude -p --model sonnet --allowedTools Write Bash Read --output-format json“Fix it until it works” is an undefined stop condition. The agent decides for itself what “works” means. The sharp-stop version hands the agent a failing test up front and names the exit condition in machine terms:
# test_parse.py already exists in the directory, asserting on known totalsecho "Make test_parse.py pass. Create solution.py.Run pytest and do not stop until pytest exits 0." \ | claude -p --model sonnet --allowedTools Write Bash Read --output-format jsonWe ran each arm three times, and then graded every result against a held-out test the agent never saw, including a negative refund row to catch naive implementations. Here is what came back:
| Arm | Mean turns | Mean cost | Mean duration | Held-out correct |
|---|---|---|---|---|
| Weak stop (“until it works”) | 4.0 | $0.0600 | 13.8s | 3/3 |
| Sharp stop (pytest exit 0) | 4.0 | $0.0560 | 9.5s | 3/3 |
On a task this simple, both arms got the right answer every time, so the honest headline is that the stop condition did not change correctness here. But it changed everything about efficiency: the sharp-stop loop was 31% faster and 7% cheaper, because it knew exactly when it was done instead of burning a round on self-doubt. And the deeper point is about why the weak arm succeeded at all. It got the right answer by luck. “Until it works” gave it no way to know it was finished, so it guessed, and on a trivial task the guess happened to be right. Scale that task up and the luck runs out. The verification function is the only thing that converts a loop from “stops when the model feels done” to “stops when the work is provably done.” Gupta’s co-signers said the same from the cost side:
The expensive part of a large agentic loop was never the model, it’s the loop that doesn’t know when to stop. Cheap model, unbounded iterations, still an unbounded bill.
— @MindTheGapMTG Jun 7, 2026
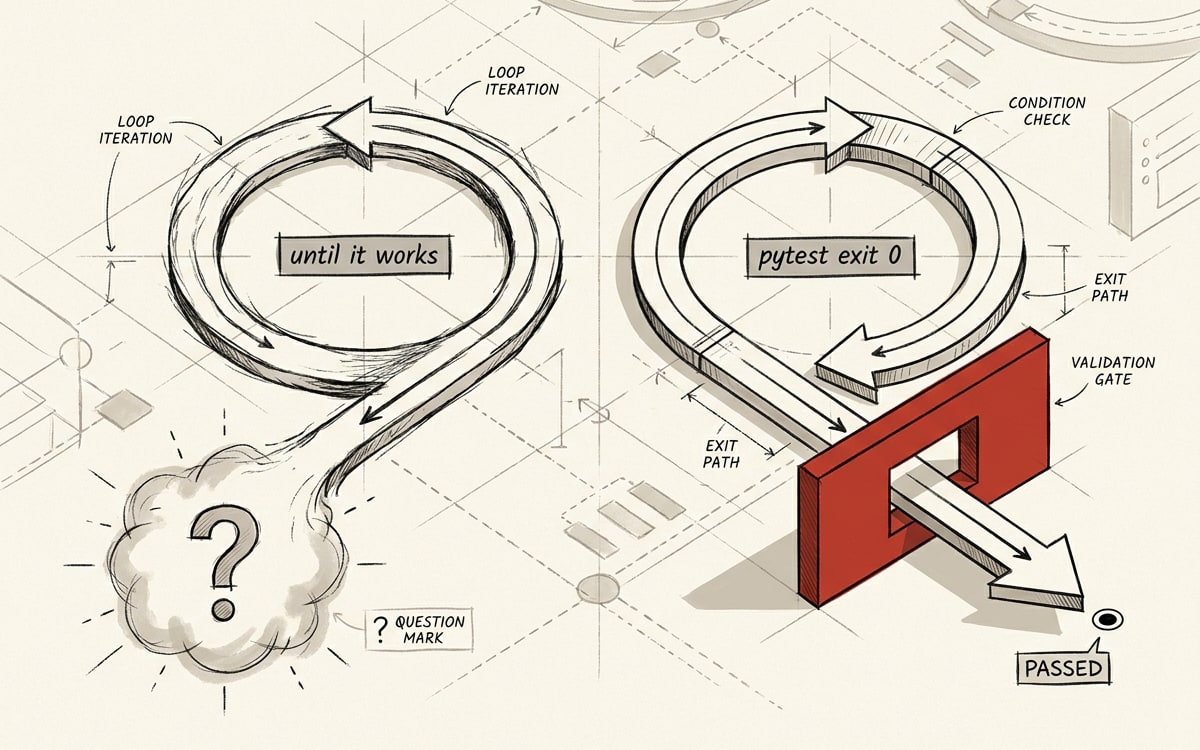
Verdict: real, and the most important claim in the set. The stop condition is not a detail of the loop. It is the loop’s specification. A loop without a sharp one is a slot machine that happens to write Python.
One real loop, from init to green
Because “design the loop” stays abstract until you watch one run, here is a real sharp-stop loop captured with --output-format stream-json --verbose. The harness handed Claude a failing pytest file and the instruction to iterate until it goes green. This is the entire loop, start to stop, four turns:
── INIT  model=claude-sonnet-4-6  cwd=/home/user/lab/exp5         stop condition = `pytest` exits 0
🧠 THINK   Let me read the test file first to understand what's needed.🔧 TOOL    Read: test_parse.py⬅️  RESULT  def test_basic_total(): ... assert parse_transactions(p) == 15.50           def test_negative(): ... assert parse_transactions(p) == 7.50
🔧 TOOL    Write: solution.py             | import csv             | def parse_transactions(filepath):             |     total = 0.0             |     with open(filepath) as f:             |         for row in csv.DictReader(f):             |             total += float(row["amount"])             |     return total
🔧 TOOL    Bash: pytest test_parse.py -v⬅️  RESULT  collected 2 items ... 2 passed
🧠 THINK   Both tests pass.✅ STOP    success — pytest green. turns=4  cost=$0.0552  dur=9506ms
Read → write → run → observe green → stop. The agent never asks the human “is this good enough,” because the test answers that question on every pass. This is what “design the loop” means in practice: you are not writing the solution, you are writing the gate the solution has to pass through, and then letting the model bang on the gate until it opens. The skill is in the gate.
Claim 2: “skills compound; re-deriving burns money”
The second claim is about what the loop carries between iterations and across runs. Renil framed it as a unit-of-reuse argument:
The reusable unit inside the loop is a skill, not a prompt. Loops that call sharp named skills compound; loops that re-derive everything just burn money.
— @renilzac Jun 1, 2026
This one is testable to the cent. The task: implement a rate limiter using a token-bucket algorithm, with tests, looping until pytest passes. We ran it two ways. The cold arm started in an empty directory. The skill arm started with a CLAUDE.md containing project conventions and a tested token-bucket snippet to reuse, the agent equivalent of handing someone a working reference instead of asking them to rederive the algorithm:
# CLAUDE.md (skill arm only)## Reusable pattern: token-bucket rate limiterUse a monotonic clock. Refill lazily on read. Tested shape: class TokenBucket: def __init__(self, capacity, refill_per_sec, time_fn=time.monotonic): ... def allow(self, key) -> bool: ...Test with a fake clock you advance manually — never time.sleep in tests.Three runs each:
| Arm | Run 1 | Run 2 | Run 3 | Mean cost | Mean turns |
|---|---|---|---|---|---|
| Cold (empty dir) | 6t / $0.103 | 6t / $0.099 | 8t / $0.169 | $0.1237 | 6.7 |
| Skill (CLAUDE.md) | 6t / $0.095 | 6t / $0.100 | 6t / $0.097 | $0.0970 | 6.0 |
The skill arm cost 21.6% less. But the mean undersells the real finding, which is in the variance. Every skill run finished in exactly six turns. The cold runs ranged from six to eight, and the eight-turn run cost $0.169 because the agent re-derived the token-bucket math from scratch, got the refill timing subtly wrong, and spent two extra rounds debugging its own arithmetic. The skill snippet did not just save tokens on average. It removed the failure mode where the loop wanders into a problem that was already solved. The agent the skill arm produced reused the proven shape verbatim:
class TokenBucket: def __init__(self, capacity, refill_per_sec, time_fn=time.monotonic): self.capacity = capacity self.refill_per_sec = refill_per_sec self.time_fn = time_fn self._tokens = defaultdict(lambda: float(capacity)) self._last = defaultdict(lambda: time_fn())
def allow(self, key: str) -> bool: now = self.time_fn() elapsed = now - self._last[key] self._tokens[key] = min(self.capacity, self._tokens[key] + elapsed * self.refill_per_sec) self._last[key] = now if self._tokens[key] >= 1: self._tokens[key] -= 1 return True return False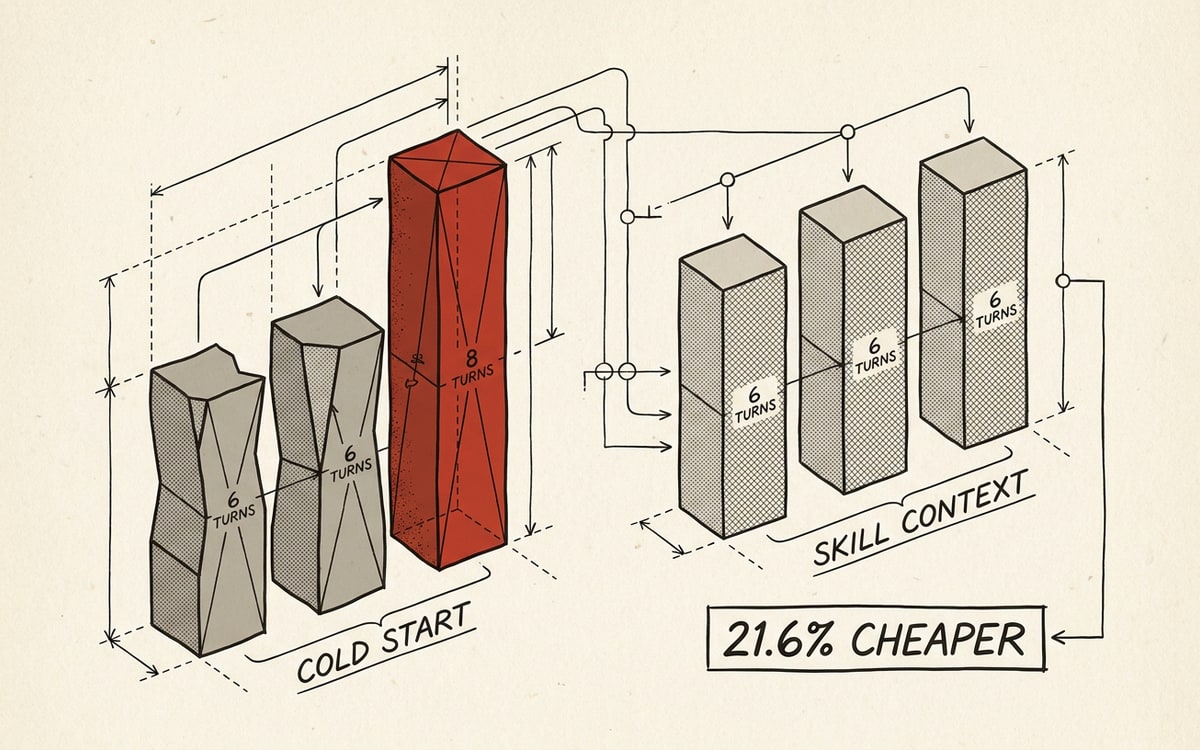
Verdict: real, and measurable. Re-derivation is where both the money and the variance live. A loop that calls a named, tested skill is not just cheaper on average; it is predictable, which on a bill that scales with iteration count matters more than the average.
Claim 3: “vague goals churn; tight slices converge”
The third claim is about the prompt that seeds the loop. The folk wisdom: a vague goal makes the agent wander, a tight issue slice makes it converge. We built a two-file repo with a naive slugify function and ran two prompts against it. The vague one: “Improve the codebase.” The tight one: “In utils.py, make slugify() handle unicode and empty strings; add 3 pytest tests. Run pytest until it exits 0.”
The result complicated the folk wisdom in a useful way:
| Arm | Mean turns | Mean cost | Produced tests? |
|---|---|---|---|
| Vague (“improve the codebase”) | 8.0 | $0.0981 | No (0 tests, both runs) |
| Tight (named function + tests) | 7.5 | $0.0940 | Yes (3 passing, both runs) |
The costs are nearly identical, which surprised us until we looked at why. A two-file repo physically bounds how far an agent can wander; there is not enough surface area to run away on. So the popular version of this claim, “vague goals cost more,” did not hold on a small repo. But the deliverable diverged completely. The vague arm edited both files based on its own guesses about what “improve” meant and produced zero tests in either run, unverifiable work with no green bar to stop on. The tight arm produced three passing tests every time. The vague loop’s own trace shows the wandering:
Bash find . -type f | head -50 # what is even here?Read main.pyRead utils.pyEdit utils.py # guessing at "improvements"Edit main.pyBash python main.py # does it still run?(no test file ever created — agent self-decided it was done)The danger of a vague goal, then, is not always cost. On a small repo it is something worse and quieter: motion without a contract. The agent does work, the work looks plausible, and nothing in the loop can tell you whether it helped, because no stop condition was ever defined. This is Claim 1 wearing different clothes. A vague goal is just a missing verification function at the input end of the loop.
Verdict: real, with a correction. Tight slices do not reliably cost less on small tasks. They produce verifiable output instead of confident guesses, which is the property that actually matters.
Claim 4: “the loop is expensive”
The loudest complaint about loop engineering is the bill. The funniest version:
Loop Engineering, Harness Engineering… whatever, my token bill still looks like I’m personally funding OpenAI’s next yacht. The loop is expensive.
— @ai_edisonZ Jun 7, 2026
So we measured what actually drives cost by running four tasks of increasing complexity, each test-gated:
| Complexity | Task | Turns | Cost | Duration |
|---|---|---|---|---|
| 1 | One pure function | 3 | $0.0482 | 8.2s |
| 2 | Function + tests | 5 | $0.0653 | 14.7s |
| 3 | Class + tests + edge cases | 6 | $0.0939 | 25.0s |
| 4 | Three-file module with CLI | 6 | $0.0655 | 14.8s |
The curve rises from a single function to a class with full edge-case tests, roughly doubling. But the revealing row is the last one. The three-file CLI module, which sounds like the biggest task, came in cheaper than the single-file class with exhaustive edge cases. More files did not mean more loop iterations. What drove cost was the number of distinct things the loop had to verify: every edge case is another round of write-run-check, and the edge-case-heavy class had more of those than the multi-file module did.
That reframes the cost complaint entirely. The loop is not expensive because it loops. It is expensive in proportion to how much verification you ask it to do. Which means cost is a design variable, not a fixed tax. You control it the same way you control the stop condition, by deciding what the loop must prove before it exits. The defenders of the term made exactly this point against the yacht jokes:
The global reaction that loops need a crazy token budget misses the point. There’s nothing forcing “loops” to be always-on token-burners.
— @tadasayy Jun 7, 2026
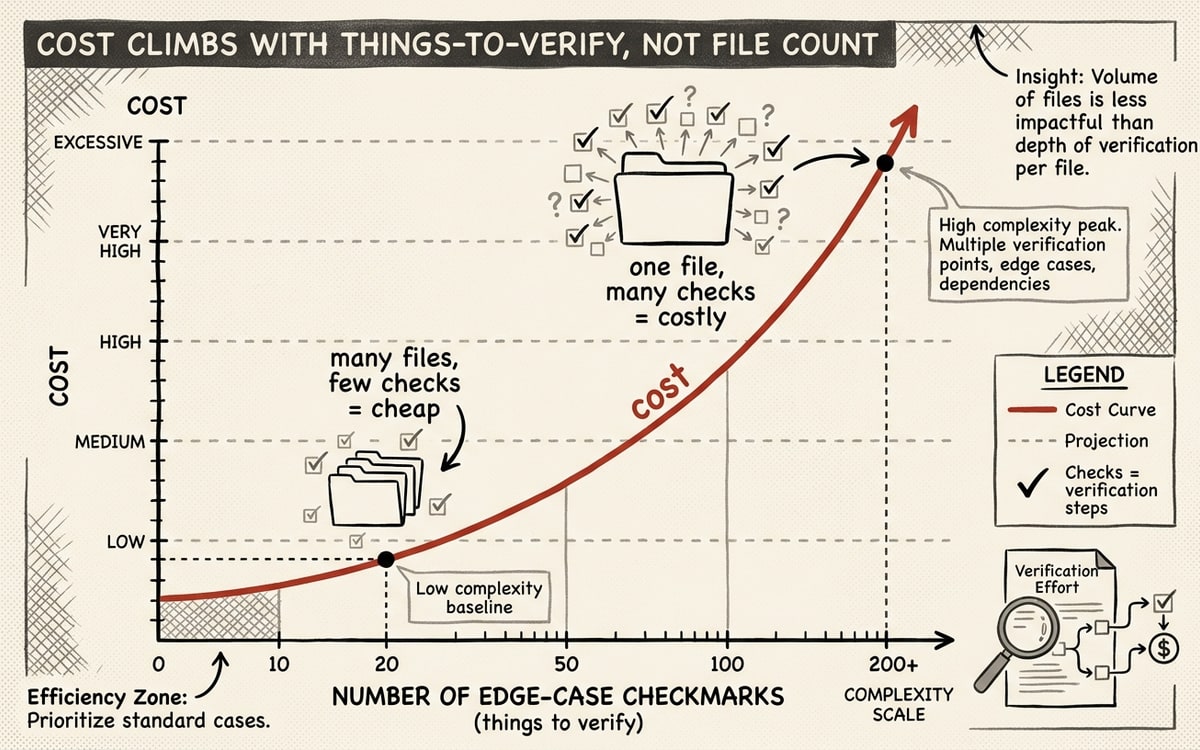
Verdict: real, but misattributed. The cost is not the loop’s. It is the verification surface’s. Cheap loops and expensive loops run the same control structure; they differ in how much they ask the model to check.
The backlash is right about the word and wrong about the work
The skeptics were the funniest people in the conversation, and on the narrow question of the name, they were correct:
Oh god, LinkedIn will now start a new fad, “Loop Engineering”. Harness Engineering is so last year. Loop Engineering is what you should be doing.
— @gauthampai Jun 7, 2026
That tweet got 943 likes ratioing the earnest ones, which tells you the room. And the prior-art charge is fair: people have been wiring agents into directed loops since AutoGPT, and the academic version of “act, observe, repeat” is older than the phrase. Gautham’s follow-up named it directly: this is “prompt to DAG,” which practitioners have done for a while, now with a fresh label.
But notice what our four experiments actually found. The naming is recycled. The engineering claims under it are not. The stop condition really is the product. Skills really do compound while re-derivation really does burn money and variance. Vague goals really do produce unverifiable motion. Cost really does track verification surface. None of those four findings depends on whether you call the activity loop engineering, harness engineering, or wiring a DAG. They are properties of running an autonomous agent against a gate, and they were true before the word and will be true after the next word replaces it.
That is the resolution of the believer-skeptic fight, and both sides are half right. The skeptics win the argument about the term: it is a rebrand, the ladder is incoherent about its own ordering, and the frontier will have a fifth word by autumn. The believers win the argument about the practice: the shift from tuning prompts to engineering verification loops is real, and the engineering decisions inside that shift have measurable consequences in turns and dollars. The mistake is thinking those are the same argument. The word is marketing. The verification function is engineering. You can ignore the first and you cannot ignore the second.
Four levers, measured
If you skip the discourse entirely and keep four things, keep these, because they are the four our runs support with numbers:
Write the gate before the solution. The sharpest lever in the entire 47-run set was handing the agent a failing test and an explicit exit condition. It made loops faster, cheaper, and verifiable, and it is the difference between an agent that stops when the work is done and one that stops when the model feels done.
Give the loop a memory of solved problems. A tested snippet in CLAUDE.md cut cost 21.6% and, more importantly, removed the eight-turn re-derivation blowup entirely. The reusable unit is the skill, not the prompt, and the payoff is variance reduction on a bill that scales with iteration.
Never seed a loop with a verb like “improve.” A vague goal does not save you work; it produces confident, unverifiable motion that you then have to review by hand, which is the cost the loop was supposed to remove.
Budget the loop by its verification surface, not its file count. Cost rises with the number of things the agent must prove, not the size of the codebase. If a loop is expensive, the question is not “how do I stop looping,” it is “what am I asking it to check, and does it need to.”
None of that requires the word “loop engineering.” It requires treating the stop condition as a first-class artifact, which is what every genuinely useful claim in this cycle reduces to. The term will be obsolete by the next time Anthropic ships a docs page. The verification function will still be the product.
We will keep the sandbox numbers updated as the models change. The word will have changed by then too.