xAI spent the back half of May shipping a coding agent, and the headline wrote itself: every major lab now has a terminal. Anthropic has Claude Code. OpenAI has Codex. Google has Antigravity. As of late May, xAI has Grok Build, a coding agent and CLI that installs with one curl command and runs inside your shell. The framing across the developer timeline was immediate and unanimous.
First look at Grok Build by @xai, this time as a CLI tool running directly in the terminal. This is clearly positioned as a competitor to Claude Code, bringing agentic coding workflows into the command line with xAI’s own model stack behind it.
— @mark_k May 9, 2026
That is the story most outlets ran: a fourth horse in the agentic-coding race. It is also the least interesting thing that happened. The interesting thing happened on June 1, when xAI added a model to Grok Build that it did not build, that it does not own, and that beats the model it does. To see why a company would ship a competitor’s product as the better option inside its own flagship, you have to stop looking at the terminal and start looking at the cap table.
What xAI actually shipped
Grok Build arrived in stages, which is part of why the through-line got lost. A closed beta opened to SuperGrok Heavy subscribers around May 14. On May 25, xAI published the formal launch post and widened access to all SuperGrok and X Premium Plus subscribers. The feature set is a faithful copy of the category leader, which is the correct strategy when you are fourth.
Plan mode is the default workflow. You describe a task, the agent drafts a plan, and nothing executes until you approve it, comment on individual steps, or rewrite it outright. Every change after that lands as a clean diff. From the launch post:
For complex tasks, start Grok Build in plan mode. You can approve the plan, comment on individual steps, or rewrite it entirely before execution begins. Once a plan is approved, every change shows up as a clean diff.
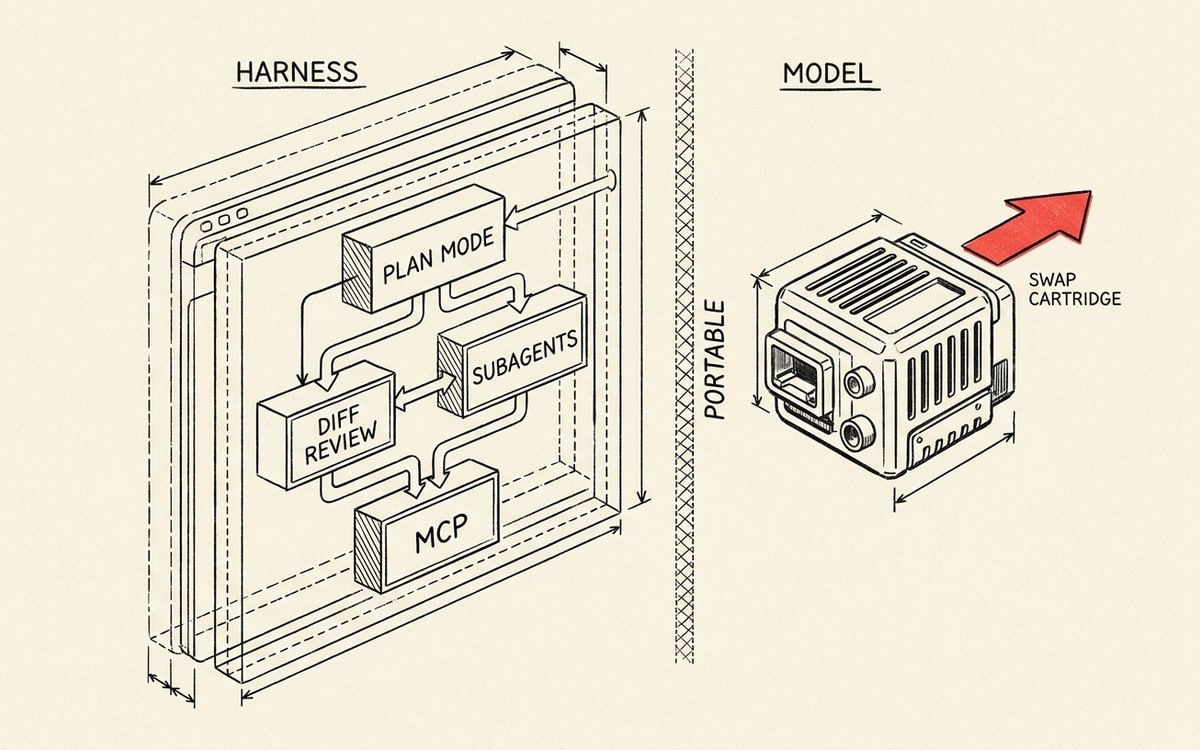
The compatibility surface is the tell. Grok Build reads your AGENTS.md, your plugins, your hooks, your skills, and your MCP servers “out of the box,” in xAI’s words. It speaks the Agent Client Protocol. It has a headless -p flag for CI pipelines. These are not arbitrary choices. They are the exact conventions Claude Code and Codex established, which means Grok Build is built to be a drop-in for a developer who already has a configured agent harness and wants to swap the engine without rewriting the car. The parallel-subagent model, where the agent fans work out to specialized subagents each running in its own git worktree, is lifted from the same playbook.
The reception was the reception every fourth entrant gets: a wave of interest, then a wave of friction. Within a day of the wide launch, enough users hit usage caps that xAI reset limits for every account and shipped a caching fix. The skeptics were louder than the boosters.
Agreed. It’s useless. I had just switched to SuperGrok Heavy thinking Grok Build would be worth it. But it’s pretty bad, and now all the censorship and usage limits. There really is no more advantage to Grok compared to the other AI labs.
— @Jay002 May 30, 2026
The defenders made the case that most complaints came from people who never got past the install:
I feel like 90% (if not 99%) of people complaining about limits with Grok Build actually didn’t try Grok Build. I’ve done a full week of working before hitting limits.
— @myrhex May 31, 2026
Both can be true. A fourth entrant ships rough, and a vocal slice of its early users are subscribers who upgraded on hype and want their money’s worth. None of that is the story either. The story is the model.
The brain is nine months old
On May 29, xAI put the engine on its API and gave it a name.
grok-build-0.1 is now available via the xAI API in public beta. This is the same model that powers the Grok Build CLI and excels at agentic coding. Priced at $1/m input and $2/m output, it’s extremely cost effective, intelligent, and fast.
— @xai May 29, 2026
A new model, a new version number, a fresh 0.1. Except it is not new. xAI’s own model documentation lists grok-build-0.1 with three aliases: grok-code-fast-1, grok-code-fast, and grok-code-fast-1-0825. That last suffix is a date stamp. grok-code-fast-1 is the model xAI launched on August 28, 2025, the one it gave away free for a week across Cline, GitHub Copilot, and Cursor to seed adoption. The documentation page for the “new” model still lives at the grok-code-fast-1 URL.
So the fastest coding model powering xAI’s new agent is a rebrand of a model that shipped nine months earlier. The specs match the 2025 release exactly: a 256,000-token context window, text and image input, function calling, structured outputs, and reasoning, served at 100-plus tokens per second. The pricing is the same economy tier xAI has run on this model since launch: $1.00 per million input tokens, $0.20 cached, $2.00 output on the xAI console, with a cheaper $0.20-in, $1.50-out tier exposed through OpenRouter.
This matters because of what it says about where xAI’s effort went. The lab did not train a frontier coding model to win the CLI race. It wrapped a known, fast, cheap, mid-tier model from last summer in a new harness and a new name. The investment was in the agent, not the intelligence. That is a defensible bet, since the harness is where Claude Code’s lead actually lives. But it leaves a hole exactly where a buyer looks first: how good is the model. And on June 1, xAI filled that hole with someone else’s model.
The model xAI didn’t make
Composer 2.5 is now available inside Grok Build. Composer 2.5 is a fast, highly intelligent model that excels on long-running tasks and following complex instructions.
— @xai June 1, 2026
Composer 2.5 is Cursor’s model. Cursor released it on May 18, built on the open-source Kimi K2.5 checkpoint and refined with large-scale reinforcement learning. It scores 79.8% on SWE-bench Multilingual and 63.2% on Cursor’s own CursorBench v3.1, numbers that sit alongside Opus 4.7 and GPT-5.5 in the frontier tier, at roughly a tenth of frontier cost. Until June 1, the only way to use it was inside the Cursor editor.
Now the only other way to use it is inside Grok Build. And it beats Grok Build’s own model on the benchmark that buyers cite: 79.8% on SWE-bench Multilingual for Composer 2.5 against roughly 70.8% on SWE-bench Verified for grok-build-0.1. The benchmarks are not identical tests, so the gap is directional rather than exact, but the direction is unambiguous and xAI is not hiding it. The company added a model to its /model menu, set it next to its own, and let any subscriber pick the one that codes better. That subscriber will pick Composer 2.5.
No company does this by accident. Shipping a rival’s superior model inside your own paid product is, on its face, a decision to undercut your own model’s reason to exist. It only stops looking irrational when you notice that xAI and Cursor are not really rivals anymore.
The cap table explains the product
The pieces have been assembling in public since spring. In February 2026, SpaceX merged with xAI, folding Musk’s AI lab into the rocket company at a combined valuation that the IPO filing would later put in the $1.75 trillion range. In April, xAI began supplying GPU infrastructure to Cursor for model training, tens of thousands of GPUs from xAI’s clusters. Composer 2.5 was trained on xAI’s Colossus 2 cluster. The model xAI just embedded was, in a literal compute sense, partly built on xAI’s own machines.
Then the financial tie. On April 21, SpaceX disclosed that it holds an option to acquire Anysphere, Cursor’s parent, for $60 billion, or to pay a $10 billion breakup fee if it walks.
SpaceX said in a post on X that it’s obtained the rights to buy coding startup Cursor for $60 billion later this year, or pay $10 billion for the work the companies are doing together.
— CNBC, April 21, 2026
The S-1 SpaceX filed on May 20 locked in the mechanics. The acquisition option becomes exercisable roughly 30 days after SpaceX begins trading on Nasdaq under the ticker SPCX, an IPO targeted for June 12. Read that calendar against the product calendar. SpaceX files to go public on May 20. xAI puts grok-build-0.1 on its API on May 29. xAI embeds Cursor’s Composer 2.5 in Grok Build on June 1. The IPO that arms the Cursor option is June 12. The product integration is not a coincidence sitting next to a financial event. It is the first user-visible proof that the financial event is real, shipped eleven days before the trigger.
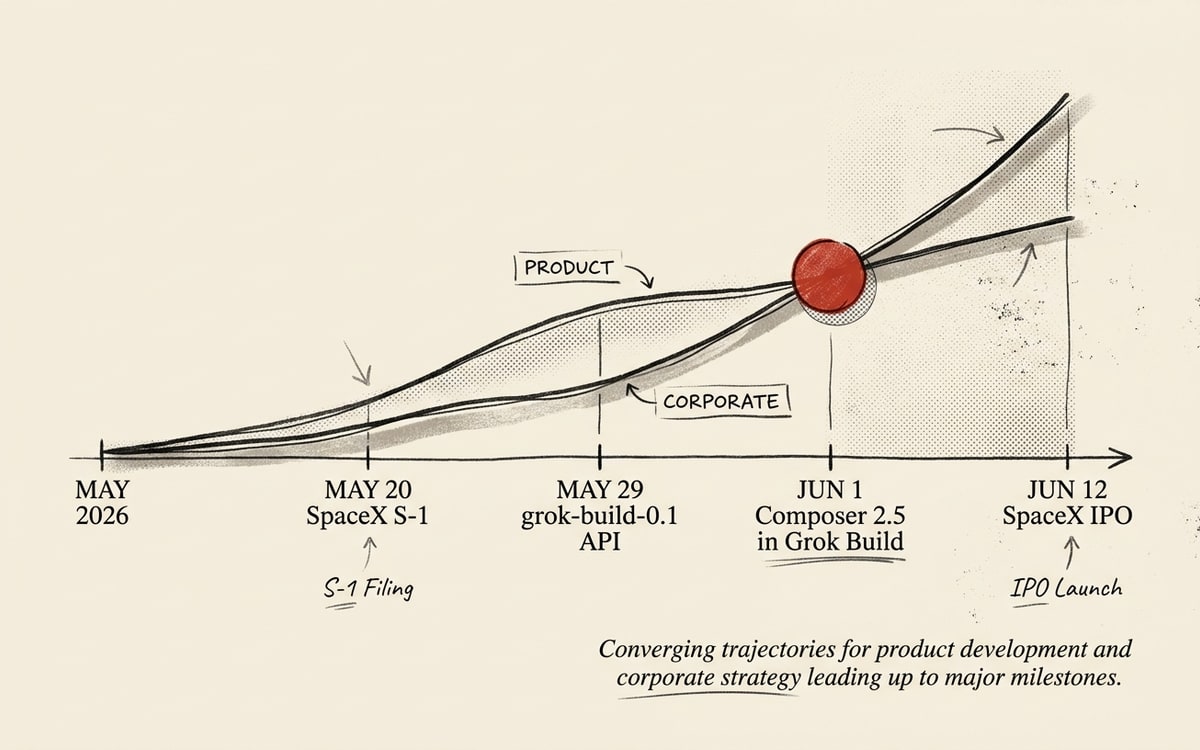
Viewed this way, the June 1 integration stops being a company undercutting itself and starts being a holding company routing its best asset to its most-used surface. The integration is bidirectional, which seals the interpretation: grok-build-0.1 is also listed in Cursor’s model menu. Two products, two model menus, one set of models flowing freely between them. That is not how competitors behave. It is how divisions of the same company behave.
Why the “CLI war” framing breaks
The clean version of the story has four labs racing for the same slot in your terminal. It is not wrong about the surface. There genuinely are four agents fighting for the same prompt, and developers are running the bake-offs in public, throwing identical tasks at Claude Code, Codex, Grok Build, and Cursor to see which builds a working Windows 98 simulation fastest. The competition for the terminal is real.
What the framing misses is that the terminal and the model have come apart. A coding agent in mid-2026 is two separable things: a harness (the plan mode, the diff review, the subagents, the MCP plumbing, the worktree integration) and a brain (the model that writes the code). The whole point of the AGENTS.md and ACP and MCP conventions that Grok Build adopted is that the harness is now standard enough to be portable. And once the harness is portable, the model becomes a component you slot in, not a moat you defend.
The clearest statement of where the fight actually moved came from a developer watching the launches stack up:
xAI shipped Grok Build, a terminal-based coding agent aimed directly at Claude Code and Copilot. Every major lab now has one: Codex, Claude Code, GitHub Copilot, Grok Build. The first wave competed on capability. Now they’re competing on UX, pricing, and which IDE you live in.
— @bphillipsai May 30, 2026
That is the right diagnosis with the wrong conclusion. The labs are competing on UX, pricing, and surface ownership, yes. But the deeper move is that the model layer underneath is consolidating while the surface layer fragments. xAI did not win the model race; it rebranded a nine-month-old model and then borrowed a better one from a company it is about to own. The terminal stays contested. The intelligence inside it pools.
| Grok Build | Claude Code | Codex CLI | Cursor | |
|---|---|---|---|---|
| Lab | xAI | Anthropic | OpenAI | Anysphere |
| Default model | grok-build-0.1 (was grok-code-fast-1, Aug 2025) | Claude Opus 4.x | gpt-5 family | Composer 2.5 (on Kimi K2.5) |
| Context | 256K | 200K | up to 400K | long-horizon |
| Best public benchmark | ~70.8% SWE-bench Verified | Opus 4.x SWE-bench Verified, top tier | varies by model | 79.8% SWE-bench Multilingual |
| Entry price | $99/mo intro, rising to $300 | $20-$200/mo | API metered | $20/mo + token tiers |
| Now also offers | Cursor’s Composer 2.5 | none | none | xAI’s grok-build-0.1 |
The bottom row is the whole story. Two of the four “competitors” now ship each other’s models, because two of the four are converging into one corporate entity. The other two, Anthropic and OpenAI, are racing on a different axis entirely: not whose terminal you use, but what the model can do. Anthropic’s proof point this cycle was not a CLI feature. It was Bun’s port from Zig to Rust, a single merged pull request of 1,009,257 lines across 2,188 files, written by Claude Code over nine days and passing 99.8% of the existing test suite. That is a capability claim, not a packaging claim, and it is the axis xAI conspicuously did not compete on.
What the integration actually signals
The temptation is to score this as a loss for xAI: the lab that had to borrow a model because its own was not good enough. That misreads the structure. xAI is not a standalone lab that failed to ship a frontier coding model. It is a division of a soon-to-be-public rocket company that holds a call option on the best independent coding model on the market. From that vantage, training a competitive frontier coding model from scratch would be redundant. Why spend the compute when you can route Composer 2.5 to your surface today and own the company that makes it in 30 days?
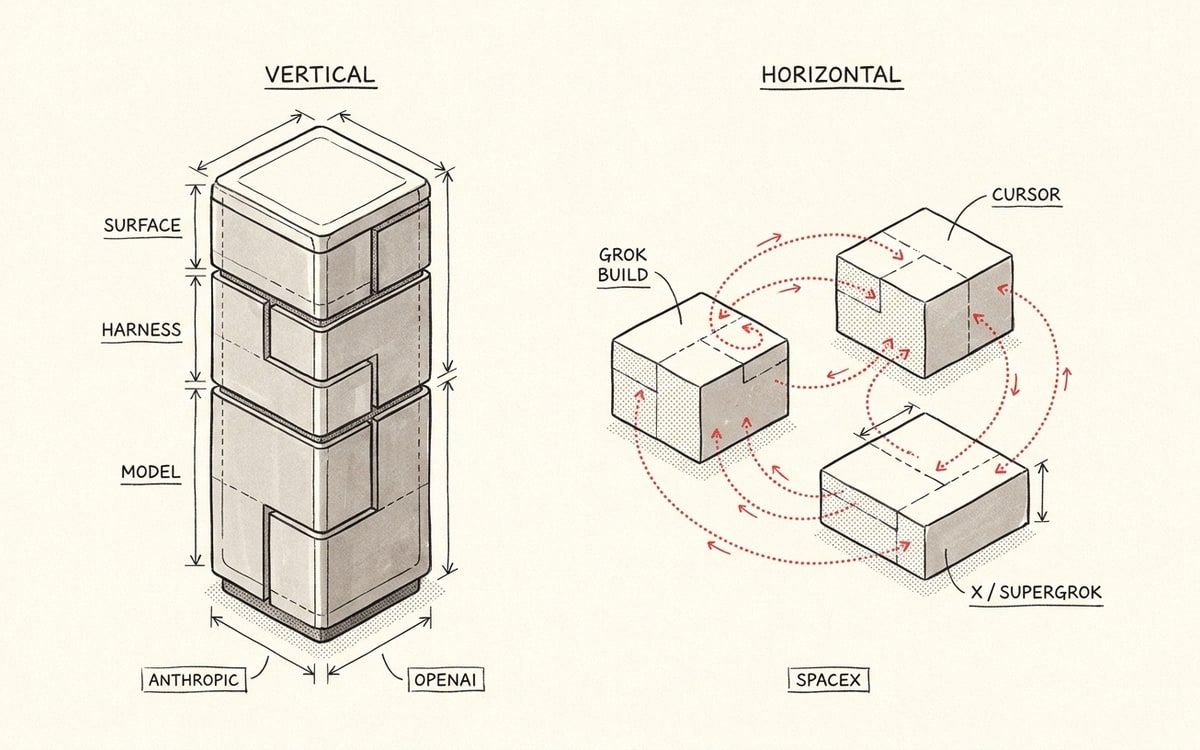
The honest read is that the coding-agent market is bifurcating along the seam between harness and model. On one side, Anthropic and OpenAI are vertically integrated: their own frontier model, their own harness, their capability lead defended by the model. On the other, the SpaceX stack is assembling horizontally: a harness (Grok Build), an editor (Cursor), a distribution surface (X, SuperGrok), and a set of models that move freely across all of them, with a $60 billion option turning the loose partnership into a single balance sheet.
The CLI war, then, is the visible weather over a slower tectonic move. Four agents will keep fighting for your terminal, and developers will keep running the bake-offs. But the question that decides the next year is not which terminal wins. It is whether the model stays a moat or becomes a part. xAI just answered for its half of the market. It put a rival’s model in its own product and let it win, because in the stack SpaceX is building, there is no rival. There is only inventory.