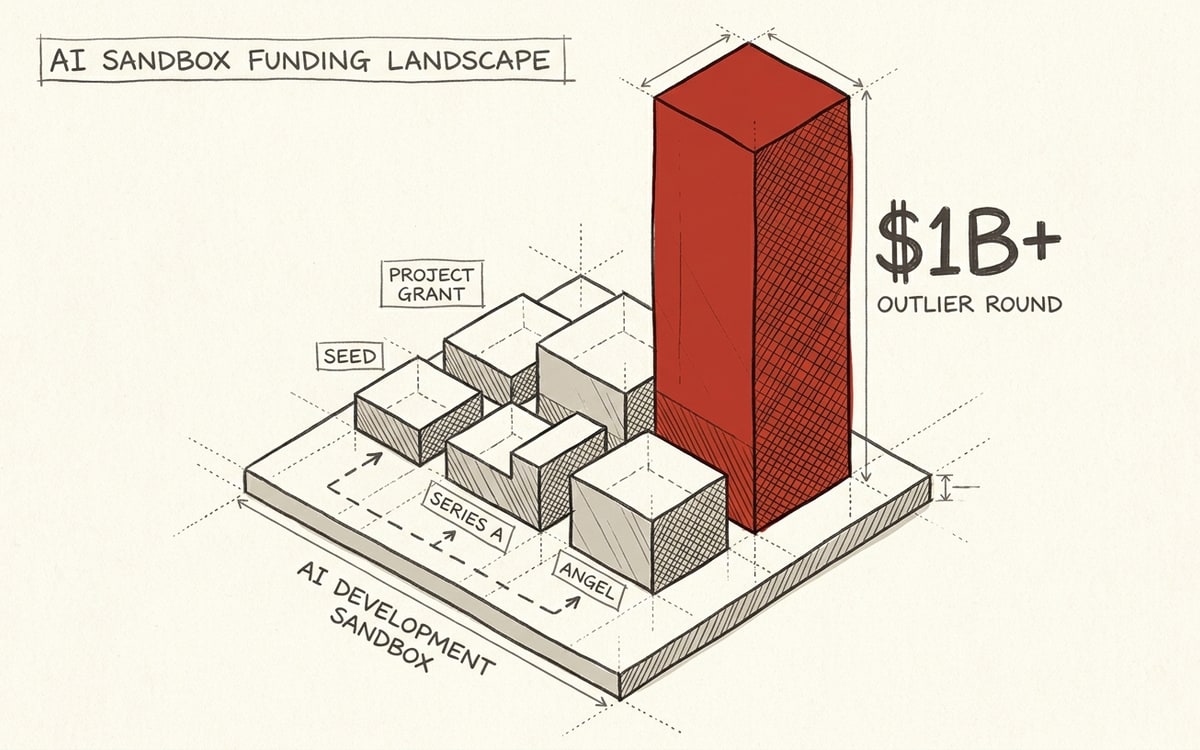
Modal raised $355 million in May 2026 at a $4.65 billion post-money valuation. Revenue had gone from roughly $60 million to over $300 million in six months, the company told Reuters. The round was led by General Catalyst and Redpoint, with Menlo Ventures, Bain Capital Ventures, and Accel joining. That valuation is not a GPU-leasing story. It is, increasingly, a sandbox story: the business of renting an AI agent its own isolated computer to run code in.
One account on X compressed the whole thesis into five sentences:
Modal raised $355M at $4.65B. Revenue went from $60M to $300M in 6 months. The growth isn’t GPU leasing. It’s AI agent sandboxes. Every agent builder needs isolated execution.
— @InfomlyLab May 21, 2026
That take overstates the clean attribution (Modal sells GPU compute and data pipelines too, not only sandboxes), but it names the right shift. When an LLM writes code, something has to run that code. It cannot run on your laptop, in your production process, or anywhere it can read a credential, delete a file, or open a socket it shouldn’t. It needs a box: a real, isolated, disposable computer that boots in milliseconds, runs untrusted output, and disappears. The unglamorous layer that provides those boxes has become a fundable category with at least 23 companies competing in it, three priced funding rounds inside six months, and a public benchmark war about to start.
This is the map. Who the players are, what they actually run underneath, where the real differentiation lives, what the money looks like, and what the operators, founders, and skeptics are saying about all of it.
A category nobody named two years ago
The clearest framing of why this layer exists came from Daytona’s CEO, who laid out the demand side in a thread that has aged well:
If you fail to understand the hype around the sandbox infra race, just look up the use cases they serve: Agents need environments to write code, preview it, and run it. Agents need full computer access to run browsers and execute tasks. For training and improving AI models through post-training, companies need to spin up 100k-200k environments simultaneously in about 3 minutes for RL training. When you need massive concurrency at scale, you can’t just take this capability off the shelf.
— @ivanburazin February 6, 2026
Three demand curves, one primitive. Coding agents like Lovable, Bolt, and Replit spin up hundreds of thousands of sandboxes to let users preview generated apps. Computer-use agents need a full desktop to drive a browser. And reinforcement-learning pipelines need to reset tens of thousands of identical environments per minute to train the next model. The same disposable-Linux-box primitive serves all three, which is why a coding-sandbox company and an RL-environment company increasingly look like the same business viewed from opposite ends.
The category is not the same as three adjacent things it gets confused with. It is not a CI runner; those are slow, trusted, and built for your own code, not an LLM’s. It is not a cloud dev environment like the old Daytona or Gitpod, which are built for humans typing, with IDEs and warm caches and hour-long sessions. And it is not browser automation like Browserbase or Steel, though browser sandboxes are a specialized branch of the tree. What defines an agent sandbox is the combination: untrusted-code isolation, sub-second creation, programmatic SDK control, and disposability at massive concurrency.
Grok, asked to read the market chart, drew the boundary about as well as anyone:
The coding-focused ones (E2B, Runloop, Daytona, AIO Sandbox, CodeSandbox) aren’t fully generic: they’re built for AI agents with microVM isolation for untrusted LLM code, fast ephemeral sandboxes, agent SDKs, state persistence/snapshots for multi-turn workflows, and templates integrating agent frameworks. They target the agent niche vs broad PaaS like AWS/Docker. The space is fragmenting into agent-specialized infra.
— @grok May 26, 2026
“Fragmenting into agent-specialized infra” is exactly right. Two years ago you ran agent code in a Docker container and hoped. Today there are 23 companies arguing about the right way to do it, and the argument starts one level below the SDK — at the isolation boundary itself.
The substrate war is nearly settled, with one $4.65B holdout
Strip away the landing pages and most of these companies run the same thing underneath: a microVM. Specifically, most of them run Firecracker, the open-source virtual machine monitor AWS built to run Lambda and Fargate. Firecracker’s pitch is the resolution of an old tradeoff. Containers are fast to boot but share the host kernel, so a container escape is a host compromise. Full VMs give you a separate kernel and real hardware-level isolation but boot in seconds. Firecracker gives you a real VM, with a separate guest kernel and separate userspace, that boots in tens of milliseconds. For running untrusted code that an LLM just wrote, that is close to the ideal trust model, because it is the exact trust model AWS designed it for: multi-tenant execution of code you do not trust at scale.
One engineer who maintains Firecracker-based playgrounds put the dominance plainly:
Where it runs in production: AWS Lambda, AWS Fargate, fly.io (whole platform), Kata Containers, E2B, Modal, Daytona (AI-agent sandboxes). Untrusted code at millisecond scale is almost always Firecracker underneath.
— @persikbl May 25, 2026
He is mostly right, and one of his examples is wrong in a way that matters. Modal, the category’s biggest, best-funded player, does not run Firecracker. It runs gVisor, Google’s userspace kernel that intercepts and reimplements syscalls, on top of a custom Rust scheduler spread across 13 cloud suppliers. That is a container-class isolation primitive, not a hardware microVM. The richest company in the category looked at the consensus choice and bet the other way.
This is the most interesting fault line in the whole map, so it is worth stating precisely. The real isolation axis is not open-source versus closed. It is a three-way split:
| Isolation tier | Mechanism | Who runs it |
|---|---|---|
| 🟢 Hardware microVM | Separate guest kernel via KVM (Firecracker, Cloud Hypervisor, QEMU) | E2B, Vercel, Fly Sprites, Superserve, Leap0, Qbox, CodeSandbox, Tensorlake, Runloop, Morph, Freestyle, SmolVM, Box, OpenComputer |
| 🟡 gVisor / syscall interception | Userspace kernel intercepts guest syscalls | Modal, Beam |
| 🔴 Containers / namespaces | Shared host kernel, namespace + cgroup isolation | Cloudflare (Containers + Durable Objects), OpenSandbox, Novita, Steel |
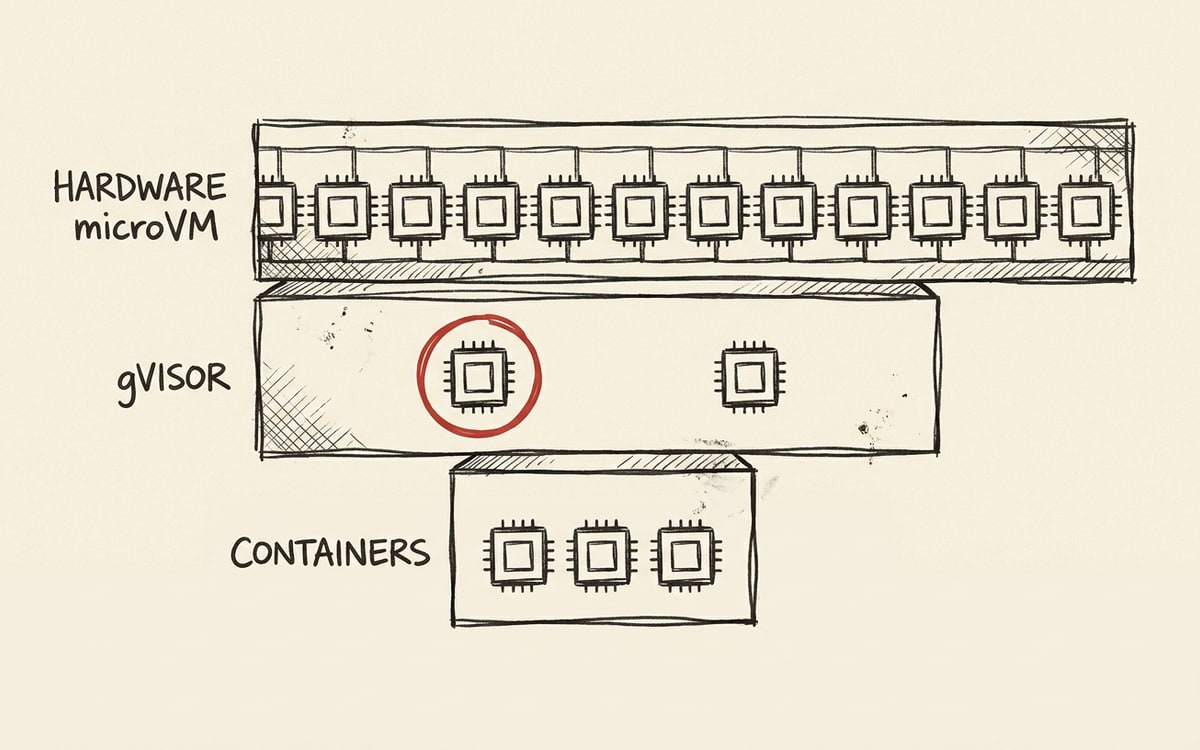
The microVM tier is crowded because it is the security-maximalist default and because Firecracker is free. The interesting bets are the deviations. Modal’s wager is that gVisor plus a strong scheduler plus aggressive memory snapshotting is enough isolation, and that the engineering it frees up (multi-cloud GPU scheduling, sub-second cold starts on containers) buys more than hardware virtualization would. Cloudflare’s wager is that its existing Containers-on-Durable-Objects platform, already deployed to every edge location, beats standing up a microVM fleet. Both are defensible. Neither is the consensus. And that is the point: the substrate looks settled until you notice the two companies with the most distribution both declined to follow it.
The Firecracker enthusiasm in the developer community is real and slightly breathless. A representative reaction:
Millisecond start times on Firecracker is wild, that’s a huge leap for agent deployment.
— @Dev__F May 20, 2026
And a sharper, more cynical version of the same observation — that AWS has the technology to dominate this category and is not shipping it as a product:
You know amzn is done when you don’t hear about a 2 pizza team that built an agent sandbox product in aws that uses firecracker and lets you fork vms in 10s of ms, and sell like crazy.
— @twofifteenam February 24, 2026
AWS invented Firecracker and sells it to nobody as an agent sandbox. The startups built the product layer on top of Amazon’s own kernel technology. That gap, between owning the primitive and shipping the product, is the entire opportunity these 23 companies are filling.
The money: three priced rounds and a lot of seed
The funding map is what turned this from a feature into a category. Three rounds inside six months put real valuations on the table, and the gap between them tells the story of the market’s shape.
| Company | Round | Amount | Valuation | Lead | Date |
|---|---|---|---|---|---|
| 🟢 Modal | Series C | $355M | $4.65B post | General Catalyst + Redpoint | May 21, 2026 |
| 🟡 Daytona | Series A | $24M (€20.4M) | $125M | FirstMark Capital | Feb 5, 2026 |
| 🟡 E2B | Series A | $21M | n/d ($32M total) | Insight Partners | Jul 28, 2025 |
| 🟢 Runloop | Seed | $7M | n/d | The General Partnership + Blank Ventures | Jul 30, 2025 |
| 🟢 Blaxel | Seed | $7.3M | n/d | First Round Capital | Jul 2025 |
| 🟢 Beam | Seed | ~$3.6M | n/d | Tiger Global, Uncorrelated, Y Combinator | — |
Modal is in a class of its own at $4.65 billion, but Modal is also the broadest of these companies — GPU compute, data pipelines, and sandboxes, not a pure-play. The two pure-play sandbox rounds that matter are Daytona’s $24M Series A at a $125M valuation and E2B’s $21M Series A. Both are early-stage bets on the picks-and-shovels thesis: don’t build the agent, build the layer every agent stands on.
Several of these companies are products of much larger parents, which changes the competitive calculus. Vercel Sandbox is a feature of Vercel, which raised a $300M Series F at $9.3 billion in September 2025. Sprites is a Fly.io product; Fly raised a $70M Series C in 2023. Cloudflare Sandboxes is a product of a public company. Islo is built and funded internally by Incredibuild, the Tel Aviv build-acceleration firm that took $140M from Insight Partners in 2021. OpenSandbox is an Alibaba open-source project. These are not startups racing to a Series A; they are incumbents extending a platform, and they can afford to price sandboxes as a loss-leader to keep developers inside the walls.
A note on rigor, because the aggregators are unreliable here. Two funding figures circulating for this category do not survive a primary-source check. Morph is widely listed with a “$22.8M” raise that no primary source corroborates — and the name collides with at least three unrelated companies (an L2 chain, a YC company called morphllm, and Morphic). Steel.dev appears in one aggregator with a “$17M Series A, founded 2022,” which contradicts Steel’s own “founded 2024” and almost certainly conflates it with Browser Use, which did raise $17M from Felicis. We are not asserting either number. When the founder of one of these companies disagrees with the aggregator about what year they started, the aggregator loses.
The traction numbers, where companies disclose them, are the better signal anyway. Modal’s $300M+ ARR is the largest. Daytona reports 850,000 agent runs per day, up 74% month-over-month — a figure its CEO has repeated in interviews and that shows up in the community:
Daytona provides secure, elastic infrastructure for running AI-generated code and agent workflows in isolated sandbox environments. Sandboxes spin up in under 90ms from code to execution. Full composable computers with dedicated kernel, filesystem, and network stack. Stateful environment snapshots enable persistent agent operations across sessions.
— @GithubProjects May 28, 2026
There is one trap buried in Daytona’s numbers that anyone drawing a market chart needs to know about. Daytona’s GitHub repository has roughly 72,500 stars — by far the most in the category, more than ten times E2B’s. Those stars are not a sandbox-adoption signal. They accrued when Daytona was an open-source dev-environment manager, a Gitpod competitor founded in early 2024. The company pivoted to agent sandboxes in mid-2025, threw away $300,000 of existing revenue to do it, and hit $1M ARR in under 90 days on the new product. The star count measures the popularity of a product the company no longer sells. Put it on a chart as a proxy for sandbox traction and the chart lies.
Cold start is the headline metric, and most of the numbers are marketing
Ask any of these companies what makes them special and the first answer is a number measured in milliseconds: how fast can they hand an agent a running computer. It is the right metric to care about — when an agent fans out to a hundred parallel sandboxes, a 2-second cold start is 200 seconds of wasted wall-clock and a worse product. But almost every published figure is a vendor self-benchmark, run on the vendor’s ideal image, and they are not comparable.
Here is the claimed landscape, sorted fastest first, with the caveat attached to each:
| Provider | Claimed cold start | Source type |
|---|---|---|
| 🟢 Tencent Cloud Agent Runtime | <60–80ms | Vendor (KVM + RustVMM) |
| 🟢 Blaxel | ~25ms resume from standby | Vendor self-benchmark |
| 🟢 Daytona | <90ms | Vendor (measured ~0.75s by a third party) |
| 🟡 Vercel Sandbox | ~125ms | Vendor |
| 🟡 Leap0 | ~200ms | Vendor (official; not the “~100ms” sometimes cited) |
| 🟡 E2B | <200ms | Vendor (0.515s, fastest, in an independent 5-way test) |
| 🟡 Superserve, Novita | <200ms | Vendor |
| 🟡 Morph | <250ms branch | Vendor (Infinibranch) |
| 🟡 Tensorlake, Fly Sprites | <300ms | Vendor |
| 🟡 Modal | ”sub-second” | Vendor (memory + GPU snapshots) |
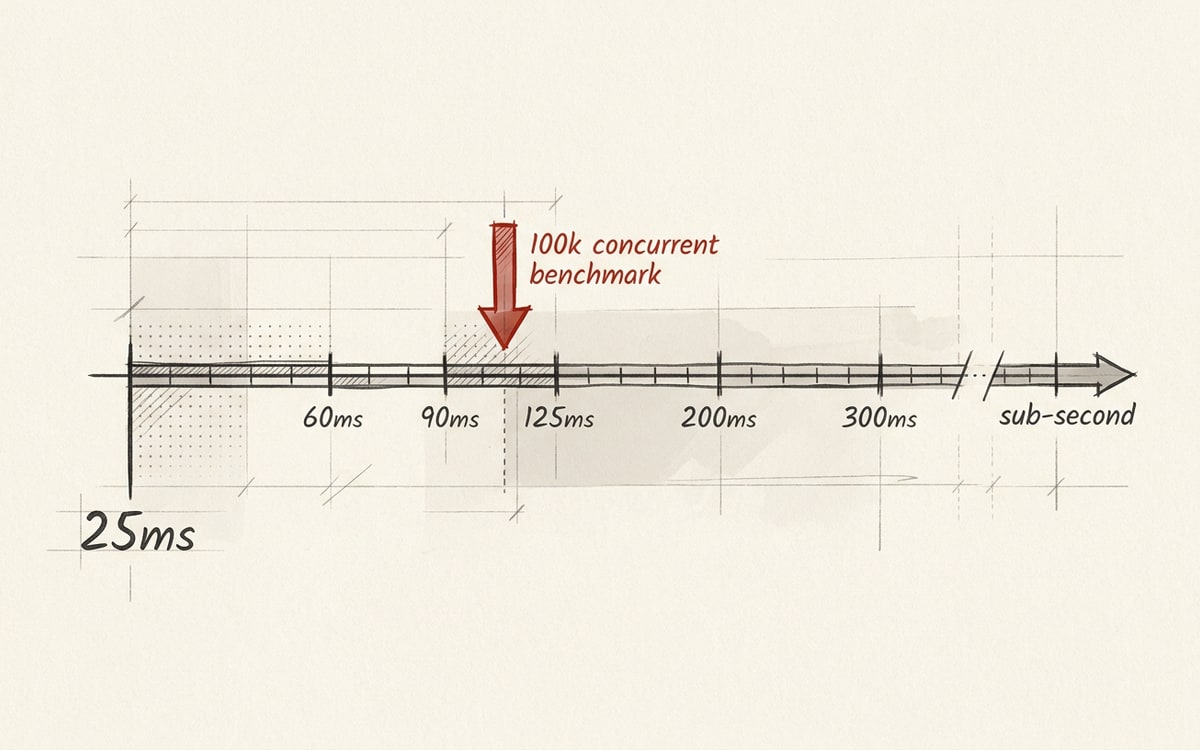
The pattern to notice: the claimed numbers cluster between 25ms and 300ms, and the gap between “claimed” and “measured” is often an order of magnitude. Daytona claims sub-90ms and a third-party test clocked it closer to 0.75 seconds. E2B claims sub-200ms and an independent five-provider benchmark put its real cold start at 0.515 seconds — which was still the fastest in that test. The honest reading is that nobody in this category is slow, the differences between the leaders are within measurement noise on a good day, and the marketing numbers are aspirational best-cases.
This is exactly why the most important event in the category is not a funding round. It is a benchmark:
SCALE. So on June 1st @modal @tensorlake @RunloopAI @northflank @declaw_ai and @e2b have accepted the most ambitious sandbox scale test we’ve ever run. 100k sandboxes running concurrently.
— @computesdk May 22, 2026
ComputeSDK runs a public leaderboard that measures Time-to-Interactive (median, P95, and P99 startup latency plus success rate) with the methodology and raw data on GitHub. The June 1 test puts six providers (Modal, Tensorlake, Runloop, Northflank, declaw, E2B) on the line for 100,000 concurrent sandboxes. That is the number that matters, because concurrency-at-scale is where the vendor demos quietly fall over and where the RL-training customers actually live. When the results land, half the cold-start marketing in this post becomes adjudicated fact instead of vendor claim. That is the moment the category has been missing.
Snapshot, fork, branch: Git for agent state
If cold start is the metric everyone leads with, snapshotting is the feature that actually separates the field — because it is harder, and because it enables the workflows that justify the category’s existence. The idea: freeze a running sandbox’s entire state (filesystem, memory, processes) and clone it instantly into N children. An agent installs its dependencies once, snapshots, and then forks a hundred copies to explore a hundred solution branches in parallel, each child a full running computer that resumes exactly where the parent left off.
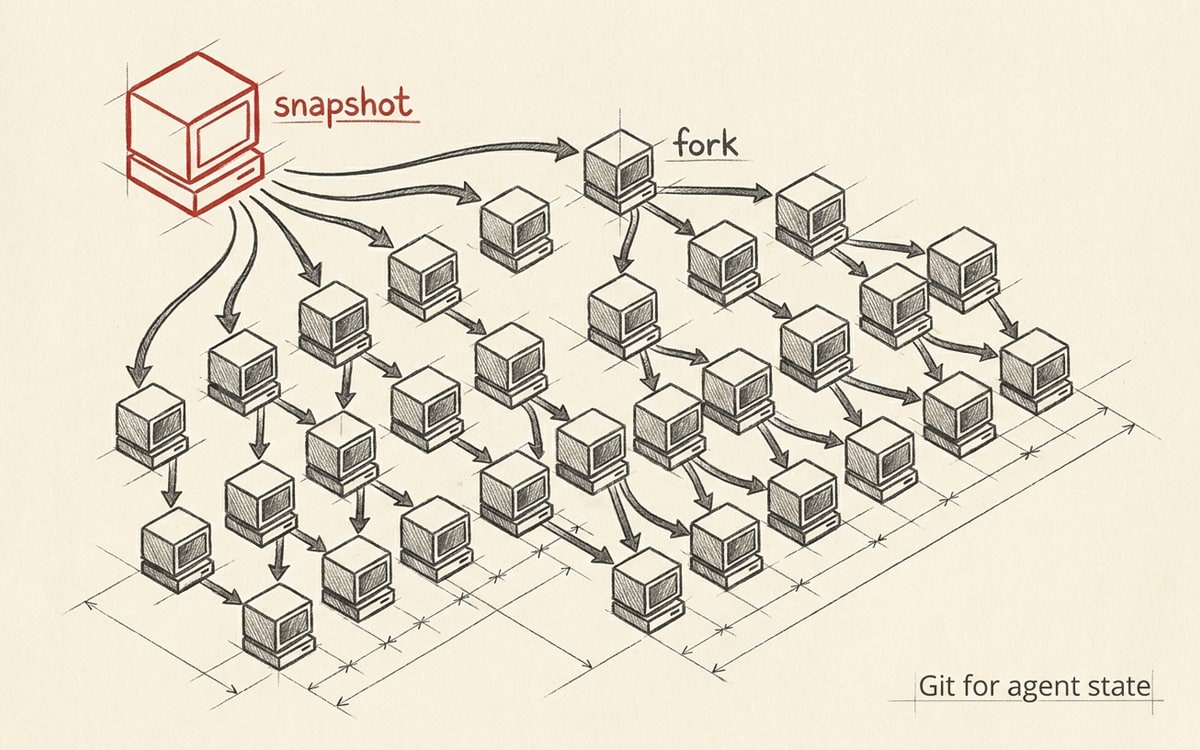
The vocabulary the category has settled on is “Git for agent state,” and the implementations differ in what exactly they can freeze:
| Provider | Snapshot capability | What it freezes |
|---|---|---|
| 🟢 Morph (Infinibranch) | Instant branch | Full VM: disk + memory + processes |
| 🟢 CodeSandbox | <2s clone, memory resume | Filesystem + memory + process state |
| 🟢 Modal | 3 snapshot types | Filesystem, memory, GPU memory |
| 🟢 Runloop | Snapshot + branch | Disk snapshot, suspend/resume |
| 🟡 Fly Sprites | CoW checkpoint ~300ms | Copy-on-write filesystem |
| 🟡 Vercel Sandbox | Clone / fork / resume | Filesystem snapshot |
| 🟡 Cloudflare | R2-backed snapshots | Filesystem (memory resume on roadmap) |
| 🟡 Tensorlake | Snapshot → clone → replicate → live-migrate | Full state + live migration across hosts |
The deepest version of this is full-VM branching with memory included, which is what Morph’s Infinibranch and CodeSandbox’s hibernation do — you can fork a sandbox mid-computation and the children inherit the exact RAM state, no re-warming. That is the feature RL pipelines and SWE-bench harnesses care about, because resetting an environment to a known checkpoint thousands of times per minute is the inner loop of training. The shallower version is filesystem-only snapshotting, which is cheaper to build and sufficient for the common case (install dependencies once, clone the disk) but forces a cold process restart on every fork.
GPU memory snapshotting, which Modal shipped in mid-2025, is the frontier: freezing not just CPU RAM but the state loaded onto the GPU, so an agent that has loaded a model into VRAM can be checkpointed and resumed without paying the multi-second model-load cost again. For agents that touch large models, that is the difference between a snapshot being useful and being theater.
The part enterprises actually pay for: credential governance and BYOC
Here is the counterintuitive finding from reading every one of these companies’ pitches: the millisecond cold start is what they market, but the governance layer is what closes enterprise deals. An agent sandbox that boots in 25ms but leaks your AWS keys is worthless to a bank. The companies that understand this have moved their differentiation away from speed and toward two features that are boring to demo and impossible to skip: credential brokering and bring-your-own-cloud.
The credential problem is specific. An agent needs to call your database, your Stripe account, your internal APIs — but the code running in the sandbox is untrusted LLM output. If the credentials live inside the sandbox, a prompt injection or a hallucinated curl can exfiltrate them. The fix the leaders have converged on is a broker: the credentials never enter the sandbox at all. The sandbox makes an outbound request, an egress proxy injects the credential on the way out, and the agent never sees the secret. Vercel, Superserve, Cloudflare, Islo, and Runloop all ship some version of this. The cleanest articulation came from a builder explaining why the happy-path demo and the enterprise reality are different products:
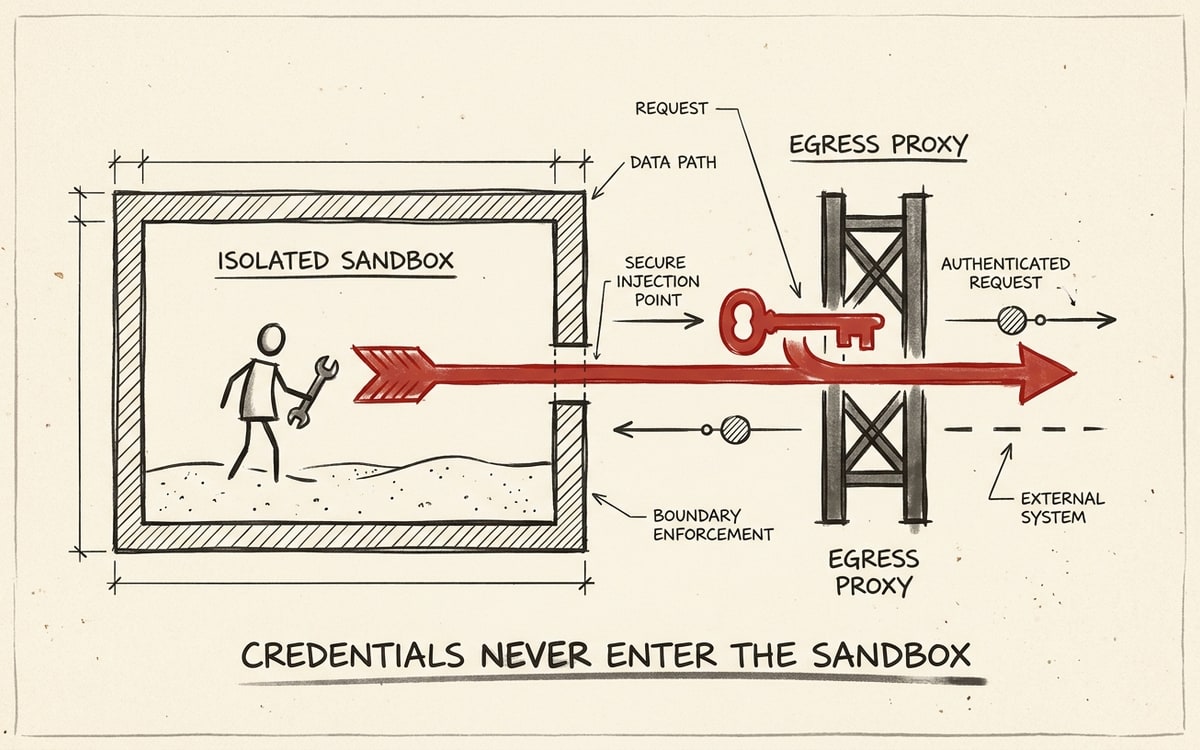
Most “AI agent” demos run in a happy cloud sandbox. Enterprise AI can’t. It needs to run inside your VPC, touch your data, and never leak credentials. We surveyed @e2b, Daytona, @RunloopAI, @modal and others. Then built our own.
— @vvkcnd May 27, 2026
That last sentence, “then built our own,” is the recurring threat to this entire category, and we will come back to it. But note the requirement: run inside your VPC. That is the second governance feature, bring-your-own-cloud, and it is where the enterprise-focused players have planted their flag. Instead of running the agent’s sandbox in the vendor’s cloud, the sandbox runs inside the customer’s own AWS, GCP, or Azure account, so the data and the execution never leave the customer’s security perimeter. Tensorlake’s founder described the mechanism precisely:
We are doing something similar for @tensorlake sandboxes. Dataplane in private networks of customers connect to Tensorlake with an mTLS outbound connection. Once that is setup, users call Tensorlake APIs, and sandboxes land in their private networks!
— @diptanu May 28, 2026
Tensorlake, Islo, Runloop, and Daytona all offer some form of in-VPC execution. Notably, the biggest player does not: Modal has no bring-your-own-cloud story, which is its clearest enterprise gap and the wedge its smaller competitors are aiming at. When the buyer is a regulated enterprise rather than a YC startup, “runs in your VPC with mTLS and credential brokering” beats “boots 50ms faster” every time. The speed race is for the developer-tools market. The governance race is for the money.
The convergence nobody planned: sandboxes are RL environments
The most important structural fact about this category is that it is quietly merging with a second one. A sandbox that runs an agent’s code and an environment that trains a model through reinforcement learning are, at the infrastructure level, the same thing: an isolated, resettable computer that executes untrusted actions and reports back a result. The coding-sandbox companies are discovering they have built RL infrastructure by accident, and the RL-infrastructure companies are discovering they need sandboxes.
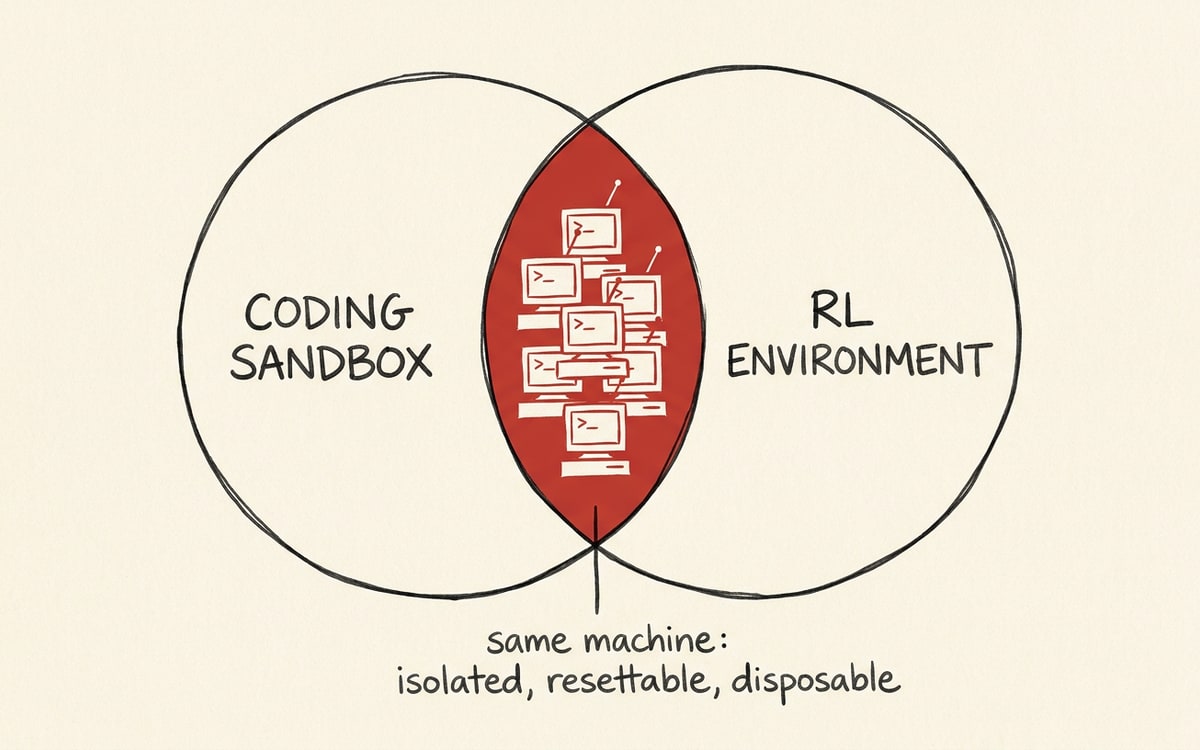
The clearest statement of the stakes came from Tencent, which is operating at a scale that dwarfs the startups:
.@MiniMax_AI is now working with Tencent to explore 100K+ concurrent Agent RL sandbox deployment. In Agentic RL, your model improves as fast as your environments can reset. Running Forge on Tencent Cloud Agent Runtime Sandbox: 80ms sandbox delivery (96% cold start reduction), 1M+ concurrent rollout environments, 600K sandboxes/min, virtualization-level isolation per session.
— @TencentAI_News March 18, 2026
“Your model improves as fast as your environments can reset” is the sentence that collapses the two categories into one. RL post-training is bottlenecked not on GPUs but on environment throughput — how many times per minute you can spin up a fresh world, let the agent act, score the result, and tear it down. A million concurrent rollout environments and 600,000 sandboxes per minute is not a coding-agent workload; it is a training workload. And it runs on the same microVM primitive E2B sells to app builders.
The independent RL-environment ecosystem is exploding in parallel. The funding and launches in the adjacent space tell the same story from the model-training side:
The next step toward automating AI is automating RL environments. Introducing General-Agent: A fully synthetic environment whose task corpus self-evolves and grows harder over time. 4,504 tool-use tasks · 1,040 domains · 8,159 unique tools.
— @PrimeIntellect May 19, 2026
And from the academic side, the same pattern of building thousands of resettable worlds:
We built 1,000 worlds for AI agents to level up in. Introducing Agent World Model — now open-source. 1,000 executable worlds, 10,000 user tasks, 35K auto-generated tools, fully resettable, 1,024-way parallel RL.
— @HuaxiuYaoML February 11, 2026
“Fully resettable” and “1,024-way parallel” are sandbox-infrastructure requirements wearing RL clothes. The practitioners building this stuff have started to formalize the anatomy of an RL environment, and when they do, the sandbox sits at the center of it:
Essentially an RL env is a set of 5 components. E = (Tasks, Harness, Verifier, State, Configuration). State: stateless / stateful, state mgmt for reproducibility, cascading side effects from stateful tools.
— @himanshustwts May 23, 2026
State management for reproducibility and handling cascading side effects from stateful tools — that is the snapshot-and-restore problem from the previous section, restated in training vocabulary. The convergence is not coming. It is here. Daytona launched an Agent Cloud aimed explicitly at RL evaluation. Tensorlake markets “10k+ concurrent RL environments.” The coding-sandbox companies and the model-training companies are going to keep colliding, because they are building the same machine.
Four sentiment clusters, and only one is bullish
Funding rounds and architecture diagrams tell you what the companies want you to believe. The unfiltered reactions tell you what the market actually thinks. Reading across the developer chatter, four distinct sentiment clusters emerge — and they are not all bullish.
Cluster one: genuine operator delight. The people actually running these sandboxes in anger are, by and large, happy — and the thing they keep mentioning is not speed, but the combination of transparency and price. A representative note from someone using Daytona for agent benchmarking:
I’ve been loving @daytonaio sandboxes. I use agents for benchmarking and experiments where agents write tons of .md, .json files and sqlite dbs. Daytona makes this seamless. Being able to browse the filesystem and get terminal access to the sandbox while my agent is working is incredible. Also shocked by the pricing. Experiments running for a couple hours cost me less than $1.
— @NathanBurg May 22, 2026
Under a dollar for hours of agent compute, with live filesystem access, is the kind of detail that does not show up in a pitch deck but drives actual adoption. The operators care about watching their agent work and not getting a surprise bill.
Cluster two: the self-host pull. The single most consequential market signal of the last month came not from a startup but from Anthropic, when it shipped self-hosted sandboxes and named the providers it integrates with:
With self-hosted sandboxes, you can run agents in any environment you control: your own infrastructure, or managed providers like Cloudflare, Daytona, Modal, or Vercel.
— @claudeai May 19, 2026
This tweet did two things at once. It validated four specific companies by name — instant credibility for Cloudflare, Daytona, Modal, and Vercel. And it validated the premise that developers want to control where their agents run, which is the entire BYOC thesis. When the largest agent-platform vendor builds an integration layer and lists you as a supported backend, that is worth more than a Series A. It also quietly reframes these companies as interchangeable backends behind someone else’s agent — a commoditization risk we will get to.
Cluster three: the build-your-own threat. The most repeated phrase across the entire corpus of reactions is some version of “so we built our own.” The enterprise-sandbox builder said it. Independent developers say it constantly:
Building my own integration layer to use Daytona. With my own tooling I can spin up to a hundred sandboxes for agents at a time. My main issue was my Mac mini crashes after a few due to ram issues.
— @Sithira269 May 27, 2026
The pattern is telling. Developers hit the limits of running sandboxes locally (the Mac mini crashes), reach for a managed provider, but frame it as building their own integration layer on top — not adopting a platform wholesale. The sandbox is treated as a swappable component, not a destination. That is healthy for the buyer and dangerous for any vendor hoping for lock-in.
Cluster four: the skeptics and the security framing. Not everyone is celebrating, and the sharpest critiques are about whether this is a real moat or a thin wrapper over Amazon’s kernel technology. The “amzn is done” tweet from the substrate section belongs here too — it is simultaneously a compliment to the startups and an argument that their advantage is borrowed. The security community, meanwhile, has started treating sandboxing as table stakes rather than a feature:
Security for agentic frameworks is hardening via Zero-Trust sandboxing using Wasm and Firecracker microVMs. Tools like E2B are setting the security floor for code execution, protecting against RCE vulnerabilities in autonomous systems.
— @agentcommunity_ May 26, 2026
“Setting the security floor” is a double-edged compliment. It means E2B defined the category’s baseline — and it means sandboxing is now an expectation, not a differentiator. When a capability becomes the floor, the companies selling it have to find a new ceiling. That tension runs underneath all four sentiment clusters: the operators love the price, the platforms are commoditizing the backend, the developers treat it as swappable, and the security framing makes it mandatory. None of those are the conditions for fat margins. They are the conditions for a feature war.
The full map: 23 companies selling a computer to your agent
Here is the complete field, drawn from the awesome-ai-sandboxes census and the per-provider research behind this piece. Open-source first, then closed, with the load-bearing facts attached.
| Provider | Isolation | Cold start | GPU | BYOC / self-host | Note |
|---|---|---|---|---|---|
| 🟢 E2B | Firecracker microVM | <200ms | No | Yes | Category reference SDK; rivals ship “E2B-compatible” APIs; 88% of F100 claimed |
| 🟢 Daytona | Bare metal | <90ms claimed | Yes (H100) | Yes | 850K runs/day; pivoted from dev-environments; AGPL-3.0 |
| 🟢 Beam | gVisor / runc | 1–3s | Yes | Yes | GPU checkpoint-restore; per-second billing |
| 🟢 OpenSandbox (Alibaba) | Docker/K8s + pluggable | n/d | n/d | Yes | Widest SDK matrix; launched Dec 2025; CNCF Landscape |
| 🟢 SmolVM (Celesto) | QEMU + Firecracker | ~500ms | Yes (QEMU) | Yes | Dual-backend; runs on a laptop; Windows-guest support |
| 🟢 Superserve | Firecracker | <200ms | No | Yes | Credentials broker; pause-to-disk; coding-agent focus |
| 🟢 Steel.dev | Docker + Chrome/CDP | <1s | No | Yes | Browser-only; anti-bot stealth; 24h sessions |
| 🟢 OpenComputer (Digger) | KVM full VM | wake in seconds | No | n/d | ”Beyond sandboxes”; hibernate/wake; git-style fork |
| 🟢 Qbox | Firecracker | n/d | n/d | Yes (by design) | Self-host-only; “E2B but in your perimeter”; alpha |
| 🟢 Leap0 | Firecracker + Jailer | ~200ms | No | Yes | Free in preview; LangChain + Google ADK plugins |
| 🟢 Tensorlake | Firecracker / Cloud Hypervisor | <300ms | n/d | Yes (mTLS in-VPC) | Live migration; 10k+ RL envs; June 1 test entrant |
| 🟢 Vercel Sandbox | Firecracker | ~125ms | No | No | GA Jan 2026; powers v0, Blackbox, Roo Code |
| 🟡 Modal | gVisor + Rust scheduler | sub-second | Yes (B200→T4) | No | $4.65B; $300M+ ARR; GPU memory snapshots |
| 🟡 Cloudflare Sandboxes | Containers + Durable Objects | boot+clone ~30s, restore 2s | No | No | GA Apr 2026; R2 snapshots; 15k concurrent |
| 🟡 Fly Sprites | Firecracker | ~300ms checkpoint | No | No | CoW checkpoints; $0.07/CPU-hr; persistent ext4 |
| 🟡 CodeSandbox | Firecracker microVM | <2s clone | No | No | Acquired by Together AI (Dec 2024) |
| 🟡 Runloop | microVM, custom bare-metal | n/d | n/d | Yes (VPC) | $7M seed; Stripe Projects; SOC2/HIPAA; SWE-bench |
| 🟡 Morph | Full VM + Infinibranch | <250ms branch | n/d | n/d | Instant full-VM branching; RL rollouts; ~90K SDK downloads/mo |
| 🟡 Blaxel | microVM (root FS in RAM) | ~25ms resume | No | No | $7.3M seed; auto-suspend to $0; Webflow, Strapi |
| 🟡 Islo | Dedicated microVM | n/d | Yes | Yes (end-customer) | By Incredibuild; LLM-as-judge egress filters; STS roles |
| 🟡 Novita | System-level (container) | <200ms | No | No | E2B-SDK-compatible; “cheaper E2B Pro alternative” |
| 🟡 Box (ascii.dev) | Dedicated Ubuntu VM | n/d | No | No | $20/mo flat; SSH + Docker-in-VM; EU regions |
| 🟡 Freestyle | KVM + nested virt full VM | <600ms | No | n/d | YC S24; live VM forking; built-in multi-tenant Git |
Twenty-three companies, one primitive, and a striking amount of convergence. Look down the isolation column and the microVM monoculture is obvious — broken mainly by Modal’s gVisor bet and the container-based platform players. Look down the cold-start column and the numbers are all within a single order of magnitude, mostly clustered under 300ms, mostly unverified. Look down the BYOC column and you find the actual segmentation: the companies that can run inside your VPC are selling to enterprises, and the ones that can’t are selling to developers. The map is not organized by speed. It is organized by who the buyer is.
Where this leaves the category
The substrate war is over and Firecracker won the open-source default, with Modal’s gVisor bet and Cloudflare’s container bet as the two well-funded dissents that keep it interesting. That part is settled. What is not settled is whether selling sandboxes is a business or a feature.
The bear case is strong and the market is already voicing it. Sandboxing is becoming the security floor, not a differentiator. The biggest agent platform, Anthropic, treats these companies as interchangeable backends behind its own integration layer. Developers reach for a managed provider and then describe themselves as “building their own integration layer,” which is the language of a swappable component, not a platform they are committing to. AWS owns the underlying kernel technology and could ship a first-party product whenever it decides the market is large enough. And the cold-start race that everyone markets on is converging toward a floor where the differences are within measurement noise. When the thing you sell is mandatory, undifferentiated at the substrate, commoditized by your largest customer, and buildable by your own users on top of free AWS technology, that is not a recipe for $4.65B outcomes across the board. Modal’s valuation is a GPU-and-data-platform valuation that happens to include sandboxes, not proof that pure-play sandboxes command that multiple.
The bull case is narrower but real, and it is the same word the enterprise builders keep circling: governance. The millisecond cold start is a developer-tools feature and it will commoditize. Credential brokering, egress control, LLM-as-judge filtering, SOC2 and HIPAA compliance, and bring-your-own-cloud execution inside a customer’s VPC are not features an LLM can vibe-code over a weekend on top of Firecracker. They are the slow, unglamorous, enterprise-sales work that builds a moat. The companies that survive the coming benchmark thinning will not be the ones with the fastest demo. They will be the ones a bank’s security team signs off on. Tensorlake, Islo, Runloop, and Daytona are building toward that. The pure speed plays are building toward a race to the bottom.
The June 1 benchmark will start adjudicating the speed claims publicly, and that is good — it will turn marketing into fact and thin the herd of undifferentiated wrappers. But the benchmark measures the wrong thing for the question that actually decides this market. The winning metric was never sandboxes-per-minute. It was whether the agent’s computer is one a regulated enterprise will let touch its data. The companies optimizing for the first number are fighting over the developer-tools scraps. The companies optimizing for the second are fighting over the budget. Watch which ones spend the next year talking about latency, and which ones spend it talking about VPCs and compliance. The second list is shorter, and it is the one that matters.