On Dec 15, 2025, the OpenAI developer account posted that gpt-4o-mini-transcribe-2025-12-15 had reached an “89% reduction in hallucinations compared to whisper-1”. The post pulled 1,052 likes and almost no follow-up coverage. A week later, on Feb 13, 2026, Deepgram shipped a Nova-3 Multilingual update that cut batch mean word error rate from 26.2% to 17.4% and labelled the rollout “no API or configuration changes required.” In April, xAI launched Grok STT at $0.10 per audio-hour and a viral tweet asked whether xAI had “just mass-murdered the entire voice AI industry.” By May, Wispr Flow was a $700M company with India as its second-biggest market — and a 99-like complaint on X asking, in public, whether Wispr was “downgrading you to a cheaper model when you use it daily.” These four moments share nothing except the fact that the speech-to-text market is now five markets, the price floor is dropping faster than the WER floor, and the benchmark leaderboards have stopped agreeing with the press releases.
The five markets, as they actually segment in mid-2026:
- Consumer dictation. Wispr Flow, Aqua Voice Avalon, native OS dictation. Sold per user per month.
- Enterprise batch transcription. AssemblyAI, Speechmatics, Rev AI, AWS Transcribe. Sold per audio-hour, with diarization, redaction, and compliance as the moat.
- Real-time voice agents. Deepgram Nova-3, AssemblyAI Universal-3 Pro Streaming, Cartesia, Soniox, ElevenLabs Scribe v2 Realtime, OpenAI Realtime. Sold per minute of session, latency is the headline.
- Regional and sovereign. Sarvam Saaras V3 in India, Speechmatics across EU regulated industries, Soniox in 60+ languages. Sold against the assumption that “Western models don’t actually work in my language.”
- Hyperscaler default. Google Speech-to-Text v2 / Chirp 3, Microsoft Azure Speech / MAI-Transcribe-1, AWS Transcribe. Sold as the option the procurement department won’t argue with.
The rest of this piece walks the contradictions inside each market, the pricing collapse that ties them together, and the architectural fork that quietly rewrote what “state of the art” even means.
The pricing race-to-the-bottom
On Apr 18, 2026, xAI’s voice API page went live with two lines that read like a counter-positioning attack. STT batch at $0.10/hour. STT streaming at $0.20/hour. Within 24 hours, the framing tweet had pulled 7,713 likes and 857 reposts.
Did xAI just mass-murder the entire voice AI industry? 🤯 Grok just launched two voice APIs. Speech-to-Text and Text-to-Speech. Built on the same stack powering Tesla cars and Starlink support. And priced at 10x cheaper than ElevenLabs. Speech-to-Text: $0.10/hr batch. $0.20/hr streaming. Text-to-Speech: $4.20 per million characters. 25+ languages. Real-time streaming. Speaker diarization. Already outperforming ElevenLabs, Deepgram, and AssemblyAI on word error rate.
— @VaibhavSisinty Apr 18, 2026
The technical spec, posted the same day, claimed 6.9% overall WER, word-level timestamps, speaker diarization, multi-channel audio, and “smart formatting” for numbers, dates, and currencies.
xAI just launched Grok Speech-to-Text and Text-to-Speech APIs. Grok Speech-to-Text • 25+ languages • Blazing accurate: 6.9% WER overall (beats ElevenLabs, Deepgram, AssemblyAI) • Real-time streaming (WebSocket) + batch (REST) • Word-level timestamps, speaker diarization, multi-channel audio • Smart formatting (numbers, dates, currencies) […] Pricing Speech-to-Text: $0.10/hr batch • $0.20/hr streaming
— @cb_doge Apr 18, 2026
The 6.9% WER claim is vendor-sourced. Artificial Analysis has not listed Grok STT on AA-WER v2 as of the May 21 snapshot, so the “beats ElevenLabs, Deepgram, AssemblyAI” line is unverified against the index that the rest of the market now treats as canonical. Pricing, however, is not unverified. It is published. And it is below every other vendor on the comparison sheet.
The lower floor came earlier. On Mar 11, 2026, Modulate launched Velma-2 at $0.03 per audio-hour with a public A/B comparison tool at speechtxt.com and the framing “Don’t trust our benchmarks. Test it yourself.”
🚨 This startup might have just killed Deepgram’s model with pricing alone. New STT model: Velma-2 by @modulate_ai $0.03 per audio hour transcribe. Compare that to: - @DeepgramAI Nova-3 - @elevenlabs Scribe v2 - @AssemblyAI Universal-2 …which can cost 10–90x more depending on use
— @n__deborah Mar 14, 2026
The 10–90× claim is wide because incumbent pricing is itself wide. The like-for-like table:
| Vendor / Model | Streaming | Batch | Notes |
|---|---|---|---|
| Modulate Velma-2 | — | $0.03/hr | Vendor; A/B tool at speechtxt.com |
| xAI Grok STT | $0.20/hr | $0.10/hr | Self-claimed 6.9% WER, 25+ languages (docs.x.ai) |
| Soniox V4 | ~$0.12/hr | ~$0.10/hr | 60+ languages |
| Cartesia Ink-Whisper | $0.13/hr | — | “Most affordable streaming STT” per Cartesia |
| AssemblyAI Universal-Streaming (Eng) | $0.15/hr | — | English-only streaming SKU |
| OpenAI gpt-4o-mini-transcribe | $0.17/hr | $0.17/hr | 89% hallucination reduction vs whisper-1 |
| Google Speech-to-Text (Dynamic Batch) | — | ~$0.18/hr | $0.024/min “without data logging” = ~$1.44/hr streaming |
| AssemblyAI Universal-3 Pro | $0.45/hr | $0.21/hr | Flagship, 6 European languages |
| ElevenLabs Scribe v2 | ~$0.22/hr | ~$0.22/hr | Per @_vojto: “now costs $0.22 per hour” |
| Speechmatics Standard | $0.24/hr | $0.24/hr | ”From $0.24/hr” |
| Deepgram Nova-3 Monolingual | $0.29/hr | $0.25/hr | $200 free credit |
| Deepgram Nova-3 Multilingual | $0.35/hr | $0.30/hr | + code-switching |
| Sarvam Saaras V3 | — | ~$0.36/hr | ₹30/hr per customer testimonial |
| OpenAI gpt-4o-transcribe | $0.36/hr | $0.36/hr | $0.006/min |
| AWS Amazon Transcribe | $1.44/hr | $1.44/hr | Drops to ~$0.47/hr at 5M+ minutes |
Note what the table does and does not say. It does not say Velma-2 wins. Artificial Analysis has not benchmarked Velma-2 either. It says that across the surface area of the market in May 2026, the price of speech-to-text spans more than a 40× range for advertised, in-production SKUs from credible vendors, before any tier discount kicks in. Three of those vendors are claiming roughly the same headline accuracy.
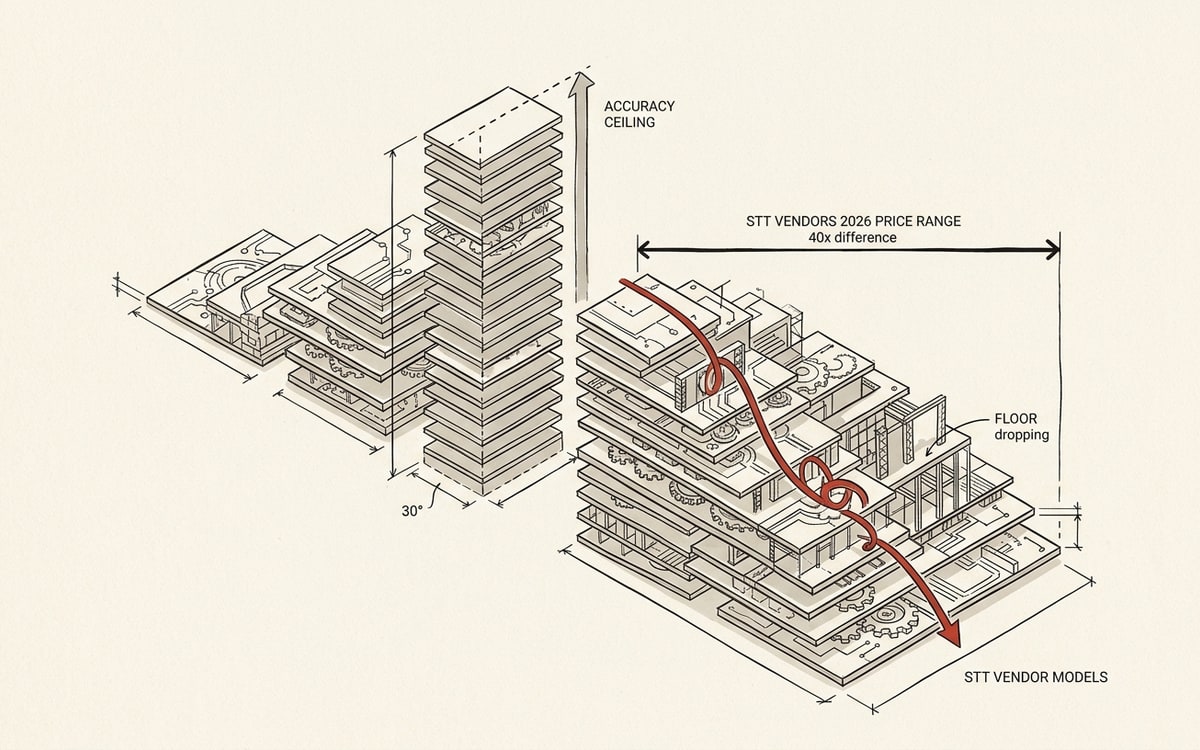
A market that prices the same nominal output at $0.03 and $1.44 is not a market in equilibrium. It is a market where the buyers do not believe the comparisons are like-for-like, and the sellers know it. That is the gap Modulate’s public A/B tool was built to expose.
Instead of asking you to trust benchmarks, we built a side-by-side comparison tool. Upload audio and compare: Velma-2 vs @DeepgramAI Nova-3, @elevenlabs’s Scribe v2 and @AssemblyAI’s Universal-2 Same audio. Same test. Try it: https://speechtxt.com/
— @modulate_ai Mar 11, 2026
The pattern is now general. Cohere’s open transcribe model launched the same way: top of the Hugging Face Open ASR English leaderboard, weights downloadable, comparison done by the community. Vendor decks are losing to public tools and to third-party leaderboards. That shift is the precondition for everything else in this piece.
Wispr Flow, and the consumer breakout that started arguing with itself
If pricing is the front of the war between sellers, Wispr Flow is the front of the war between users and the model behind the app. The product is the consumer breakout of the year. The discourse around it is louder, more contradictory, and more revealing than anything happening at the API layer.
The positive case is a thirty-year-old itch finally being scratched.
Tried my first dictation software in the 90s. Tried every generation since. They were all almost-good-enough in a way that made them worse than just typing. Wispr Flow is the first one I actually use all day. The gap between “almost works” and “works” took thirty years.
— @fernando May 19, 2026
I have been using Wispr Flow for sometime now and it works like a charm. The accuracy is just insane, so I end up saving a lot of time while speaking long texts. Also just saw @tankots (the founder) writes competitive programming in his X bio which made me even happier💪
— @Priyansh_31Dec May 8, 2026
The founder narrative is the one consumer-AI investors recognize on sight. Wispr Flow says it has 98% word accuracy, 85% of messages going out with zero edits, 54% of Fortune 500 companies using it, $10M+ revenue with a team under 50, and a 20% paid conversion rate against a 3–4% consumer-app baseline. It says the founder personally onboarded the first 500 users. And it says India became its second biggest market organically, with no marketing.
i grew up in delhi dreaming of building tech millions of people couldn’t live without. today, @wisprflow is officially live in india! before this launch, i flew to india to answer one question: does wispr flow actually work here? in the back of an auto with horns blaring. a mumbai gym with punjabi music at full volume. a dhaba with the waiter rattling off the menu faster than you can type. we went and found out - it worked every single time. india became our second biggest market on its own. we 3x’d growth in 3 months with no campaigns or partnerships.
— @tankots Apr 27, 2026
The negative case lives in the same feed and reads as a different product entirely.
Does Wispr Flow downgrade you to a cheaper model when you use it daily? The accuracy started off great, but now I have to make a lot of edits.
— @sanketnadhani Mar 8, 2026
Ninety-nine likes and 43 replies. The thread is not a one-off complaint, it is a public hypothesis: that the perceived accuracy regression is the consequence of a model switch at scale. The same hypothesis reappears two months later from a different user.
anyone else feel like wispr flow transcription accuracy got way worse all of a sudden?
— @rkapur102 May 7, 2026
And from a user who picked up an exit option.
I stopped paying $15/mo for Wispr Flow subscription Switched to a FREE local open-source model running Nvidia’s parakeet-tdt-0.6b-v3 straight from Hugging Face. Hold FN + speak → instant text. No typing. Zero lag. Accuracy is great.
— @ehwangah Feb 26, 2026
This is the structurally interesting one. The exit option is no longer “buy a competitor.” It is “download NVIDIA’s open-weight model and run it on the same laptop.” Parakeet TDT 0.6B v3 sits at 4.2% AA-WER on Artificial Analysis and 6.32% Avg WER on the Hugging Face Open ASR leaderboard, free, with a 912× real-time speed factor on Together.ai. The pricing gap between a $15/month consumer dictation app and a free local model is the entire margin of the consumer STT market, and a non-zero number of users now know it.
Wispr’s response, read across founder Tanay Kothari’s posts and the company’s product moves, is consistent. It is not engaging the regression hypothesis on engineering grounds. It is shipping product: Hinglish, Android, and India distribution. Founders as initial users. Twelve percent of coders using the product. The company’s three ideal customer profiles, in order, are developers, founders, and creators. The strategy is to widen the moat fast enough that the regression debate becomes irrelevant to growth.
That may be the right strategy. It is also the strategy that, in the AI app cohort of 2026, almost every consumer product is running. Whether it survives the open-weight model exit ramp is the open question of the consumer market. The closer the bottom of the price stack moves to zero, the louder that question becomes.
OpenAI’s quiet hallucination fix
Whisper’s signature failure mode, for two years, was hallucination during silence. The model would “hear” phantom speech, especially in healthcare and meeting transcription contexts. Reviews of Whisper documented “frequent AI hallucinations” even when accuracy was headlined at 98%. On Dec 15, 2025, OpenAI shipped a fix and almost didn’t market it.
🆕 New audio model snapshots are now live in the Realtime API with improvements to reliability, lower error rates, and fewer hallucinations: - gpt-4o-mini-transcribe-2025-12-15: 89% reduction in hallucinations compared to whisper-1 - gpt-4o-mini-tts-2025-12-15: 35% fewer word errors as measured by Common Voice - gpt-realtime-mini-2025-12-15: 22% improvement in instruction following and 13% improvement in function calling
— @OpenAIDevs Dec 15, 2025
The amplification was modest by OpenAI standards. A summary post pulled 163 likes:
New 2025-12-15 snapshots are live in the OpenAI Realtime API, targeting higher reliability, lower error rates, and fewer hallucinations: gpt-4o-mini-transcribe-2025-12-15 claims 89% fewer hallucinations vs. whisper-1, gpt-4o-mini-tts-2025-12-15 shows 35% fewer word errors (Common Voice), and gpt-realtime-mini-2025-12-15 improves instruction following (+22%) and function calling (+13%).
— @kimmonismus Dec 16, 2025
The architectural framing came from the OpenAI Audio Team blog earlier in the year: “For our speech-to-text models, we’ve integrated a reinforcement learning (RL)-heavy paradigm, pushing transcription accuracy to state-of-the-art levels. This methodology dramatically improves precision and reduces hallucination.” OpenAI is, in effect, training STT the way it trains its reasoning models, plus what it calls “midtraining with diverse audio datasets.” Whether the framing maps cleanly to the architecture or is post-hoc storytelling, the measured outcome on its own benchmarks is large. Eighty-nine percent reduction is not a marketing rounding error.
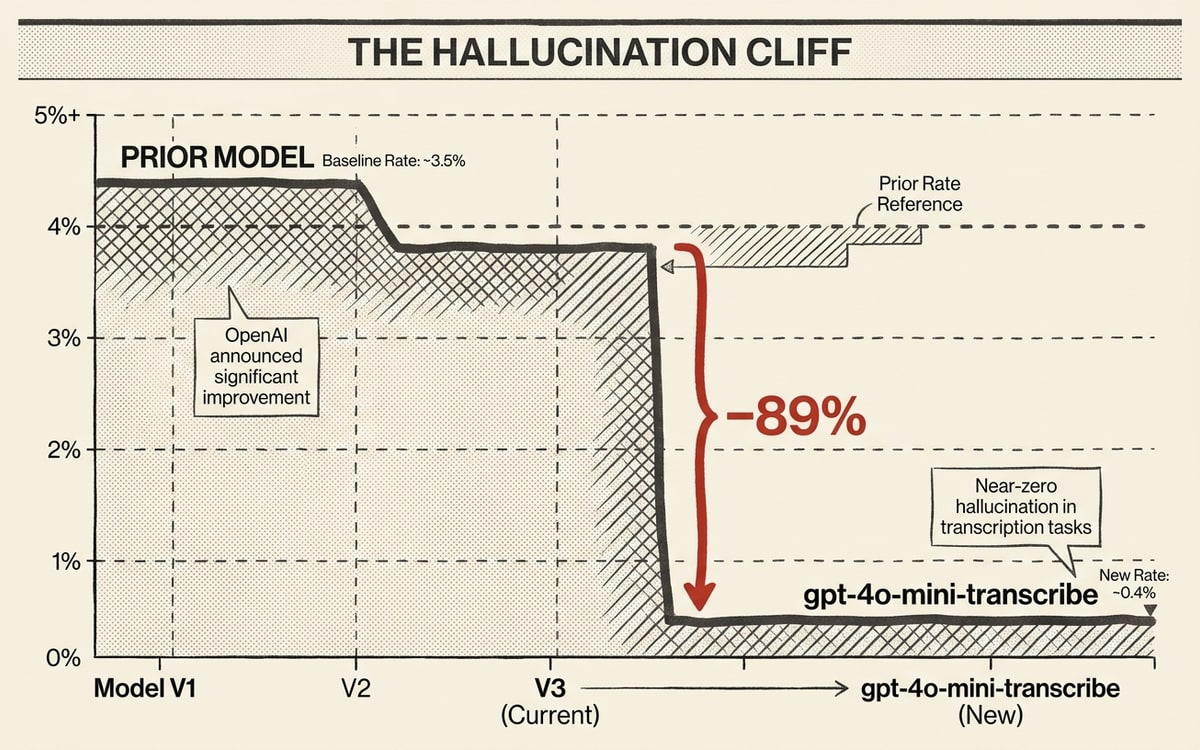
The number’s load-bearing footnote, from a builder who tested the model in an agentic loop, is worth reading as written.
the hallucination rate dropped from 92% to 61%. that’s a meaningful improvement. it’s also still 61%. any agentic workflow running on this model needs to be built around that number, not the benchmark headline.
— @MoveDecisions May 19, 2026
The two statements are not contradictory. OpenAI is measuring hallucination reduction against a specific Common Voice and benchmark setup. The builder above is measuring agent-loop hallucination rate on whatever pipeline they were running. Both can be true. The lesson is that “hallucination” is now a per-workload number, not a property of the model.
On the headline accuracy axis, AA-WER places GPT-4o Transcribe at 4.1% and GPT-4o Mini Transcribe at 4.6%, against ElevenLabs Scribe v2 at 2.2%. OpenAI is not at the top of the leaderboard. It is competitive. It is priced at $0.36/hour for the full model and $0.17/hour for mini-transcribe. And it has a hallucination story that is finally falsifiable.
For the enterprise buyer worried about agent-loop reliability rather than transcript accuracy on clean podcast audio, the Dec 15 snapshot is the most important shipping decision OpenAI made in 2025 that nobody outside the dev relations org actually amplified.
Deepgram Nova-3, and the silent multilingual upgrade
Deepgram’s 2026 has two posture changes hiding inside one model. The first is a streaming-default product that the voice-agent builders are quietly standardizing on. The second is a multilingual upgrade large enough to re-rank Deepgram on languages it previously lost.
The headline shipped on Feb 13.
Nova-3 Multilingual Speech-to-Text just got more accurate. The updated production model delivers lower Word Error Rate (WER) across batch and streaming and significant improvements in code-switching scenarios. No API or configuration changes required. 📉 Batch Mean WER: 26.2% → 17.4% | Streaming Mean WER: 23.5% → 18.6%
— @DeepgramAI Feb 13, 2026
That is a 34% relative reduction on batch and a 21% relative reduction on streaming, shipped silently into production. A third-party recap of the rollout characterized it as “~34% relative WER reduction on batch, ~21% on streaming.” No new SKU, no new pricing tier, no model rename. The customers who were already running Nova-3 woke up to a meaningfully better model on Feb 14.
Two weeks earlier, Deepgram had added Arabic with seventeen dialects.
Arabic STT is now live on Nova-3. Built for real spoken Arabic in production, Nova-3 delivers best-in-class accuracy across 17 regional variants, unlocking high-quality transcription across the Middle East and North Africa — and outperforming other STT systems on conversational speech.
— @DeepgramAI Jan 28, 2026
In May, Asia-Pacific.
Nova-3 expands speech-to-text support across Asia-Pacific. 🌏 New support now available for: 🔹 Thai 🔹 Cantonese Traditional 🔹 Mandarin Simplified 🔹 Mandarin Traditional Plus: ✔️ Accuracy improvements for Bengali, Marathi, Tamil, and Telugu ✔️ New Gujarati support
— @DeepgramAI May 14, 2026
The pattern is the implicit repositioning. Deepgram is no longer the “English-first, low-latency” default that the 2024 reviews wrote about. In 2026 it is contesting Soniox and ElevenLabs on multilingual breadth while keeping the latency and price posture that made it the streaming default in the first place. Nova-3 monolingual sits at $0.0048/min ($0.29/hr) streaming, multilingual at $0.0058/min ($0.35/hr). Voice-agent builders who run Deepgram tend to say the same two things.
the working setup right now is mic to deepgram nova-3 over wss. nothing local matches the word error rate on noisy laptops yet. parakeet and distil-whisper are getting close, not production-ready.
— @m13v_ May 14, 2026
Appreciate it, Naomi! Deepgram’s low latency is the only way this product is even possible. The Nova-3 accuracy truly makes the logic feel like a real-time conversation rather than a delay-heavy bot.
— @ethereal_soft Apr 17, 2026
Note the asymmetry. Deepgram on the AA-WER leaderboard sits at 5.3% (Nova-3), behind ElevenLabs Scribe v2’s 2.2% and AssemblyAI Universal-3 Pro’s 3.3%. It is not the best accuracy on the chart. It is the best accuracy for what the builders are actually shipping, which is real-time streaming over WebSocket on noisy laptops with sub-300ms latency budgets. The two statements live in different markets and stop arguing with each other once you separate them.
Deepgram CEO Scott Stephenson framed the broader market posture in a January funding announcement.
Voice AI startup Deepgram raised $130 million at $1.3 billion valuation 🦄 The San Francisco company hit unicorn status without looking for capital. CEO Scott Stephenson told Reuters the company wasn’t seeking a raise. Deepgram was cash-flow positive last year and didn’t need the money […] “Any place with a text field or button, products are adding voice.” More than 1,300 organizations use Deepgram’s APIs for real-time voice agents.
— @aitrendz_xyz Jan 15, 2026
The “any place with a text field or button” framing is not just rhetoric. It is the strategic precondition for the voice-agent bundling that AssemblyAI, Deepgram, ElevenLabs, and Cartesia are all running. STT alone, priced and marketed alone, is no longer how this segment of the market sells.
AssemblyAI ships self-hosted, and a $4.50/hr voice agent
AssemblyAI’s 2026 has two structural moves stacked into one quarter. On Dec 16, 2025, it launched Self-Hosted Voice AI, allowing customers to deploy Universal-Streaming on their own infrastructure.
We just launched Self-Hosted Voice AI—our Universal-Streaming model, deployed on your infrastructure, with the same performance developers already trust from our API. Self-hosting speech AI used to mean compromising on quality or paying a premium for the privilege. Not anymore.
— @AssemblyAI Dec 16, 2025
The pricing move came alongside it. AssemblyAI’s Voice Agent API bundles STT, LLM, and TTS into one WebSocket at $4.50/hour flat, priced explicitly against OpenAI Realtime’s per-token billing.
I built a voice agent yesterday using Claude Code and AssemblyAI’s new Voice Agent API. […] Universal-3 Pro Streaming has a 16.7% error rate on alphanumerics vs. 23.3% for OpenAI and 25.5% for Deepgram. In production that gap shows up in failed completions. $4.50/hr flat OpenAI Realtime API runs ~$18/hr billed per token.
— @jasonngsx May 15, 2026
The alphanumeric error rate is the load-bearing claim. For voice agents doing phone-tree work (order numbers, confirmation codes, dates, currencies), alphanumeric transcription is where accuracy gaps actually break the workflow. AssemblyAI’s vendor-cited 16.7% vs OpenAI’s 23.3% and Deepgram’s 25.5% maps directly to “how often does the agent ask the customer to repeat their order number.”
On May 4, AssemblyAI shipped a streaming diarization upgrade with metrics aimed at the same audience.
Today we’re shipping a major upgrade to streaming diarization, and it pulls us decisively ahead of the competition on the metrics that matter in production. […] 2x better cpWER on 2-speaker telephony 📊 13% better cpWER on 4-speaker meetings 🔇 42% fewer false-alarm speakers 👻 91% fewer phantom turns and words attributed to speakers who don’t exist
— @AssemblyAI May 4, 2026
Then on May 19, a latency and code-switching update.
Universal-3 Pro just got better across the board. 🚀 Five upgrades, live now: 🌎 Code-switching: ~19% relative WER improvement on multilingual benchmarks 🗣️ Disfluencies: ~5.9% WER improvement on verbatim datasets ⚡ Turnaround time: P50 latency up to 30% faster, P99 up to 34% faster
— @AssemblyAI May 19, 2026
The shipping cadence is itself the strategy. AssemblyAI is the only vendor in 2026 publishing P50 and P99 latency deltas, alphanumeric error rates, and per-scenario diarization numbers (2-speaker telephony, 4-speaker meetings) as quarterly metrics. The implicit pitch to the enterprise voice-agent buyer is “we will tell you, in writing, what you are buying.”
The headline number AssemblyAI puts at the top of the marketing is 8.14% WER for Universal-3 Pro real-time streaming. On the Hugging Face Open ASR English leaderboard, Universal-3 Pro is listed at 6.2% Avg WER (different test set). On Artificial Analysis AA-WER v2 batch, Universal-3 Pro sits at 3.3%, alongside Azure’s MAI-Transcribe-1 and Google’s Gemini 3 Pro at 2.9%. Three different numbers for the same model, on three different benchmarks, all defensible. This is the benchmark situation the rest of the piece keeps returning to.
The note buried in AssemblyAI’s pricing page is that Universal-3 Pro Streaming costs $0.45/hour. The Voice Agent API costs $4.50/hour. The 10× delta is the bundled LLM and TTS. The pitch is that the buyer no longer cares what the STT line item is, because the STT line item no longer exists as a line item.
ElevenLabs Scribe — 99 languages, 150ms, and the leaderboards that disagree
ElevenLabs is making the loudest single accuracy claim in 2026. On Nov 11, 2025, it shipped Scribe v2 Realtime.
Introducing Scribe v2 Realtime – the most accurate real-time Speech to Text model. Built for voice agents, meeting notetakers, and live applications, it transcribes in 150ms across 90+ languages, including English, French, German, Italian, Spanish, Portuguese, Hindi, and Japanese.
— @ElevenLabs Nov 11, 2025
Co-founder Mati Staniszewski framed it as a launch milestone.
To kick off ElevenLabs Summit we are releasing the best speech-to-text real-time model: Scribe v2 Realtime. - <150ms latency - incredible across all languages - 93.5% accuracy on FLEURS for top 30 languages And of course available in Agents Platform straight away too.
— @mati Nov 11, 2025
The amplification was unusual for an STT model. A 1,814-like tweet called it “every transcription tool on the market” killed. Another, with 757 likes, said “transcription just got solved.” A third, with 494 likes, said Scribe v2 “made ZERO errors on the ultimate test: identical twin voices.”
And the leaderboard agrees, on one leaderboard. On Artificial Analysis AA-WER v2, Scribe v2 is #2 overall at 2.2%, beaten only by the unreleased Fun-Realtime-ASR-preview at 1.8%, and ahead of every commercial model in the index.
On the Hugging Face Open ASR English leaderboard updated May 5, 2026, Scribe v2 sits with 5.83% Avg WER, behind every one of IBM’s granite-speech-4.1-2b (5.33%), Cohere’s cohere-transcribe-03-2026 (5.42%), IBM’s granite-speech-4.1-2b-nar (5.44%), Zoom’s scribe_v1 (5.47%), IBM’s granite-4.0-1b-speech (5.52%), NVIDIA’s canary-qwen-2.5b (5.63%), IBM’s granite-speech-3.3-8b (5.74%), and Alibaba’s Qwen3-ASR-1.7B (5.76%). NVIDIA Parakeet TDT 0.6B v3, the free-to-download model the user above switched to from Wispr Flow, sits at 6.32% Avg WER, within 0.5% of “the most accurate transcription model”.
The two leaderboards are not measuring the same thing. AA-WER v2 uses Artificial Analysis’s own held-out test set across multiple languages and contexts. The HF Open ASR leaderboard uses eight English-only test sets averaged into a single Avg WER. A model can rank #2 on one and #16 on the other and the model has not changed. What has changed is which benchmarks the buyer is allowed to see.
A real-world test from a developer comparing Whisper and Scribe v2 on customer calls, run over two weeks, makes the multilingual case for Scribe more defensibly than any leaderboard:
Spent 2 weeks evaluating transcription engines. Tested Whisper vs ElevenLabs Scribe v2 on real customer calls: Whisper: English: 96%, Persian: 71%, Arabic: 68%, Hindi: 64%. Scribe v2: English: 97%, Persian: 94%, Arabic: 92%, Hindi: 91%. One option was viable.
— @frkia Apr 8, 2026
That delta — 91% Hindi vs 64% Hindi — is not a leaderboard ranking, it is a market split. Scribe v2 is the foundation-model STT incumbent for the buyer whose audio is multilingual and conversational. For English-only enterprise batch on technical domains, the HF leaderboard says Scribe v2 is not the strongest available model and several free or near-free options outscore it. Both statements are true.
Pricing settled at $0.22 per hour by mid-May.
ElevenLabs Scribe now costs $0.22 per hour.. @OpenAI still at $0.36.
— @_vojto May 19, 2026
ElevenLabs ended 2025 at $330M+ ARR with a $11B valuation. The company is monetizing its TTS-and-voice-cloning surface and has, in effect, treated STT as a tactical loss-leader to keep the buyer inside the Agents Platform. The pricing supports that read.
The Indic split — Sarvam Saaras V3
The cleanest single demonstration of the regional-market thesis is what Sarvam shipped in early 2026.
On each of the most popular 10 languages on the IndicVoices benchmark, Saaras V3 outperforms leading models such as Deepgram Nova-3, Elevenlabs Scribe v2, Gemini 3 Pro, and GPT-4o Transcribe. The Realtime streaming model achieves much lower latency while being within a percent of […]
— @pratykumar Feb 11, 2026
That is the Sarvam co-founder claiming, on the benchmark the Indian government’s AI4Bharat group built, that the four Western incumbents lose on their own multilingual marketing claim once the test set is actually Indic. A customer note backs the latency and price part of the pitch:
Saaras V3 STT model has been flawless so far, enna fastu ya! crazy speeds! aprom cheap dhaan - 30rs per hour of audio! ippo dhaan oru 2.5 hr podcast ah 3 run-la ottinen after chunking apdi-ipdi-nu kitta thatta ~ 75rs, paravailla nu thonudhu! […] Aana sarvam ai irukkuradhu naala - selavu verum 75 dhaan
— @bwjbuild Mar 25, 2026
Thirty rupees an hour is roughly $0.36, the same as OpenAI’s gpt-4o-transcribe. Sarvam’s positioning is not “cheaper than the West.” It is “comparable price, better Indic accuracy, and built locally.”
The company is private, raised about $50M+ from Lightspeed and Khosla Ventures, and was selected by the IndiaAI Mission to receive ₹246.72 crore for indigenous AI models including Bulbul (TTS) and Saaras (STT). Co-founder Vivek Raghavan’s framing is the sovereign-AI thesis, applied to inference rather than training.
“Only thing stopping us from building a very large model is capital.” […] Vivek Raghavan says Sarvam AI has proven India can build competitive voice and vision models. And that sovereignty in AI is possible. He adds that constraint isn’t talent. It isn’t ambition. It’s funding at frontier scale.
— @prasannavishy Feb 20, 2026
The argument is structurally identical to the one Mistral made in Europe a year earlier: that the global model market is not actually a single global market, and that local-language accuracy is a defensible wedge even against a frontier lab with more capital. Saaras V3 is the first speech-to-text model to make that argument in a measurable way against the full incumbent set on its own ground.
The benchmark wars collapsed into public tools
The pattern, by mid-2026, is now repeating across vendors. Modulate launched Velma-2 with a public A/B tool. Cohere launched Transcribe-03-2026 with the weights uploaded to Hugging Face and the model self-evaluable on the Open ASR leaderboard. Artificial Analysis runs AA-WER as an index against held-out audio that vendors do not control.
CohereLabs/cohere-transcribe-03-2026 → 5.42 Avg WER → #2 on Hugging Face Open ASR (open-models category). 525 minutes of audio processed in 1 minute.
— @keita_masui Mar 29, 2026
That a 2B-parameter open model now beats Scribe v2 and Whisper-Large v3 on the eight-test-set average is not a quirk. It is the structural consequence of two things happening simultaneously: large model architectures becoming applicable to ASR, and the test sets becoming public and version-controlled. The vendor that publishes a 2.2% WER on a private test set and the vendor that publishes 5.42% on a public one are not measuring the same thing — but the buyer, in 2026, increasingly only trusts the second one.
Three concrete examples of the contradiction, all from the same May 2026 corpus:
- ElevenLabs Scribe v2: 2.2% AA-WER (#2 overall), 5.83% HF Open ASR (#16). Marketing says “most accurate transcription model.” Both numbers are real.
- Cohere Transcribe-03-2026: 5.42% HF Open ASR (#1 among open models, top tier overall), not on AA-WER. Marketing says “open” and lets the leaderboard speak.
- xAI Grok STT: 6.9% vendor-claimed WER, not on either leaderboard. Marketing says “beats ElevenLabs, Deepgram, AssemblyAI.” Pricing says $0.10/hour.
The buyer who reads only one of these data points walks away with three different rankings. The buyer who reads all three walks away with a single conclusion: vendor-blog WER claims have lost their pricing power, and the comparison has moved to whoever ships the tool first.
Local and open-weight models, now production-ready
The exit ramp that the Wispr user took to Parakeet is not an isolated case. Three independent open-weight models are now production-grade on the benchmarks that matter.
NVIDIA Parakeet TDT 0.6B v3. 4.2% AA-WER on Artificial Analysis. 6.32% Avg WER on HF Open ASR. 912× real-time speed factor on Together.ai. Free.
Cohere Transcribe-03-2026. 5.42% Avg WER, #1 open model on HF Open ASR. Beats Whisper-Large v3 (7.44%) and Scribe v2 (5.83%) on the same eight-test-set average.
Mistral Voxtral Small (24B). 2.9% AA-WER on Artificial Analysis, the best open-weights model on the AA leaderboard, ahead of every Whisper variant and most commercial APIs.
The cancellation case is now a coherent product pattern, not an isolated complaint.
I stopped paying $15/mo for Wispr Flow subscription Switched to a FREE local open-source model running Nvidia’s parakeet-tdt-0.6b-v3 straight from Hugging Face. Hold FN + speak → instant text. No typing. Zero lag. Accuracy is great.
— @ehwangah Feb 26, 2026
The counter-case is also coherent.
the working setup right now is mic to deepgram nova-3 over wss. nothing local matches the word error rate on noisy laptops yet. parakeet and distil-whisper are getting close, not production-ready.
— @m13v_ May 14, 2026
Both are right. Parakeet on a quiet laptop matches Wispr Flow’s accuracy for free. Parakeet on a noisy call-center floor with mid-sentence interruptions and code-switching loses to Nova-3. The open-weight floor is rising, the noisy-environment ceiling has not yet been hit by anything you can run locally. Voice-agent builders running production telephony stay with the cloud. Dictation power users with a quiet office leave. That bifurcation is the structural story of consumer vs production STT in 2026.
The voice-agent reframe — STT is becoming a feature
The market signal is consistent across vendors: nobody is selling STT alone anymore. Deepgram packages it into Voice Agent API at roughly $4.50/hr standard. AssemblyAI does the same at $4.50/hr flat. ElevenLabs sells the Agents Platform with Scribe v2 Realtime bundled. Cartesia sells Line. OpenAI sells Realtime. The buyer’s pricing comparison has shifted from per-minute STT to per-minute “voice agent,” and the bundled price is converging.
The framing is most explicit in Sara Guo’s October 2025 reaction to Cartesia’s Sonic-3 launch.
this is the year of real time voice! Congrats to the @Cartesia team. Their architectural creativity, obsession with performance, and taste finally makes AI conversation feel human (sub-200ms latency, multilingual consistency, and natural emotional range).
— @saranormous Oct 28, 2025
Stephenson’s “any place with a text field or button” maps to the same shift. The market is moving from “buy STT, then bolt on LLM and TTS” to “buy a voice agent.” The vendors that bundle (AssemblyAI, Deepgram, ElevenLabs, Cartesia, OpenAI) capture margin and lock in the data. The vendors that don’t (Rev AI, Speechmatics standalone, AWS Transcribe standalone) keep the workload but lose the surface area that monetizes.
That’s why Modulate’s $0.03/hour standalone STT is interesting and dangerous at the same time. It is interesting because it threatens the standalone-STT vendor’s price floor. It is dangerous to itself because the bundled voice-agent vendors are not actually selling against $0.03/hour STT. They are selling against $18/hour OpenAI Realtime. The standalone-STT market that Velma-2 is undercutting may not exist in the way the launch tweet implied by the end of 2026.
The architectural fork — foundation-model STT vs classical ASR
A clean architectural split is now visible across the AA-WER and HF Open ASR leaderboards.
Foundation-model STT. ElevenLabs Scribe v2 (2.2% AA-WER), OpenAI GPT-4o Transcribe (4.1%), Google Gemini 3 Pro (2.9%), Mistral Voxtral Small (2.9%), Alibaba Qwen3.5 Omni Plus (3.7%). Built on LLM-style architectures, optimized for context understanding, multilingual zero-shot, and instruction following. The accuracy ceiling on long-form, clean, multilingual audio sits here.
Classical ASR descendants. Deepgram Nova-3 (5.3% AA-WER, 568×–912× speed factor for related Nova variants), AssemblyAI Universal-3 Pro (3.3%), NVIDIA Parakeet TDT 0.6B v3 (4.2%, 912× real-time). Transducer or RNN-T architectures, leaner, faster, streaming-native, often with explicit speaker diarization and keyterm prompting. The latency floor on real-time streaming sits here.
A buyer-side voice from the Gemini cohort captures the shift in posture:
Building https://echoraven.ai and tried multiple transcription models this week. It is incredible how far ahead LLMs like Gemini are compared to standard AWS Transcribe and Google Speech-to-text. Settled on Gemini 2.5 flash. Never going back to non-LLM tools.
— @JatinHariani Jun 13, 2025
That sentiment generalizes for batch transcription of clean audio. It does not generalize for real-time voice agents. Gemini 2.5 Flash and GPT-4o Transcribe both have multi-second time-to-first-audio on the Realtime API workloads, which is fine for batch and unacceptable for a phone call. The classical-ASR vendors retain the streaming use case by being the only architecture that meets a 300ms latency budget today.
The fork is real and is unlikely to close in 2026. Foundation-model STT will keep climbing the accuracy ceiling. Classical-ASR descendants will keep optimizing the latency floor. The buyer’s job is to know which axis they care about before reading the leaderboard.
How to choose in 2026
The framework is the same five markets the lede opened with, with current defaults and credible challengers attached.
Consumer dictation. Default: Wispr Flow at $12–$15/month. Challenger: NVIDIA Parakeet TDT 0.6B v3 running locally, free. The Wispr regression complaints will either resolve (likely, given the company’s product velocity) or compound into the open-weight exit ramp. The next six months decide which.
Enterprise batch transcription. Default: AssemblyAI Universal-3 Pro at $0.21/hour, with the diarization and alphanumeric numbers it publishes. Challenger: Speechmatics at its $0.40/hour accuracy tier for regulated industries, ElevenLabs Scribe v2 for multilingual workloads where Scribe’s leaderboard win is real. Cohere Transcribe at HF #1 if the buyer can self-host an open-weight 2B model.
Real-time voice agents. Default: Deepgram Nova-3 streaming, the working setup the builders standardize on. Challenger: AssemblyAI Universal-3 Pro Streaming on alphanumeric accuracy, ElevenLabs Scribe v2 Realtime on multilingual latency, AssemblyAI Voice Agent API at $4.50/hour for the bundled pricing posture.
Regional and sovereign. Default in India: Sarvam Saaras V3 on Indic languages, by the IndicVoices benchmark its co-founder owns. Challenger: ElevenLabs Scribe v2 on the multilingual real-call test that hit 91% Hindi accuracy. Soniox V4 across 60+ languages for the non-Indian regional buyer.
Hyperscaler default. Default: AWS Transcribe, Google Speech-to-Text, Azure Speech, in that order of procurement-team familiarity. Challenger: nothing, because the buyer in this segment is not looking for one.
The thesis is single-sentence. Ask which of the five markets you are buying for before asking who is best. The vendor that wins one rarely wins another, the leaderboards disagree on which vendor wins which, and the price floor is dropping fast enough that the answer to “who’s cheapest” changes every quarter. The next six months will decide whether the bundled voice-agent stack ($4.50/hour, STT included) or the unbundled standalone-STT floor ($0.03–$0.10/hour, agent stack assembled on top) becomes the dominant pricing posture. Watch where the open-weight floor sits at the end of 2026. That number, more than any vendor announcement, is the one that will tell you which markets are still defensible.