When Addy Osmani’s Agent Harness Engineering essay started circulating on May 9, 2026, the headline numbers were 716 likes, 79 retweets, and 62,000 views — respectable for a director-level Google Cloud post but not viral. The number that mattered was the bookmark count: 1,499, against 716 likes. A bookmark-to-like ratio above two is the signal an audience uses when it knows it will need the document later. Readers were saving the piece because they had been collecting fragments of the same idea from different writers for nine months and finally had the synthesis in one place.
The fragments had been accumulating since at least February. A working developer’s blog used the term “harness engineering” on February 5. A LangChain engineer published the formal taxonomy of an “agent harness” on March 10. A coding-agent IDE startup wrote “It’s not a model problem. It’s a configuration problem” on March 12. Anthropic’s engineering team published a long-running-agents architecture in November 2025 and a follow-up in March 2026. Thoughtworks’ Distinguished Engineer published a user-side companion piece in April. An independent researcher in Karachi reverse-engineered Claude Code’s twenty-three components and shipped them as a teaching repository. The Director of Google Cloud AI then mapped all of it together.
By the time you read this, every major coding agent in production (open source and closed alike) ships the same primitives. Hook systems, subagent isolation, sandboxes, memory files, context-compaction passes, MCP-based tool registries, permission gates, observability layers. Some are more elaborate than others. None are missing. The discipline went from “I don’t know if there is a broad industry-accepted term for this yet” (Hashimoto’s exact phrasing on February 5) to a settled vocabulary in nine months.
This post is the synthesis. Where the term came from. The seven voices that defined it. What every shipping coding agent actually contains, with line-level citations. Where the practitioners agree, where they disagree, and which open problems are genuinely open. The thesis Viv Trivedy put cleanest:
“Agent = Model + Harness. If you’re not the model, you’re the harness.”
If you build with coding agents, configure them, evaluate them, or run them in production, you are now in the business of harness engineering whether you call it that or not.
The contested origin
The industry consensus, repeated by Addy Osmani, by HumanLayer, and even by Viv himself, is that Viv Trivedy at LangChain coined “harness engineering” in his February 17, 2026 post Improving Deep Agents with Harness Engineering. The phrase entered the canon when his March 10 follow-up, The Anatomy of an Agent Harness, reached 733,000 views and 4,800 bookmarks on X. Viv’s launch tweet was the engagement event:
A coding agent is the model + the harness around it. The harness does most of the work.
— @Vtrivedy10 Mar 10, 2026
Twelve days before Viv’s first public use of the phrase, Mitchell Hashimoto wrote it down in his personal blog.
Mitchell co-founded HashiCorp, built the open-source terminal Ghostty, and posts roughly twice a year. On February 5, 2026, in My AI Adoption Journey, he wrote:
“I don’t know if there is a broad industry-accepted term for this yet, but I’ve grown to calling this ‘harness engineering.’ It is the idea that anytime you find an agent makes a mistake, you take the time to engineer a solution such that the agent never makes that mistake again. I don’t need to invent any new terms here; if another one exists, I’ll jump on the bandwagon.”
That paragraph is the canonical definition that HumanLayer’s Skill Issue post quotes verbatim and that Addy Osmani paraphrases in the lede of Agent Harness Engineering. It is shorter than Viv’s taxonomy by an order of magnitude. It encodes the discipline as an iterative practice, not a static schema. And it predates Viv’s first published use of the exact phrase by twelve days.
Viv’s contribution, to be clear, is not in question. The taxonomy he wrote in Anatomy is the structural definition every other writer now uses. He had been writing about harnesses since September 23, 2025, and he is the one who derived the harness components by working backwards from desired agent behavior. He coined the related term Harness-as-a-Service. Viv is the taxonomist.
But Mitchell named it.
The fairer attribution: Mitchell named the discipline; Viv defined and operationalized it. Both should be cited. The pattern of secondary-source attribution, where everyone credits the formal taxonomy and silently drops the working developer who wrote the phrase first, is the kind of small history rewrite that becomes the standard story if nobody points at it. It deserves correcting before it sets.
There is a second, smaller observation worth noting. Mitchell is a HashiCorp veteran, not a LangChain employee. Birgitta Böckeler is at Thoughtworks. Dex Horthy runs HumanLayer. Fareed Khan is an independent researcher in Karachi. Addy Osmani is at Google Cloud, not Anthropic. The discipline named harness engineering did not emerge from a single AI lab or framework vendor. It emerged from working developers across companies with no coordinating editorial line, all reaching for the same idea at roughly the same time. That distributed origin is part of why the convergence is interesting. Nobody is selling it.
Agent = model + harness, in eight components
Viv’s Anatomy of an Agent Harness is the clean structural definition. We are not going to re-derive it here — go read his post if you want the full version. The compressed account:
Agent = Model + Harness. A raw model is a probability distribution over next tokens. It cannot, by itself, edit a file, run a command, observe the result, retry, or remember what it did yesterday. Wrap a runtime around it that gives it state, tools, feedback loops, and constraints, and the model becomes an agent. Everything in that wrapper is the harness.
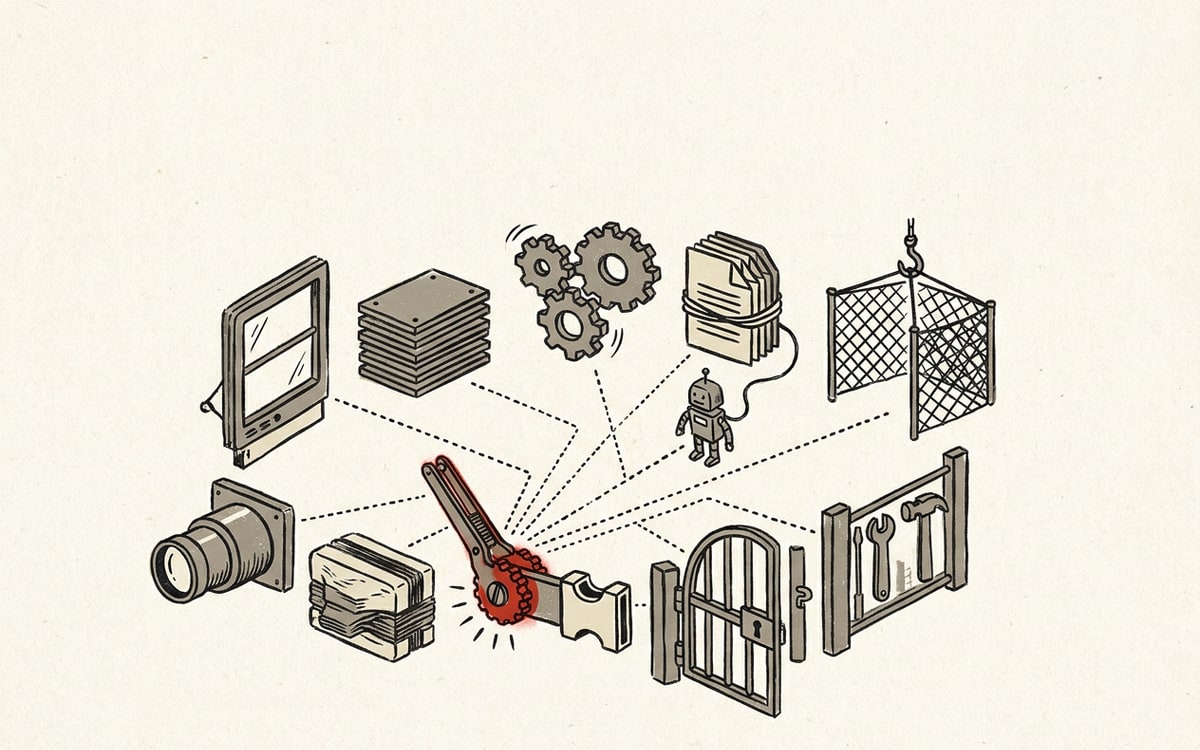
The harness contains roughly eight load-bearing components:
- A filesystem and version control. The agent’s durable workspace. Reads inputs, offloads intermediate work, coordinates between sub-tasks. Git provides free versioning and rollback.
- Bash and code execution. A general-purpose action surface. Most agents use a ReAct loop (reason, act via a tool call, observe, repeat). Bash is the universal tool because the agent can synthesize new commands at runtime instead of relying on pre-built actions.
- Sandboxes. Bash without isolation is dangerous. Sandboxes ship with pre-installed runtimes, test CLIs, and headless browsers so the agent can verify its own work without endangering the host.
- System prompts and memory files. The standing instructions. AGENTS.md, CLAUDE.md, CONVENTIONS.md,
.cursor/rules/*.mdc,.clinerules/— names differ; function does not. The pilot’s-checklist for the agent. - Tools and MCP servers. Read-write actions exposed to the model. The Model Context Protocol, introduced by Anthropic in November 2024, is now the dominant standard. TDF mapped its ecosystem here.
- Hooks and middleware. Deterministic code that runs at fixed points in the agent loop. Pre-tool-use, post-tool-use, pre-commit, on-permission-request. Hooks are how a harness encodes the rule “never run a command matching
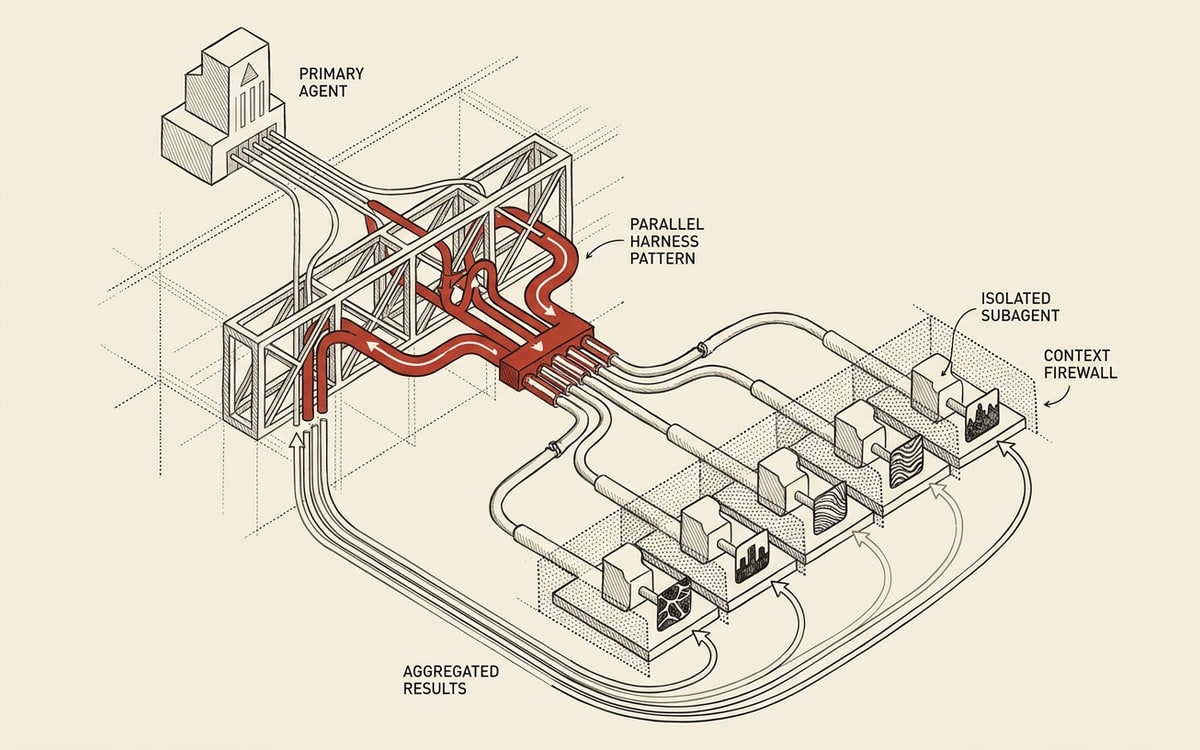
rm -rf /” without depending on the model to remember. - Subagent orchestration. The mechanism for spawning a child agent with its own context window and a narrowed task. Used as a context firewall so the parent agent’s context doesn’t fill up with the child’s exploration.
- Observability. Logs, traces, cost meters, latency meters. Without these, you cannot iterate on the harness because you cannot see what failed.
Birgitta Böckeler’s framing in Harness engineering for coding agent users adds a second axis worth keeping. Each harness component, she writes, is either a guide (anticipates behavior, steers the agent before it acts: system prompts, AGENTS.md, skills, code mods) or a sensor (observes after the agent acts and feeds the signal back: linters, type checkers, ArchUnit, LLM-as-judge). And each can be either computational (deterministic, fast, cheap, run by a CPU) or inferential (semantic, slow, expensive, run by a GPU). The four-quadrant view is operational: it tells a tech lead what to build before reaching for an LLM.
Anthropic’s two engineering posts (Effective harnesses for long-running agents in November 2025 and Harness design for long-running application development in March 2026, by Prithvi Rajasekaran) extend the structural definition with a temporal one. A harness is also the discipline of preserving coherence across many context windows. Each new session starts with no memory of the last. The harness is what makes a thirty-hour task feel like one continuous thread rather than a hundred unrelated ones.
That gets us to the seven voices.
The seven voices
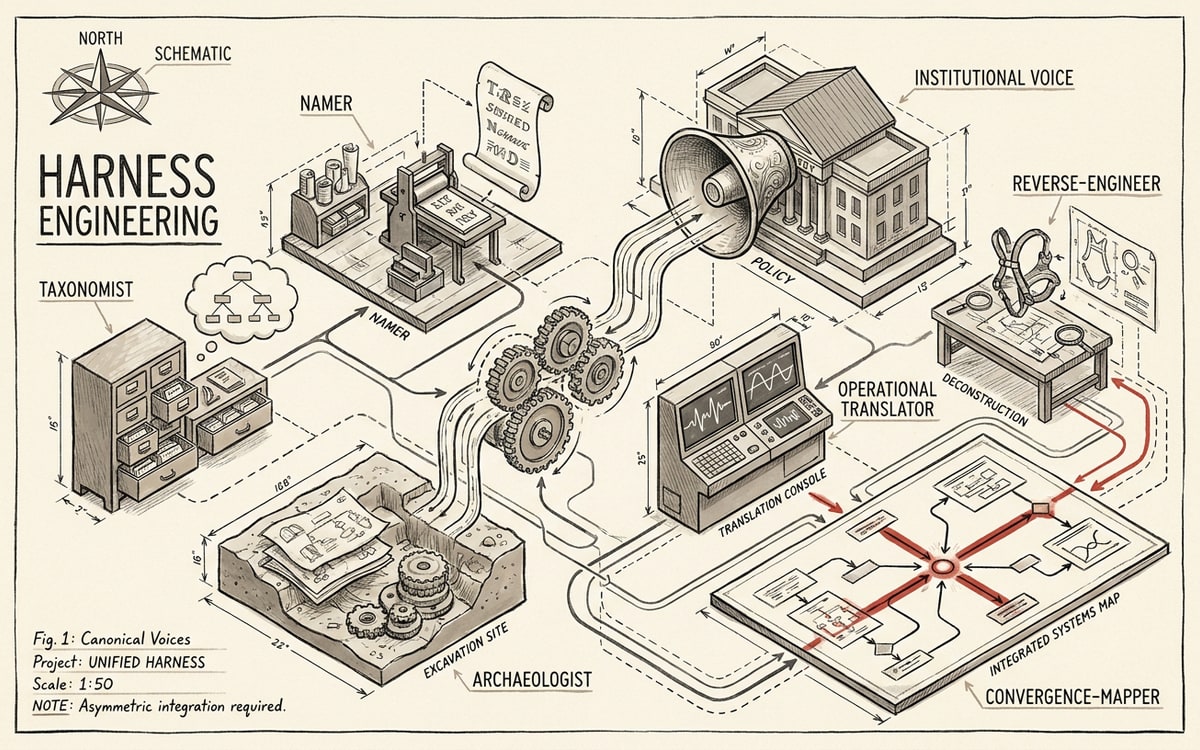
The discipline has seven canonical contributors. Each has a unique angle. Together they cover the territory.
Viv Trivedy — the taxonomist
Viv works on agents and evals at LangChain. PhD in computer science from Temple, previously at AWS, now publishing through both vtrivedy.com and the LangChain blog. He has been writing about harnesses since September 2025, when he coined Harness-as-a-Service in The Claude Code SDK and the Birth of HaaS.
His March 10, 2026 Anatomy of an Agent Harness is the reference document. The structural definition (Agent = Model + Harness), the working-backwards-from-behavior derivation, the eight components above — all his. He also wrote the empirical defense: in his February 17 Improving Deep Agents post, he showed a deepagents-cli go from rank thirty to rank five on Terminal Bench 2.0 by changing only the harness, with the model held fixed at gpt-5.2-codex. Same model. Same task. Different harness. Twenty-five-rank improvement. That is the closest thing the field has to a controlled experiment isolating harness contribution from model contribution.
His framing line, repeated everywhere: “Harnesses today are largely delivery mechanisms for good context engineering.”
Mitchell Hashimoto — the namer
Mitchell is the co-founder of HashiCorp and the author of Ghostty. He posts maybe twice a year, usually on systems engineering or his terminal work. He is not in the AI agent industry in any commercial sense. His February 5, 2026 My AI Adoption Journey is the post where the term harness engineering first appears in print:
“It is the idea that anytime you find an agent makes a mistake, you take the time to engineer a solution such that the agent never makes that mistake again.”
That sentence is the operational definition. Every other voice has built on it. HumanLayer quotes it verbatim. Addy Osmani paraphrases it in the lede of his synthesis. Anthropic’s posts assume the principle without restating it. The whole discipline rests on the iterative-ratchet idea (you don’t fight the agent’s mistakes, you encode their prevention) and Mitchell is the writer who said it first and shortest.
Dex Horthy and HumanLayer — the archaeologists
Dex Horthy runs HumanLayer. His co-host Vaibhav Gupta runs the AI That Works podcast with him; his cofounder Kyle writes most of the long-form blog posts. Together they have been publishing field reports from the inside of brownfield enterprise codebases since early 2025.
Dex’s earliest large contribution is 12-Factor Agents (April 3, 2025; 19,601 stars on GitHub at the time of writing). It is a manifesto, structured like Heroku’s 12-Factor App but for LLM-based systems. Its claim, italicized in the README:
“Most quality production ‘AI agents’ aren’t that agentic. The best ones are mostly just software.”
He coined context engineering the same month. HumanLayer’s Skill Issue: Harness Engineering for Coding Agents (March 12, 2026, by Kyle) is the operational follow-up. It is the most concrete public field report on what failures look like in production and what to do about them. Their headline reframe:
“It’s not a model problem. It’s a configuration problem.”
HumanLayer’s body of work pulls in three directions. A Brief History of Ralph (January 6, 2026) traces the Ralph Wiggum loop pattern (created by Geoff Huntley) from accident to convention. Context-Efficient Backpressure (December 9, 2025) makes the case that verbose test/build output is a tax on agents and that wrappers are a primary harness primitive. Long-Context Isn’t the Answer (March 23, 2026) reports that they tried running Opus with one-million-token context windows in production and reverted, because quality degraded faster than the marketing copy suggests.
If Viv builds the top-down taxonomy, Dex’s team writes the post-mortems after each technique stabilizes. They are the chroniclers.
Anthropic Engineering — the institutional voice
Anthropic’s engineering blog has published three load-bearing posts on harness design. The September 29, 2025 Building agents with the Claude Agent SDK reframed Claude Code as a runtime, not a product — “build it the way we built Claude Code.” The November 26, 2025 Effective harnesses for long-running agents is the canonical reference for long-running architecture. The March 24, 2026 Harness design for long-running application development extends it with a three-agent planner / generator / evaluator split, borrowed from generative adversarial networks, to address the failure mode where models grade their own work too generously.
Anthropic’s contribution is twofold. First, they are the only model lab publishing harness research at this depth. OpenAI’s analogue exists (Ryan Lopopolo’s Long-Running Coding Agents in Codex on February 11, 2026), but the cadence and detail are not comparable. Second, they ship the reference implementation. Claude Code is the agent everyone reverse-engineers, the tool-call format others copy, the hook system that Cursor now imports configs from directly. When Anthropic’s posts use a phrase, the rest of the ecosystem starts using it within weeks.
Their March 2026 line on the convergence:
“The broader developer community has converged on similar insights, with approaches like the ‘Ralph Wiggum’ method using hooks or scripts to keep agents in continuous iteration cycles.”
That single sentence is the institutional acknowledgment that the discipline exists outside their walls.
Birgitta Böckeler — the operational translator
Birgitta is a Distinguished Engineer at Thoughtworks and their Global Lead for AI-Assisted Software Delivery. She publishes through Martin Fowler’s site. Her April 2, 2026 Harness engineering for coding agent users is the user-side companion to Viv’s vendor-side taxonomy.
Her angle: most harness writing assumes you are a vendor building an agent. She writes for the engineer who is using an agent and wants to build the harness around it that her vendor’s harness does not provide. Her vocabulary (guides versus sensors, computational versus inferential, three harness categories of maintainability, architecture-fitness, and behavior) gives a tech lead a way to plan harness work the way they would plan a CI/CD pipeline. The framing line:
“A well-built outer harness serves two goals: it increases the probability that the agent gets it right in the first place, and it provides a feedback loop that self-corrects as many issues as possible before they even reach human eyes.”
She also introduces the term harnessability, defined as how easily a given codebase can be wrapped in a useful harness, and connects the discipline back to the keep quality left practice from continuous delivery. If Viv is the taxonomist and Dex is the chronicler, Birgitta is the engineering manager’s translator.
Fareed Khan — the reverse-engineer
Fareed Khan is an independent researcher in Karachi with 163 public GitHub repositories and a long catalog of LLM-engineering tutorials on Medium. On April 6, 2026 he published Building Claude Code with Harness Engineering, a 78-minute read, alongside a companion repository, FareedKhan-dev/claude-code-from-scratch. The repo breaks Claude Code into twenty-three components, each with working Python that mirrors the original’s behavior: the master agent loop, the context-injection layer, the memory store, the worktree isolator, the permission gate, the tool dispatch registry, the MCP server interface, the subagent context-firewall layer, the compaction engine, the hook lifecycle manager.
The work was prompted by an Anthropic-shipped npm package whose .map file briefly pointed at the full TypeScript source for Claude Code on a Cloudflare R2 bucket in late March 2026. Fareed worked from that map plus the public docs to reconstruct each component.
His value is empirical. Every concept in Viv’s taxonomy shows up as a named component in his Claude Code teardown, which is what Addy Osmani points at when he writes “the clearest public picture I’ve seen of a mature harness.” The taxonomy is not speculative. There is a shipped product that contains every primitive Viv enumerates, and the diagram is on GitHub.
Addy Osmani — the convergence-mapper
Addy is the Director of Google Cloud AI, working on Gemini, Vertex AI, and the Agent Development Kit. Before Google Cloud, fourteen years on Google Chrome — DevTools, Lighthouse, Core Web Vitals. The platform reach matters: 390,000 X followers, the Elevate newsletter on Substack, and a long-running technical-writing practice that gets read by the people who build the things he writes about.
His Agent Harness Engineering post (April 19, 2026) is the synthesis of the previous five voices plus Mitchell. He doesn’t add a new primitive. He establishes that the same idea is showing up across the framework world (LangChain), the practitioner world (HumanLayer and Thoughtworks), and the model labs (Anthropic), plus the Claude Code reverse-engineering community. He’s the reason the discipline now reads as one industry movement instead of seven independent blog posts.
His most-quoted line, the one that justifies most of this post’s existence:
If you look at the top coding agents today, they look more like each other than their underlying models do. The models differ, but the harness patterns are converging.
— Addy Osmani, Apr 19, 2026
That is the empirical claim we are about to substantiate.
The eight convergent themes
Across all seven writers (and across the working-developer culture they are describing) these are the load-bearing claims that recur. We treat them as the agreed-upon foundations of the discipline.
1. Agent = Model + Harness. Every voice opens with this equation. The model is one input. Everything else is the harness, and it is the harness that does most of the engineering work. Viv and Birgitta use this framing in their taxonomies; Hashimoto names it; Addy and HumanLayer adopt it directly.
2. A great harness on a decent model beats a great model on a bad harness. Viv’s controlled experiment showed deepagents-cli rising from rank thirty to rank five on Terminal Bench 2.0 by changing only the harness. The same Opus 4.6 ranks thirty-three in Claude Code and five in a tuned alternative harness. The harness gap, where it has been measured, is bigger than the model gap.
3. Failures are configuration, not models. HumanLayer’s central thesis is direct: “It’s not a model problem. It’s a configuration problem.” And a flat rejection of the “GPT-6 will fix it” reflex. Today’s models are already capable; what’s missing is the surrounding system. Hashimoto, Anthropic, Birgitta, and Addy all hold the same line.
4. The ratchet — every mistake becomes a permanent rule. Hashimoto’s original definition. When the agent slips, you don’t retry; you encode the prevention into AGENTS.md, a hook, a subagent, or a verifier so it cannot recur. Every line in a good system prompt should trace to a specific historical failure. This is the practice that distinguishes harness engineering from harness configuration.
5. Context engineering is the parent discipline; harness engineering is its delivery mechanism. Dex Horthy coined context engineering in April 2025. Viv, HumanLayer, and Birgitta all explicitly position harness engineering as a subset. The harness is how you ship context-engineering decisions.
6. Long-horizon coherence is the open frontier. Every voice converges on the same set of patterns for keeping agents focused across hours of work: Ralph loops (Geoff Huntley → Dex → Anthropic), planner/executor splits, generator/evaluator splits (Anthropic’s GAN-inspired version), structured-artifact context resets, subagent context firewalls (HumanLayer), planning files. The long-running case is where the discipline is being most actively developed.
7. The shift from LLM APIs to Harness APIs. Viv coined Harness-as-a-Service in September 2025; Anthropic operationalized it with the Claude Agent SDK in September 2025; Addy generalized it to industry-wide trend in April 2026. Builders no longer write the loop, the tools, the compaction, the hooks from scratch. They configure a runtime. We expand on this in §9.
8. Models and harnesses co-evolve. Today’s models are post-trained inside specific harnesses. Codex’s apply_patch is the canonical example: GPT-5.2-codex is exceptionally good at it because the post-training loop included it. The implication is path-dependence: the best harness for your tasks is not necessarily the one your model was trained in. This is the most contrarian of the eight, but it shows up across Viv, HumanLayer, and Anthropic.
These eight are the foundation. The next section is the longest and least copyable in this post: what every shipping coding agent actually contains, by component.
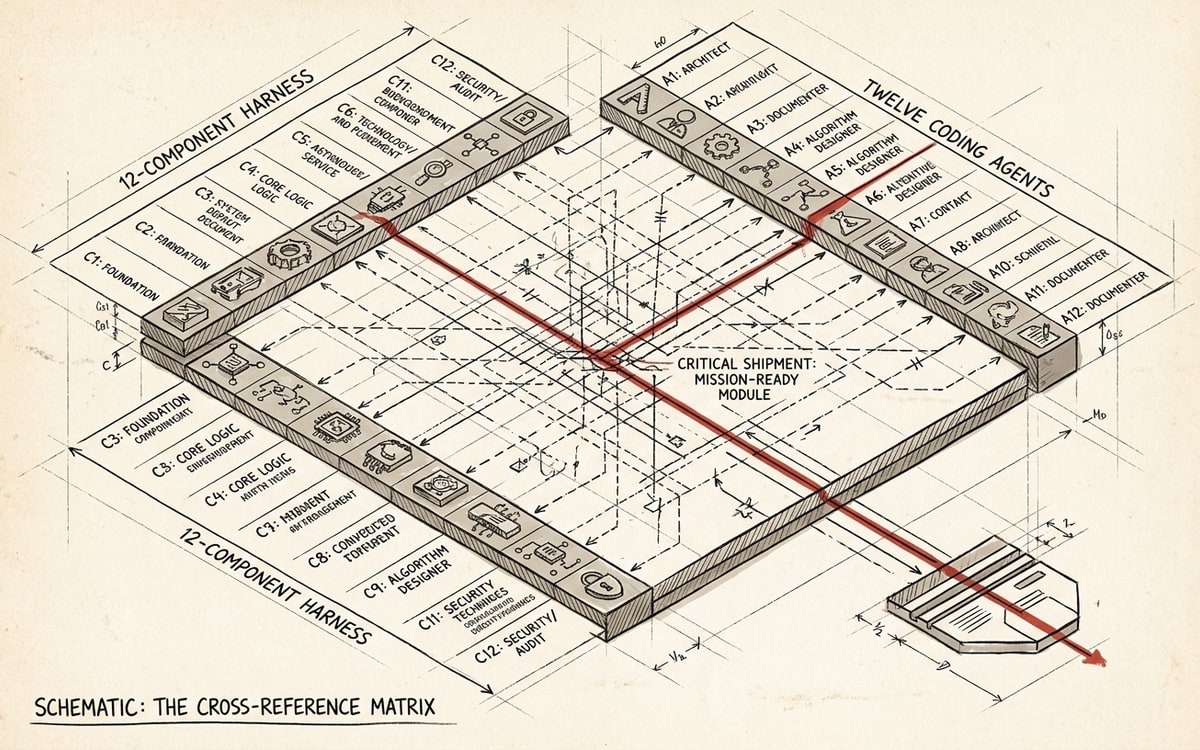
The twelve-component harness, by what each agent ships
Twelve coding agents have public-enough internals to compare meaningfully. The open-source set has eight: the IDE-grade tools (Aider at 44.6k★, Cline at 61.5k★, Continue.dev at 33.1k★) plus the runtimes (OpenCode at 157.6k★, Codex CLI at 81.4k★, goose at 44.9k★, smolagents at 27.2k★, and the framework family of Flue, just-bash, Mastra, Inngest agent-kit). The closed-but-documented set has four: Claude Code and Cursor on the editor side; Devin and Replit on the cloud-agent side. Plus Warp’s Oz as a terminal-native sixth case. Star counts and version numbers are as of May 2026, verified against each project’s repository.
For each agent the relevant claim links to a primary source — a GitHub line, an official documentation page, or a company blog post. We are not paraphrasing. The cells you can verify are the ones you should care about.
Filesystem and version control
Universal. Every agent on the list reads and writes the host filesystem; every IDE-based agent auto-commits or recommends --auto-commits for rollback. Aider commits after every successful edit by default (base_coder.py, auto_commits = True). Cline, Continue, Cursor, and Claude Code follow the same pattern with their own settings keys. Devin’s per-task VM contains its own git repository per Devin can now Manage Devins. Replit’s Repls are themselves Linux VMs with persistent storage; the Repl is the agent workspace. The pattern is invariant.
Bash and code execution
Universal except for two outliers. Aider does not run a tool-calling loop at all — it parses a SEARCH/REPLACE diff dialect from the model’s output and applies it. The shell only runs when the user invokes /run or when lint and test gates fire. Smolagents inverts the model: instead of JSON tool calls, the agent emits Python code that calls tools as functions, which smolagents parses through its own AST executor before running. Both are deliberate departures. Aider’s bet is that diff dialect choice matters more than tool count; Hugging Face’s bet is that code-as-actions reaches the same accuracy in fewer steps. Every other agent on the list uses standard JSON tool calls with a Bash tool as the action surface. The open-source side covers Cline, Continue, plus Codex CLI, OpenCode, and goose. The closed side covers Claude Code and Cursor (in the editor) plus Devin, Replit, and Warp (in the cloud).
Sandboxes
This is where the divergence is most concrete. Codex CLI is the only major coding agent shipping kernel-level sandboxing as a first-class part of every shell call. The codex-rs/sandboxing/ crate contains macOS Seatbelt SBPL policies (seatbelt_base_policy.sbpl, seatbelt_network_policy.sbpl), Linux Landlock and bwrap (bubblewrap) integrations, and Windows AppContainer support. Network egress requires explicit policy. The default sandbox is read-only.
The closed-source equivalents go even further. Devin runs each task in its own virtual machine. Cognition’s Manage Devins describes it: “Each managed Devin is a full Devin, running in its own isolated virtual machine with its own terminal, browser, and development environment.” Cursor’s Background Agents run in remote isolated VMs. Replit Agent inherits Replit’s existing container model: the Repl is already a Nix-based Linux VM. Smolagents sandboxes the interpreter itself: a custom AST executor with a whitelisted builtin set, plus optional remote backends (remote_executors.py) covering E2B, Docker, Modal, plus Blaxel and Wasm.
Aider and Cline run in the user’s host shell. So do Continue and goose; Claude Code’s default installation does as well. Safety comes from permission gates, not isolation. Flue and just-bash propose a third option: a simulated bash interpreter on a virtual filesystem (vercel-labs/just-bash implements bash-like execution in TypeScript with an in-memory filesystem). Their bet is that real-feeling bash without container overhead is the right tradeoff for cheap, fast agents.
The sandboxing field is genuinely unsettled. The open-source consensus has moved from “none, run in user’s shell” in 2024 to “OS-level isolation for the unsafe parts” in 2026. Codex CLI is the leading edge.
System prompts and memory files
Convergent in pattern, divergent in name. The dominant convention is AGENTS.md — codified at agents.md and adopted by Codex CLI, OpenCode, Cursor (alongside .cursor/rules/*.mdc), and Claude Code (alongside CLAUDE.md). Codex CLI’s AgentsMdManager walks from project root down to the current working directory, concatenates every AGENTS.md it finds, and supports a global override at ~/.codex/AGENTS.md and a local override at AGENTS.override.md. Cline’s .clinerules/ directory loads instructions at session start. Continue’s .continuerules/ does the same. Aider supports --read CONVENTIONS.md and per-project .aider.conf.yml. Cursor supports .cursorrules (legacy) and .cursor/rules/*.mdc (current).
The interesting sub-pattern is per-model-family system prompt variants. Cline ships hand-tuned prompts in nine subdirectories under src/core/prompts/system-prompt/variants/, one each for gpt-5, gemini-3, glm, plus hermes, devstral, trinity, plus xs, next-gen, and generic. OpenCode does the same with .txt files in packages/opencode/src/session/prompt/, one per family: anthropic.txt, gpt.txt, codex.txt, plus gemini.txt, kimi.txt, beast.txt, plus trinity.txt. The session/system.ts provider() function selects the variant by substring matching on model ID. This is how Viv’s “models are non-fungible” claim concretely shows up in production code.
Skills are the third layer. Claude Code’s .claude/skills/<name>/SKILL.md with YAML frontmatter is the reference; Cursor’s .cursor/skills/, Continue’s readSkill tool, and Cline’s use_skill are the imitations.
Tools and MCP
Universal. Every agent on the list ships a tool registry. The set converges. Read, Write, Edit, Bash, Grep, Glob, WebFetch, WebSearch appear under those exact names or trivial variants in Claude Code, Codex CLI, OpenCode, and Continue. Cline’s src/core/prompts/system-prompt/tools/ lists the same set plus its own additions: read_file, write_to_file, replace_in_file, apply_patch, list_files, list_code_definition_names, search_files, execute_command, browser_action, web_fetch, web_search.
MCP support is now universal across the list except in smolagents (which has mcp_client.py but treats MCP as one of many tool sources rather than the primary). The IDE-grade tools (Claude Code, Cursor) speak MCP natively, as do the runtimes (Codex CLI, OpenCode, Cline, Continue) and the cloud-edged agents (goose, Warp Oz). The general-purpose frameworks Mastra and Inngest agent-kit complete the set. The TDF MCP ecosystem map covers the 20,000-server long-tail; the relevant claim here is that MCP is now the default tool-discovery layer for harnesses, full stop.
Hook systems
Two years ago, exactly one coding agent had a public hook system. Today the practice is near-universal among the production-grade tools, and the events are visibly converging across implementations.
Claude Code has the most extensive hook system. The hooks reference documents twenty-four events: SessionStart, Setup, UserPromptSubmit, UserPromptExpansion, PreToolUse, PermissionRequest, PermissionDenied, PostToolUse, PostToolUseFailure, PostToolBatch, Notification, SubagentStart, SubagentStop, TaskCreated, TaskCompleted, Stop, StopFailure, TeammateIdle, InstructionsLoaded, ConfigChange, CwdChanged, FileChanged, WorktreeCreate, WorktreeRemove, PreCompact, PostCompact, Elicitation, ElicitationResult, SessionEnd. Three handler types are supported (shell command, HTTP endpoint, LLM prompt) and matchers can be literal tool names, |-separated lists, or regex. The HTTP and LLM-prompt handlers are unique to Claude Code on this list.
Cursor’s hook system has nineteen events per cursor.com/docs/hooks: preToolUse, postToolUse, postToolUseFailure, subagentStart, subagentStop, beforeShellExecution, beforeMCPExecution, afterShellExecution, afterMCPExecution, afterFileEdit, beforeReadFile, beforeTabFileRead, afterTabFileEdit, beforeSubmitPrompt, afterAgentResponse, afterAgentThought, stop, sessionStart, sessionEnd, preCompact. Both command-based and prompt-based handler types. The notable detail: Cursor explicitly ships Claude Code hook compatibility — “Cursor can load and execute hooks configured for Claude Code.” This is the only example in the ecosystem of a closed-source vendor treating a competitor’s configuration format as an open standard. It is also the cleanest evidence that hooks have crossed the line from feature into infrastructure. (Cursor’s hook surface is now scriptable from TypeScript too — see what you can actually build with the Cursor SDK.)
Cline shipped the third major implementation. The src/core/hooks/ directory and templates.ts:14-23 list nine events: TaskStart, TaskResume, TaskCancel, TaskComplete, PreToolUse, PostToolUse, UserPromptSubmit, Notification, PreCompact. Hooks are external scripts (Bash on Unix, PowerShell on Windows) invoked over JSON stdio. PreToolUse hooks can cancel a tool call by raising PreToolUseHookCancellationError.
Codex CLI has eight events per codex-rs/hooks/src/lib.rs:82-86: PreToolUse, PostToolUse, PermissionRequest, SessionStart, PreCompact, PostCompact, UserPromptSubmit, Stop. Three handler types: Prompt {}, Command { command, timeout_sec, async, status_message }, Agent {}. Per-event matchers supported.
The remaining open-source agents have either narrower or nonexistent hook systems. Aider wires lint and test gates directly into the loop without exposing a general hook framework. Continue validates tool-call policies in each tool definition plus a @continuedev/terminal-security package. goose has no standalone hook framework but runs every tool call through a pipeline of inspectors (tool_inspection.rs) — a SecurityInspector, an AdversaryInspector, an EgressInspector, and a permission_judge.rs that uses a smaller LLM to classify whether the call needs approval. Smolagents has logging callbacks via monitoring.py but no policy hooks.
Three observations from the convergence. First, the events that show up everywhere are PreToolUse, PostToolUse, SessionStart, Stop, and PreCompact — that is the floor. Second, hook handlers have settled on a JSON-over-stdio interface; it works because it is the same protocol Language Server Protocol uses, so editor and CLI tools can share infrastructure. Third, hooks are the mechanism by which Mitchell’s ratchet gets operationalized: a failed test becomes a PostToolUse hook that grep’s for .skip(, becomes a permanent gate, becomes the rule the agent never has to remember because the harness enforces it.
Subagent orchestration
Spreading fast and deeply contested. Every production-grade agent on the list now has some form of subagent spawning. The architectural choices vary substantially.
Claude Code’s approach is the most elaborate. Built-in subagents include Plan (research, read-only), general-purpose (full tools), and specialized helpers. Custom subagents live in .claude/agents/<name>.md with YAML frontmatter specifying model, allowed tools, and a description. Subagents cannot spawn subagents (an explicit anti-recursion guard). Worktree isolation lets each subagent run in its own git worktree. The experimental Agent Teams mode (CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1) introduces persistent teammates with TeamCreate, SendMessage, TeammateIdle, each teammate getting its own session.
Cline’s use_subagents tool spawns up to five parallel in-process subagents per call, each with its own prompt, returning research results with token and tool statistics. Gated by subagentsEnabled and !isSubagentRun to prevent recursive spawning. Cline also supports new_task for a context handoff: the agent writes a structured summary and a fresh task starts with that as preloaded context.
Codex CLI’s tools/handlers/multi_agents.rs is direct about its inheritance model: “Sub-agents start from the turn’s effective config, inherit runtime-only state such as provider, approval policy, sandbox, and cwd, and then optionally layer role-specific config on top.” The crate uses exceeds_thread_spawn_depth_limit to prevent unbounded nesting. A newer multi_agents_v2.rs is in active development.
OpenCode’s native task tool derives subagent permissions from the parent’s. goose’s subagent_handler.rs plus subagent_execution_tool/ supports recipes — declarative agent specs in recipe/ that can be invoked as subagent jobs with positional parameters. Subagents cannot spawn additional subagents.
Cursor’s subagents documentation describes the same pattern: “Each subagent operates in its own context window, handles specific types of work, and returns its result to the parent agent.” Available in editor, CLI, and Cloud Agents.
The contested case is Devin. Cognition published Don’t Build Multi-Agents in June 2025 with two principles: “Share context, and share full agent traces, not just individual messages” and “Actions carry implicit decisions, and conflicting decisions carry bad results.” The argument was that single linear threads with full trace sharing beat multi-agent systems on reliability. They held that line for nine months. Then in March 2026 they shipped Devin can now Manage Devins: a parent Devin breaks tasks down and delegates to managed Devins, each in its own VM. Then in April they published Multi-Agents: What’s Actually Working: they now deploy multi-agent patterns where context can be cleanly partitioned. The reversal happened in ten months. We come back to this in §7.
Permission gates
Universally present, structurally divergent. Codex CLI combines OS sandboxing with approval policies (untrusted / on-failure / on-request / never) per codex-rs/core/src/safety.rs. goose runs an LLM-as-permission-judge (permission_judge.md) plus deterministic pattern checks (security/patterns.rs). Cline uses glob-pattern allow/deny via the CLINE_COMMAND_PERMISSIONS environment variable, parsing chained shell commands segment-by-segment so rm -rf / && echo done is evaluated as two separate calls. Claude Code has declarative rules with a PermissionDenied hook that can ask the model to retry. OpenCode uses Effect-typed Ruleset per Agent definition; subagents derive narrowed permissions from the parent. Aider does single-Y/N confirms on shell commands. Continue’s evaluateFileAccessPolicy returns allowedWithPermission for files outside the workspace and allowedWithoutPermission for files inside.
The interesting case is goose’s LLM judge. Most permission systems are deny-list based — you list the things the agent cannot do. Goose’s judge classifies every tool call into approval categories using inference. It is the only major coding agent that uses an LLM for safety classification. Whether that is a good idea depends on whether you trust the judge model, which depends on the same harness-engineering practice you’re using to wrap the primary agent. Recursion all the way down.
Context management
Universal, with three patterns at three levels of sophistication.
Compaction. Every long-running agent on the list ships some form of compaction. Codex CLI’s tasks/compact.rs uses a templates/compact/prompt.md that opens with “You are performing a CONTEXT CHECKPOINT COMPACTION. Create a handoff summary for another LLM that will resume the task.” Cline’s ContextManager.ts maintains nested Map<outerIndex, [EditType, Map<innerIndex, ContextUpdate[]>]> for binary-search-friendly truncation; /compact, /smol, and /newtask slash commands trigger summarization. Aider’s base_coder.py:1002 launches a background summarizer_thread that calls ChatSummary.summarize_all() when history exceeds max_chat_history_tokens. Claude Code emits PreCompact and PostCompact hooks at compaction boundaries.
Persistence and resume. Codex CLI’s rollouts (rollout/ and rollout-trace) plus its memories crate (codex-rs/memories/) enable --resume and --continue. Claude Code’s CLI has the same flags; sessions persist on disk and can be resumed or forked. Aider auto-commits every edit, so resuming is a git checkout.
Output truncation. Codex CLI’s codex-utils-output-truncation crate enforces per-tool TruncationPolicy. goose’s large_response_handler.rs does the same. The shared insight, articulated by HumanLayer in Context-Efficient Backpressure (December 2025): a 2,000-line build log is a tax on every subsequent agent turn. The harness should pre-truncate it to the relevant lines before the model sees it.
The most interesting context-management primitive on this list belongs to Cognition. SWE-grep (October 2025) is a small specialized model Cognition trained for fast multi-turn context retrieval inside Devin. It is the same idea as Anthropic’s compaction prompt (“hand off cleanly to the next session”), but Cognition went all the way down to model training. The harness ate the model.
Editor formats
Where Aider stands alone. Most agents on this list emit a single edit format — apply_patch, replace_in_file, JSON tool calls of various names. Aider supports seven distinct edit formats, selected per model based on what each model edits most reliably. The base base_prompts.py defines reusable text blocks; each coder class subclasses CoderPrompts and supplies a main_system string: EditBlockPrompts (SEARCH/REPLACE), ArchitectPrompts, AskPrompts, HelpPrompts, ContextPrompts, PatchPrompts, plus per-edit-format variants (whole-file, fenced, function, diff-fenced). Paul Gauthier’s bet is that diff-dialect choice matters more than tool count; the model’s failure mode is bad-diff parsing more often than bad-decision making.
The closest analogue is smolagents’ code-as-actions — the agent emits Python code that calls tools as functions, smolagents validates the AST, executes selected nodes, and returns observations as printed output. Hugging Face’s original blog cites work showing code-action agents reach the same accuracy in fewer steps.
Both are deliberate departures from the “JSON tool call” consensus. Aider is the harness that bets on diff dialect; smolagents is the harness that bets on code expressivity. Neither needs the other — they are answering the same question with different theories of the model.
Observability
Convergent in pattern, divergent in surface. goose has a built-in tracing stack and surfaces a ”🔒 Security Alert” approval dialog with a finding_id that lets users audit specific events. Cline persists task histories on disk. Claude Code integrates with Anthropic’s tracing via the SDK. Continue’s Hub provides shared assistant configurations with telemetry. Inngest agent-kit treats agent loops as Inngest workflows with built-in tracing — each LLM call is a step that can be retried, replayed, or resumed across deploys.
The pattern is the same: per-step traces, per-tool logs, per-session histories, cost meters where the harness has access to billing data. The variance is mostly UX. The interesting question is whether observability becomes the primary harness surface in 2027 — whether the next layer of the discipline is built by reading agent traces and feeding them back into the harness automatically. We come back to this in §10.
A note on the matrix
The full grid of twelve components by twelve agents would be twelve cells per agent, which would take more space than we have without adding evidence. The component-by-component view above contains every cross-reference that matters. Two patterns in particular are worth pulling out before we move on:
Hooks have crossed the line from feature to infrastructure. Two years ago, exactly one coding agent had a public hook system. Today five do, plus three with narrower variants, plus one closed-source vendor importing another’s hook configs as-is. The five core events (PreToolUse, PostToolUse, SessionStart, Stop, PreCompact) are universal. This is a settled standard, not an emerging one.
OS-level sandboxing has not crossed that line yet. Codex CLI is the leading edge in open source; Devin’s per-task VM and Cursor’s Background Agent VMs are the closed-source leading edge; everyone else relies on permission gates plus the user’s existing host shell. The trend is clearly toward more isolation, but the open-source default is still “run in the user’s shell.”
The 2026 question is whether the rest of the agents catch Codex CLI by 2027, or whether OS sandboxing remains the difference between toy on my laptop and production on someone else’s machine.
The Ratchet, in production
Mitchell’s coining definition is the operational core of the discipline. Restated: when the agent slips, you encode the prevention into the harness so that specific failure cannot recur. Every line in a good system prompt traces to a specific historical mistake.
The practice shows up in three places in the public record.
The first is in actual AGENTS.md files. The cross-tool agents.md convention has been adopted by Codex CLI, OpenCode, Cursor (alongside .cursor/rules/*.mdc), Claude Code (alongside CLAUDE.md), and a long tail of smaller projects. If you grep public GitHub for files named AGENTS.md in repositories with at least a hundred stars, you find a recurring pattern: a list of constraints, each phrased as a negative (“Never X” or “Do not Y”) that maps to a behavior the maintainers had to debug out of an agent. Outcome School’s blog has an entry on AGENTS.md patterns. The Astro team’s flue README calls it “a pilot’s checklist, not a style guide.”
The second is in HumanLayer’s Skill Issue post. They walk through a brownfield enterprise codebase scenario where the agent kept committing partial test updates. The fix wasn’t a better model. It was three configuration changes: (1) an AGENTS.md rule banning .skip( in any committed test, (2) a PostToolUse hook that grep’s the diff for .skip( and rejects the tool call if found, and (3) a reviewer subagent invoked before any commit to verify the test count went up, not down. Three layers of harness wrapped around a single observed failure mode. The agent never had to learn the rule because the harness enforces it.
The third is in Anthropic’s Effective harnesses for long-running agents. They describe a two-fold pattern: an initializer agent that scaffolds the environment on first run with an init.sh, a claude-progress.txt log, and an initial git commit; and a coding agent that makes incremental progress every session and leaves clean, mergeable artifacts behind. The initializer is a harness response to a specific failure: agents starting fresh with no idea what was done before. Each new session, the harness rebuilds the context the model could not preserve.
The Ratchet is not abstract. It is, concretely, Pull Request #15476 to your AGENTS.md. Or the new PostToolUse hook in ~/.claude/settings.json. Or the additional reviewer subagent in .claude/agents/reviewer.md. The mistake creates the rule. The rule prevents the next mistake. The AGENTS.md of a serious harness is, after enough iterations, a precise log of every observed failure mode in that codebase.
This is the line that distinguishes harness engineering from harness configuration. Configuration is what you do once. Engineering is what you do every time the agent shows you a new way to fail.
The contrarian read: subagent fan-out is a harness response, not a model capability
Most of this post is a synthesis. This section is an argument.
Subagent orchestration spread across every coding agent on the list above in roughly twenty months. Every voice in §4 mentions it as a primary harness primitive. The Cline team built use_subagents with five-parallel spawning. Claude Code built Agent Teams. Codex CLI added multi_agents_v2. goose built recipes-as-subagents. OpenCode added a native task tool. Cursor added subagents to the editor, CLI, and Cloud Agents.
The default narrative for this convergence is that models got better at coordination. Claude 4.5 and GPT-5.2 can plan, dispatch, and integrate results from sub-tasks more reliably than their predecessors, so the framework caught up. Subagents are the natural shape of better models.
The harness-engineering read is different. Subagents are a response to context-window economics, not to model capability. Three pieces of evidence.
First, the timing. Subagent patterns spread fastest after the leading models all gained million-token context windows in early 2025. Naively, longer context should have made subagents less necessary because you can fit more of the task into one window. The opposite happened. HumanLayer’s Long-Context Isn’t the Answer (March 23, 2026) reports the operational reason: they ran Opus with one-million-token windows in production and reverted because quality degraded faster than the marketing copy suggested. Context windows expanded, but the cost per useful token rose faster. Subagents emerged as a way to firewall the parent’s context against intermediate noise, keeping the high-quality, high-cost context window small.
Second, the framing across writers. Kyle at HumanLayer puts it in Skill Issue:
“Sub-agents function as a ‘context firewall’ that ensures discrete tasks can run in isolated context windows so none of the intermediate noise accumulates in your parent thread.”
Not “subagents enable parallel reasoning.” Not “subagents unlock specialization.” The framing is firewall — keep the parent’s context clean. That is harness language, not model-capability language.
Third, Cognition’s reversal. We covered the timeline above; the architectural details matter for the argument. The June 2025 Don’t Build Multi-Agents post by Walden Yan opens with two principles: “1. Share context, and share full agent traces, not just individual messages. 2. Actions carry implicit decisions, and conflicting decisions carry bad results.” The argument is that splitting work across multiple agents fails because the partial views each agent has of the task lead to conflicting decisions. The recommended pattern is a single linear thread plus aggressive context compression.
Then March 2026 happens. Devin can now Manage Devins describes a parent Devin that decomposes a task and dispatches managed Devins in their own VMs. Then April 2026: Multi-Agents: What’s Actually Working. Cognition still recommends single-thread for most tasks, but they now deploy multi-agent patterns where “context can be cleanly partitioned.” The reversal happened over ten months. The Sonnet model improved across that period, but that is the wrong axis to look at — the architectural insight that flipped was about context partition, which is a harness property.
The honest counter, which we should acknowledge: Anthropic’s Building Effective Agents (December 2024) defends multi-agent orchestration as a legitimate primary pattern, not a workaround. Their three-agent planner/generator/evaluator architecture in Harness design for long-running application development (March 2026) is structured around the model-correctness benefit of separating generation from evaluation, not around context economics. Both can be true: multi-agent helps with context partition and with avoiding the bias of self-grading.
The point is not that subagents are bad. They are clearly useful, increasingly standard, and worth building well. The point is that the framing matters: subagents are a harness-level architectural choice that responds to harness-level constraints (context cost, context coherence, evaluator bias). They are not a side-effect of model improvement. If your team is debating whether to add subagents, the question to ask first is “what part of our context is poisoning the parent thread?” — not “are our models smart enough yet?”
That framing changes who owns the problem. If subagent design is a harness problem, it lives with the harness engineers. If it is a model problem, it lives with the model providers. Where ownership sits determines whether the next generation of agents gets more context-isolation discipline or whether everyone waits for Claude 5 and GPT-6.
Inside HumanLayer
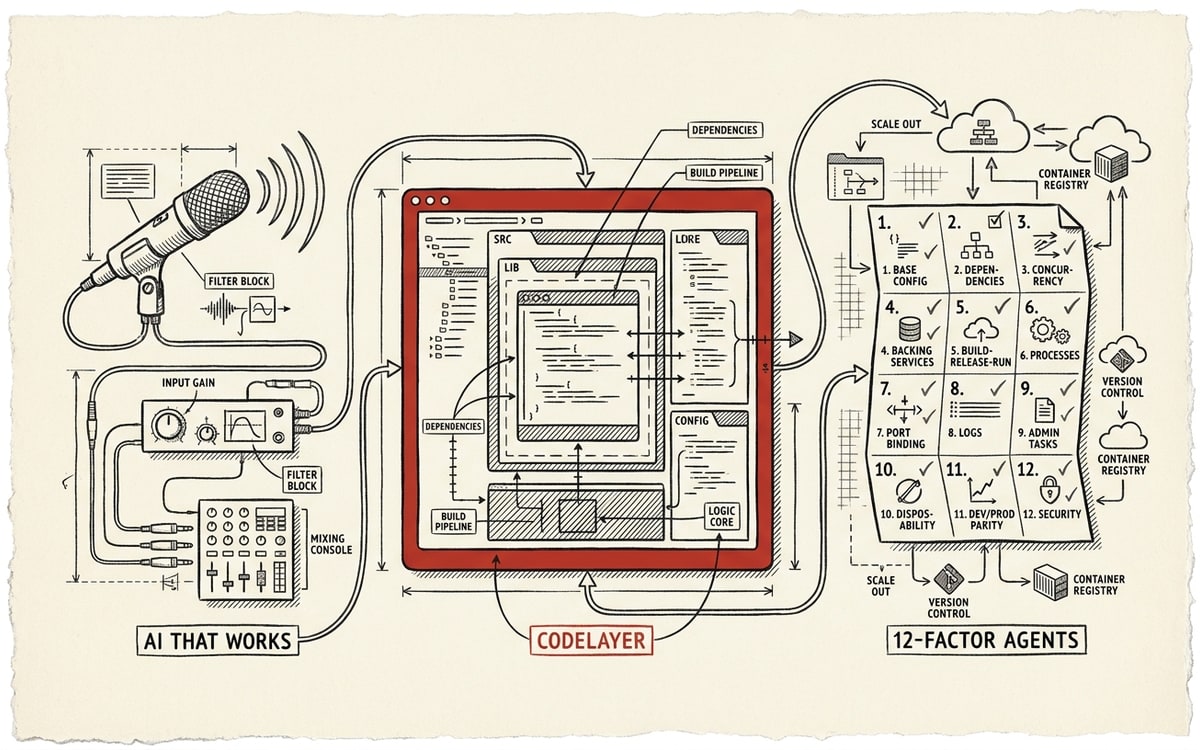
Most of the seven voices in §4 are individuals. HumanLayer is a company, and the company is shipping the productized version of the discipline its blog is documenting. That is rare enough to be worth the longer treatment.
The shape: Dex Horthy and Kyle (his cofounder) run HumanLayer out of San Francisco. Dex was previously at Replicated, Sprout Social, and NASA. He runs the SF AI Tinkerers community. The company has been writing about agents since spring 2025; 12-Factor Agents is dated April 3, 2025, and their cadence on the blog has been roughly weekly through 2026. The output has three layers.
The bottom layer is the manifesto. 12-Factor Agents is a structured list of twelve principles for building production-grade LLM systems, modeled on the original 12-Factor App. Each factor (titles like Own your prompts, Own your context window, Treat tools as functions, Errors are part of the spec, and Trigger from anywhere, meet users where they are) gets one or two paragraphs of practical guidance with a working code snippet. The repository has 19,601 stars at time of writing. The framing line, repeated everywhere: “Most quality production AI agents aren’t that agentic. The best ones are mostly just software.”
The middle layer is the post catalog. Advanced Context Engineering for Coding Agents (August 29, 2025, by Dex), A Brief History of Ralph (January 6, 2026), Context-Efficient Backpressure for Coding Agents (December 9, 2025), Writing a Good CLAUDE.md (November 25, 2025), Long-Context Isn’t the Answer (March 23, 2026), Skill Issue (March 12, 2026, by Kyle), Getting Claude to Actually Read Your CLAUDE.md (March 17, 2026). Plus a podcast (AI That Works, with co-host Vaibhav Gupta) on weekly cadence covering whatever harness or context technique they have been wrestling with. Plus the talk circuit. Dex’s 12-Factor Agents talk at AI Engineer Code Summit has 275,000 views; his No Vibes Allowed talk at the November 2025 AI Engineer event was the keynote.
The top layer is the product. CodeLayer is what HumanLayer sells: currently waitlist-only, tagline “Close your editor forever.” Their pitch frames it as “the post-IDE IDE” and “Superhuman for Claude Code.” It orchestrates multiple Claude Code sessions in parallel using git worktrees, remote cloud workers, and structured context-engineering workflows. The target customer: a team scaling AI-first development beyond a single developer who wants to run five or ten coding-agent sessions concurrently and keep them coherent.
The interesting alignment is between the layers. HumanLayer sells the productized version of the disciplines they document. 12-Factor Agents tells you to own your context window and treat tools as functions; CodeLayer is the runtime that does that for you across many parallel sessions. Skill Issue says failures are configuration; CodeLayer ships configuration. Brief History of Ralph documents the loop pattern; CodeLayer turns it into a one-button workflow. The blog is not marketing in the standard sense — it is the product roadmap, written backward.
This is rare. Most AI infrastructure companies write blog posts that abstract away from their product so they can pretend to be neutral; or they write product launches that abstract away from the discipline so they can pretend the work is original to them. HumanLayer is doing the opposite: building the productized version of a discipline they are openly contributing to, and naming the contributions of others (Geoff Huntley’s Ralph loop, Anthropic’s Claude Agent SDK, Mitchell Hashimoto’s harness engineering coining) alongside their own.
Whether CodeLayer becomes a real business depends on a different question — whether enough teams actually run five parallel Claude Code sessions to justify a multi-seat IDE. We don’t know yet. The waitlist is private. The product is unreleased. The blog is a real asset either way.
The harness-engineering community has more voices than most people outside it realize. Dex’s twelve thousand-plus monthly readers, Vaibhav’s BAML-Boundary work, Kyle’s brownfield-enterprise field reports, the NASA / Replicated / Sprout pedigree — none of that has the visibility of Anthropic or Google Cloud, but it produces a substantial fraction of the practical writing on the topic. HumanLayer is the cleanest example of a small company building a distribution business out of being the public chronicler of a discipline.
The HaaS shift
The economic claim that pulls this together is the one Viv Trivedy made in The Claude Code SDK and the Birth of HaaS on September 23, 2025:
“As tasks require more autonomous behavior from agents, the core primitive for working with AI is shifting from the LLM API (chat style endpoints) to the Harness API (customizable runtimes). I call this Harness as a Service (HaaS).”
Two years ago, building an agent meant calling the OpenAI completions API in a loop, parsing the model’s tool calls yourself, executing them yourself, managing context yourself. Today the dominant default is to start from a runtime (Claude Agent SDK, Codex CLI as a library, OpenCode’s @opencode/sdk, plus the framework family of Flue, just-bash, Mastra, and Inngest agent-kit), then customize prompts, tools, and policies on top. The loop is no longer something you build. The compaction, the hooks, the sandboxes, the permission gates, the observability layer — all of it ships with the runtime.
Anthropic operationalized HaaS first in production with the Claude Agent SDK (September 29, 2025): “The new Claude Agent SDK exposes the same harness Claude Code uses, with full programmatic access.” OpenAI followed with Codex CLI as both a product and a library — the full Rust monorepo at openai/codex is intentionally consumable as a dependency. SST shipped OpenCode at 157,600 stars as of May 2026; the same TypeScript codebase is the CLI you install and the SDK you import.
The framework set is larger and growing. Flue is built by the Astro team and inspired by Fred Schott’s earlier auto-triage experiments at Astro, which TDF covered here. It pitches itself as “The Agent Harness Framework. It’s like Claude Code, but 100% headless and programmable.” Skills, AGENTS.md, and tools live as Markdown. Default sandbox is virtual, powered by vercel-labs/just-bash. Mastra at 23,700 stars is the general-purpose TypeScript agent framework from the Gatsby team. The pitch: agents, workflows, tools, plus RAG, memory, evals, and MCP, all as composable concepts. Inngest agent-kit treats agent loops as durable workflows: each LLM call is an Inngest step that can be retried, replayed, or resumed across deploys. Mario Zechner’s pi-agent-core (yes, the libGDX guy) is a leaner alternative with first-class context-management primitives.
The economic shape that matters: in a HaaS world, the runtime is the moat, not the model. The model is interchangeable to the extent the runtime supports model swaps, which all the major harnesses now do (OpenCode’s provider() selector, Cline’s variants directory, Aider’s per-model edit-format selection). The harness encodes the path-dependence. Codex’s apply_patch works best with Codex models because both were trained together; Claude Code’s tool naming works best with Claude because the same teams designed it. The product surface that gets sold is the runtime plus its specific tuning. The model becomes a swappable commodity input.
The Anthropic-OpenAI-Google parallel matters here. Anthropic ships the Claude Agent SDK (the runtime) plus Claude (the model). OpenAI ships Codex CLI (the runtime) plus GPT-5.2-codex (the model). Google ships the Agent Development Kit (the runtime) plus Gemini (the model). All three labs are now selling runtime + model bundles where the runtime is the product surface and the model is the engine. That is the HaaS shift in concrete terms.
The remaining question is whether the runtime layer commoditizes faster than the model layer. If two open-source HaaS frameworks reach Claude Code parity by 2027 (the trajectory we’d extrapolate from OpenCode’s 157k-star year), then the lab-runtime-bundle stops being defensible. Builders will configure on top of an open framework and swap the model underneath. The labs’ moat would shrink to model quality alone, which is exactly the dimension where they are losing differentiation.
That is the bet HumanLayer is making with CodeLayer (waitlist-only, openly built on Claude Code’s harness). It is the bet SST is making with OpenCode. It is the bet the Astro team is making with Flue. None of them are model providers. All of them are betting that the harness layer is where the next decade of agent product gets built.
Where this is going
Five open frontiers, in roughly increasing order of how far they are from solved.
Self-analyzing harnesses. Today the Ratchet is manual: a developer notices an agent failure, opens AGENTS.md, adds a rule. The natural next step is for the harness to do this itself: read its own traces, identify recurring failure modes, and propose new rules, hooks, or subagent guardrails. Addy mentions this in Agent Harness Engineering: “agents that analyze their own traces to fix harness-level failures.” No production implementation exists yet. The closest analogues are smolagents’ structured ActionStep/PlanningStep records and Cognition’s SWE-grep, both of which give agents a structured trace surface to read from. Building an agent that closes the Ratchet loop (observe failure, propose fix, apply fix, verify) is one of the cleaner unsolved problems in the field.
Just-in-time tools. Every agent on the §5 list pre-loads its tool set at session start. The loaded list is finite by necessity (every additional tool adds tokens to every prompt) but the world’s MCP ecosystem now has more than 20,000 servers. The mismatch is obvious: the agent should be able to discover tools as the task requires them rather than load them upfront. Codex CLI’s tool_search is the closest production attempt, but it operates on a pre-known registry. What’s missing is a runtime that, given a task, semantically retrieves the right tools from a much larger catalog and loads them into context only when needed. This was Addy’s most-cited unsolved problem.
Harness-as-compiler. The most-quoted line from his post: “harnesses stop being static configuration files and start acting much more like compilers.” The compiler analogy is concrete: harness configurations get optimized against the agent’s task distribution. Inactive rules get pruned. Frequently-triggered hooks get inlined. Subagent prompts get auto-tuned against observed eval data. Today’s harness is hand-written. Tomorrow’s harness might be hand-specified at the high level and machine-optimized at the low level, the same way modern compilers turn human-readable C into ruthlessly tuned machine code. The discipline would shift from “write the right AGENTS.md” to “write the right spec; the runtime tunes the rules.”
Model-harness co-design. The Codex’s apply_patch overfitting case is concrete: post-train a model with a specific tool-call format and the model gets exceptionally good at that format and worse at neighboring formats. The forward direction of this (“design a new harness, then post-train the model to fit it perfectly”) is what Anthropic and OpenAI already do internally. The reverse direction (“design a harness optimized for an existing model’s idiosyncrasies”) is what Cline’s per-model variant directory and OpenCode’s per-model prompt files implement empirically. Neither is general theory yet. The field still doesn’t have a principled answer to “given model M and task T, what is the optimal harness H?” It has heuristics and benchmarks. The theory comes later.
Multi-agent emergent behavior. The genuinely open frontier, and the one where Cognition’s roadmap is most ambitious. Their April 2026 Multi-Agents: What’s Actually Working post ends with a list of patterns that are starting to show up: dispatcher-worker, planner-executor, manager-of-Devins, parallel-explorer with merge step. None has a clean theoretical justification yet. They’re empirical observations from production. What the field does not have, and badly needs, is a way to predict which multi-agent topology fits a given task. Today every team experiments. Tomorrow there might be a theory.
We notice that the open problems all point in the same direction: the next layer of harness engineering is self-modifying. Agents that read their own traces. Tools that load themselves. Rules that compile and prune. Topologies that auto-select. The static-configuration phase of the discipline is winding down. The dynamic phase is starting.
What to build
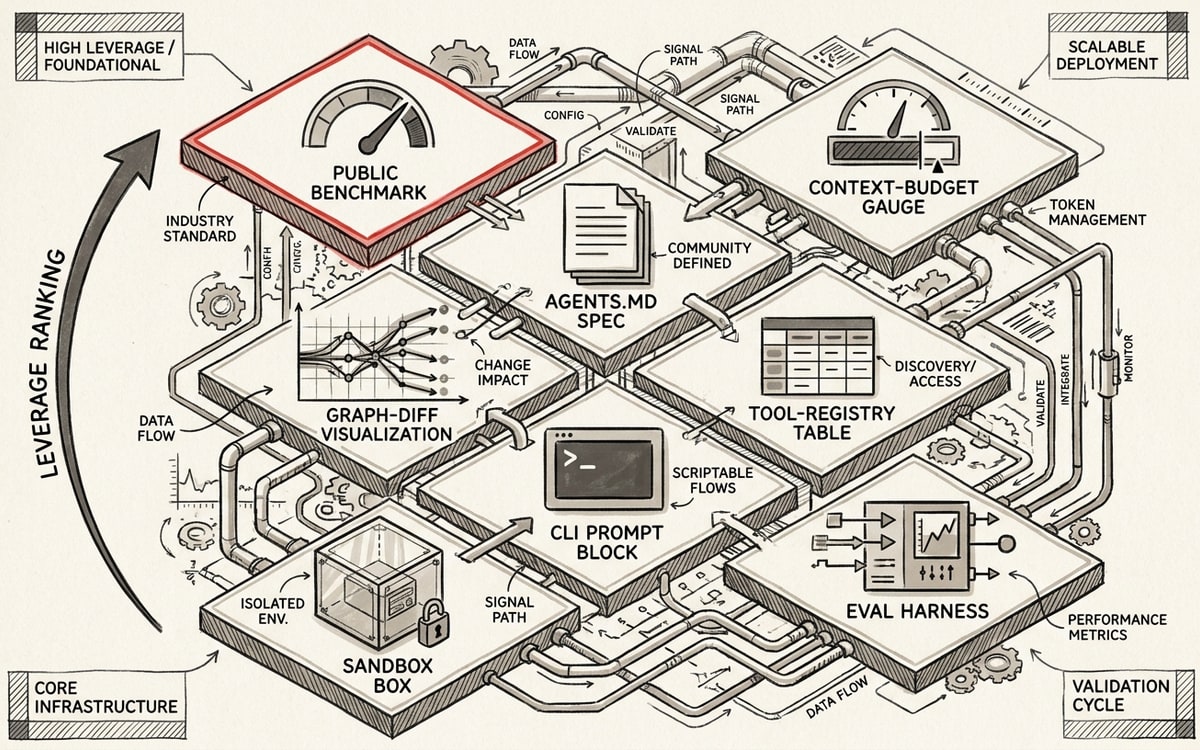
This is the workshop section. Eight concrete artifacts that don’t exist yet and would have outsized impact if they did, ordered roughly by how much each offers relative to the work involved. We’re framing them as invitations rather than as a roadmap. The Deep Feed reports; readers build.
1. A public benchmark that isolates harness contribution from model contribution. Run a defined SWE-bench-Verified subset across Claude Code, Cursor, Codex CLI, Aider, Cline, OpenCode with their default harnesses, then with the same model swapped in across all of them where possible. Publish the harness gap, not the model gap. Viv’s deepagents-cli result (rank 30 → rank 5 on Terminal Bench 2.0 by changing only the harness) is the cleanest controlled experiment in the field; no public benchmark replicates it across the full agent set. Whoever builds this owns the citation surface for the next two years of harness arguments.
2. A visual diff tool for AGENTS.md files across open-source repos. Today every team is rediscovering the same five rules independently. A side-by-side comparison of the AGENTS.md files in the top hundred trending GitHub repos would surface common patterns, identify which rules are universal versus repo-specific, and probably prompt a community spec. Closest analogue: the way Dependabot’s pull-request templates created a de-facto standard for security advisories.
3. A failure-ratchet CLI. Take an AGENTS.md file plus a directory of agent traces. Output: a proposed list of new rules, hooks, or subagent guardrails to add. The mechanism is direct — the trace shows what failed, the rule encodes the prevention. This operationalizes Mitchell’s Ratchet across teams that don’t have time to manually analyze every session log. The tool would be a couple of hundred lines on top of Claude Sonnet plus some glue code.
4. An MCP harness audit tool. Addy flagged this explicitly: “malicious or sloppy external integrations (like unverified MCP servers) can inject bad prompts into the agent before it even starts working.” MCP has 20,000+ servers in the wild. There is no public security scanner for prompt-injection vectors in tool descriptions. Building one is straightforward (read the tool description, run it through an LLM-as-judge with an injection-detection prompt) and the audit data becomes valuable to every harness operator. Low-hanging, high-value.
5. A just-in-time tool framework. Pick a handful of MCP servers, build a semantic retrieval layer that picks tools per task, expose it as an OpenAPI service. Every harness on the §5 list could plug into it. The first working implementation would also be a paper-grade research artifact, since dynamic-tool selection is one of Addy’s named open problems.
6. A HaaS framework comparison matrix that is actually maintained. Flue, just-bash, pi-agent-core, Mastra, Inngest agent-kit, smolagents — adoption numbers, design choices, “when to pick which,” version bumps tracked over time. Lives somewhere between awesome-list and Stack Overflow’s annual developer survey. Becomes the canonical reference if updated quarterly.
7. A clean, source-linked, regularly-updated annotated edition of claude-code-from-scratch. Fareed Khan’s reverse-engineering is the best public reference for Claude Code internals, but it lives on Medium with a paywall and a JS challenge that blocks unauthenticated access. A version on a stable URL with line-by-line annotations and update tracking, paired with a contributor model so the community can keep it current as Anthropic ships changes, would become the canonical reference for understanding production harness internals.
8. A community spec for AGENTS.md. The agents.md convention exists. What doesn’t exist is a structured schema — what fields belong in there, what each section should look like, what conventions for hooks, subagents, permission gates. The 12-Factor Agents pattern but at one layer below: a checklist for what a good AGENTS.md contains. Whoever ships this first becomes the Heroku-12-Factor of the harness era.
If even three of these get built in the next twelve months, the discipline gets a meaningful productivity boost. Each of them is small enough to ship as a weekend project plus follow-through. None requires custom model training. The ecosystem is an unusually friendly place to publish work right now — every voice in §4 amplifies serious contributions, the bookmark-to-like ratios on substantive posts are unusually high, and the named contributors are all approachable.
A discipline that crystallized in nine months
Return to the bookmark count. 1,499 bookmarks against 716 likes on a director-level post about a configuration practice. Bookmarks are how an audience signals I will need this later. The audience signal in this case was I have been collecting fragments of an idea for nine months and finally have the synthesis.
The fragments accumulated unusually fast. Mitchell Hashimoto on February 5. Birgitta Böckeler’s Context Engineering for Coding Agents the same day. Viv Trivedy on February 17, then March 10. HumanLayer on March 12, March 17, March 23. Anthropic’s Harness design for long-running application development on March 24. Birgitta’s Harness engineering for coding agent users on April 2. Fareed Khan on April 6. Then Addy on April 19 and the synthesis tweet on May 9. Eight months of high-frequency, high-quality writing from seven independent voices, none of whom were coordinating, all converging on the same vocabulary.
The discipline has structural qualities that explain the convergence. The model providers are publishing harness research at depths they didn’t a year ago because they have to — the harness layer is where their products differentiate now. The framework builders are publishing because the runtime layer is where the next moat sits. The practitioners are publishing because they have a year of brownfield-enterprise experience and the field has zero institutional knowledge to draw on. The reverse-engineers are publishing because the leaked source map of Claude Code briefly exposed an entire production harness to the public. None of these voices needed each other to start writing. The reason they all show up in the same Addy Osmani synthesis is that they are all addressing the same operational problem: the model is one input; how do you build the rest of the system?
Twelve coding agents implemented the same primitives independently. The closed-source production tools (Claude Code and Cursor in the editor; Devin, Replit, and Warp Oz in the cloud) all converged on the same shape as the open-source field (Codex CLI and Aider, plus Cline, OpenCode, and goose, plus Continue and smolagents). Hooks. Subagents. Sandboxes. Memory files. Compaction. MCP. Permission gates. Some are more elaborate than others. None are missing. The same shape, in twelve different code bases, in eighteen months.
Two coiners. Mitchell named it. Viv defined it. Both should be cited.
The name fits. A harness is what you put on the animal that does the actual pulling. The model is the animal: the source of capability that nobody fully understands. The harness is what makes the work usable. Everything you can engineer about the system is harness — the prompts, the tools, the context policies, the hooks, the sandboxes, the subagents, the feedback loops, the recovery paths. Engineering the harness is what working developers do every day on every coding-agent project, whether they call it that or not.
We close on the line that earned the synthesis its bookmark count, from Addy Osmani’s Agent Harness Engineering, April 19, 2026:
“If you look at the top coding agents today, they look more like each other than their underlying models do. The models differ, but the harness patterns are converging.”
The model is one input. Everything else is engineering.