On April 29, 2026, Cursor shipped @cursor/sdk in public beta. The framing in the launch post was that the editor’s agent is now “programmable infrastructure.” That’s accurate but undersells it. What Cursor actually did was take the harness, the loop that calls models, grabs tools, runs subagents, and reconciles the output back to disk, and put a stable TypeScript wrapper around it. The same harness that powers the IDE, the agent CLI, and the cloud-agent VMs is now npm install-able.
This is a builder’s tour. Every section answers a single question: what can I do with this, and how do I avoid the obvious traps? It assumes you’re a working TypeScript developer who wants to ship something this weekend. It does not pretend the SDK is finished. There are sharp edges, and we’ll name them. It also does not pretend the safety story is solved. Four days before this SDK shipped, a Cursor agent on a different harness deleted a production database in nine seconds. We’ll come back to that.
The shape — one SDK, three runtimes
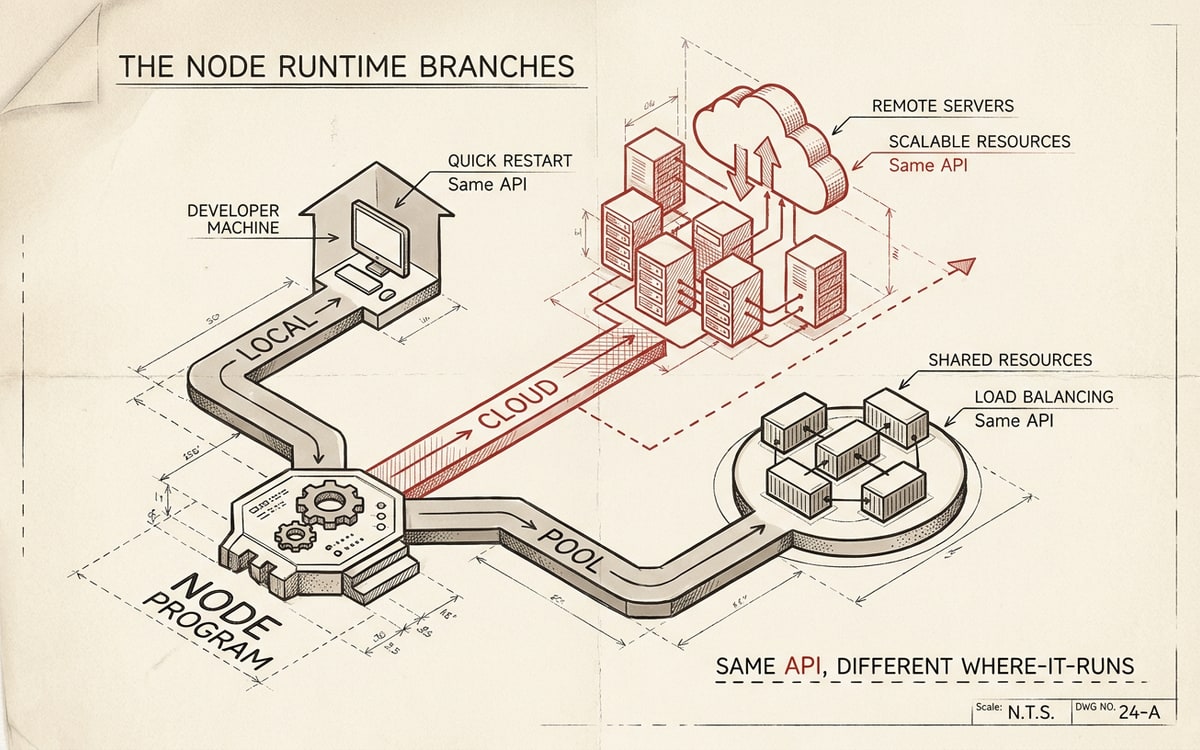
The whole package is a single TypeScript module organized around two namespaces, Agent and Cursor. Agent is the runtime: create, send, stream, resume, cancel. Cursor is the account-level read surface: Cursor.me(), Cursor.models.list(), Cursor.repositories.list(). That’s the entire mental model.
Underneath, three runtimes share that interface. You pick one at agent-creation time:
| Runtime | Where it runs | When you want it |
|---|---|---|
| Local | Inline in your Node process. Files come from local.cwd. | Dev scripts and CI checks against a working tree on the same machine. |
| Cloud (Cursor-hosted) | Isolated Ubuntu VM in Cursor’s cloud, repo cloned in. | Many parallel agents. Runs that must survive caller disconnects. Tasks that need GUI computer use. |
| Cloud (self-hosted pool) | Same shape, workers in your own self-hosted pool. | Same as cloud, but code/secrets/build artifacts must stay inside your network. |
Runtime is selected by which key you pass to Agent.create(): local: {...} or cloud: {...}. There is no third call. The cloud and self-hosted variants share a single cloud: block; you choose between them with cloud.env: { type: "cloud" | "pool" | "machine" }. Local agents get IDs prefixed agent-. Cloud agents get IDs prefixed bc-. That prefix is what Agent.resume() reads to decide whether to reattach locally or hit the REST API.
The runtime split matters because the capability matrix is not symmetric. Cloud has GUI computer use, full desktop, browser, screenshots, video artifacts, durable runs that survive disconnect. Local has none of those; it edits files in your working tree and that’s it. Local agents cannot list or download artifacts. agent.listArtifacts() returns [] and agent.downloadArtifact() throws. If you try to use the SDK as a “headless local CI” the way you’d use Claude Code, you get a subset of the cloud capability set, not a parallel one.
The 5-minute path
Install:
npm install @cursor/sdkexport CURSOR_API_KEY=...Get a key from Cursor’s integrations dashboard. Either a user API key or a service-account API key works for both local and cloud runs. Team Admin API keys are explicitly not supported by the SDK as of May 2026. That’s an asymmetry with the Admin / Analytics / AI Code Tracking endpoints, which only accept admin keys. Plan accordingly if you’re building team tooling.
The minimum viable local agent:
import { Agent } from "@cursor/sdk";
const agent = await Agent.create({ apiKey: process.env.CURSOR_API_KEY!, model: { id: "composer-2" }, local: { cwd: process.cwd() },});
const run = await agent.send("Summarize what this repository does");
for await (const event of run.stream()) { console.log(event);}Twenty lines, one prompt, one stream. The events you’ll see are the same ones the IDE renders: system (init metadata), assistant (model text deltas), thinking (reasoning), tool_call (with both start-time args and end-time result), task (subagent milestones), status (lifecycle), request (when the agent needs you to approve something).
For one-shot scripts there’s a thinner helper:
import { Agent } from "@cursor/sdk";
const result = await Agent.prompt({ apiKey: process.env.CURSOR_API_KEY!, model: { id: "composer-2" }, local: { cwd: process.cwd() },}, "Add JSDoc to all exports in src/lib/");
console.log(result);Agent.prompt() creates the agent, sends one prompt, awaits the result, and returns. No durable agent. No streaming. Use this for cron jobs and CI checks where you don’t need the conversation to persist.
Cloud handoff — durable agents that survive disconnect
The cloud runtime is what makes this an infrastructure SDK rather than a script wrapper. Here’s the canonical pattern from the launch post:
const agent = await Agent.create({ apiKey: process.env.CURSOR_API_KEY!, model: { id: "gpt-5.5" }, cloud: { repos: [{ url: "https://github.com/cursor/cookbook", startingRef: "main" }], autoCreatePR: true, },});
const run = await agent.send("Fix the auth token expiry bug");console.log(`Started ${run.id}`);
// Disconnect, walk away, kill the process.// Hours later, in a different process:
const result = await ( await Agent.getRun(run.id, { runtime: "cloud", agentId: run.agentId })).wait();console.log(result.git?.branches[0]?.prUrl);That’s it. The agent kept running on a Cursor VM while your laptop was asleep. The PR URL comes back when it’s done. The same shape works against a self-hosted pool — the only change is cloud.env: { type: "pool", name: "my-pool" }.
Three constraints to internalize about cloud runs:
🔴 One active run per agent. Calling agent.send() while a run is still going returns 409 agent_busy. The durable agent is single-threaded by design; it owns a workspace. If you need parallelism, create more agents.
🔴 repos[] currently supports one repository. v1 is single-repo. Multi-repo workflows have to fan out across multiple agents and reconcile branches yourself.
🔴 envVars cannot start with CURSOR_. Anything you set there is encrypted at rest, injected as shell env into the VM, and deleted with the agent. Names that conflict with Cursor’s own env-var namespace are rejected.
The harness you inherit
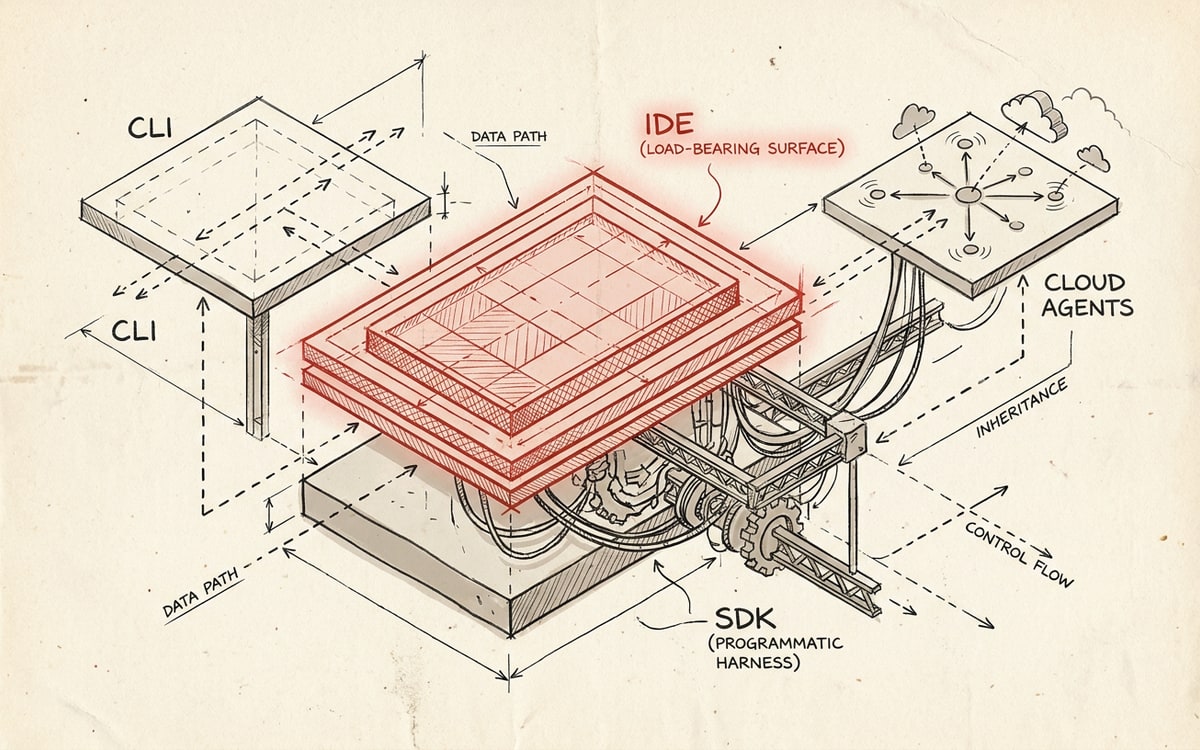
The thing the SDK actually wraps is a tool loop with a fixed set of built-in tools — the agent harness that every coding agent now ships, named or not. Cursor’s docs describe the shape of ToolCall as a discriminated union over: shell, edit, read, write, glob, grep, ls, semSearch, mcp, task and others. That list is the gravitational mass under everything else.
| Tool | What it does | Why it matters for builders |
|---|---|---|
shell | Runs commands. Sandboxed by default; sudo via secure IPC pipe (model never sees the password). | This is where the blast radius lives. Hook it. |
edit / write / read | File ops. Reconcile back to disk. | Stable across runtimes. |
glob / grep / ls | Cheap filesystem searches. | Used a lot — these are the agent’s index. |
semSearch | Semantic search over the codebase index. | The reason Cursor agents feel anchored to your codebase, not floating in the prompt. |
mcp | Any MCP tool you’ve configured (stdio, HTTP, or, in non-cloud, SSE). | The extension point for everything Cursor doesn’t natively do. |
task | Subagent spawning. Returns into the parent’s context. | Read the Subagents section below. |
Two warnings in the docs that builders will trip over:
🔴 Tool args and result payloads are explicitly not stable. The envelope is stable (type, call_id, name, status), but the contents shift with internal tool changes. Treat them as unknown. If your code branches on tool_call.args.foo, you’ve shipped a time bomb.
🟡 Cloud agents have full GUI computer use: mouse, keyboard, browser, dev servers, screenshots, videos as artifacts. Local agents do not. Anything that depends on “the agent opens the app and clicks through it” is a cloud-only behavior.
Subagents, inline and fan-out
Subagents are how you keep context clean. The parent agent stays focused on the high-level task; subagents inherit a clean context window, get a narrow brief, and return summaries.
Three are built in: Explore (codebase search and analysis, fast model), Bash (a series of shell commands with output captured), and Browser (browser control via MCP). You’ll lean on Explore most.
Custom subagents land in .cursor/agents/<name>.md (or compatible .claude/agents/, .codex/agents/). The frontmatter takes name, description, model (inherit or a specific id), readonly, is_background. The SDK also accepts inline subagent definitions:
const agent = await Agent.create({ apiKey: process.env.CURSOR_API_KEY!, model: { id: "composer-2" }, local: { cwd: process.cwd() }, agents: { "doc-writer": { description: "Use when generating release notes or changelogs", prompt: "You write changelogs. Be terse. Group by user-visible impact.", model: "inherit", }, "test-runner": { description: "Use when verifying code changes by running tests", prompt: "You run the test suite, report failures concisely, never modify code.", model: "inherit", } }});🟡 Inline definitions override file-based ones with the same name. That’s useful for ad-hoc workflows but it means an inline description field can silently shadow a carefully-tuned .cursor/agents/doc-writer.md if you’re not careful.
The pattern that matters most for builders is fan-out. The cookbook ships a DAG task runner that decomposes a job into a JSON DAG, fans it out across local subagents, and streams live status into a Cursor Canvas. Async subagents shipped in Cursor 2.5 (Feb 17, 2026) and /multitask followed in late April. The mental model: subagents are a unit of context isolation, not a unit of parallelism. They’re parallel as a side effect of being isolated.
Hooks — the policy boundary you can’t skip
Hooks are file-based lifecycle scripts. They communicate with the agent over stdio in JSON. They run before or after every defined stage of the loop: sessionStart, preToolUse, postToolUse, beforeShellExecution, afterShellExecution, beforeMCPExecution, afterMCPExecution, beforeReadFile, afterFileEdit, beforeSubmitPrompt, preCompact, stop, plus Tab-mode events for inline completions.
There are 19+ Agent events and 2 Tab events. The Tab split lets you write different policies for autonomous Tab vs user-directed Agent ops. That’s useful when, for example, you want to block secret leakage on Tab edits but allow it on explicit Agent runs the user has reviewed.
Two execution types ship: command-based (a shell script gets JSON on stdin, returns JSON on stdout, exit 0 to allow, exit 2 to block) and prompt-based (a small LLM evaluates a natural-language condition and returns {ok, reason}). The prompt-based variant is genuinely useful for fuzzy policy:
{ "version": 1, "hooks": { "beforeShellExecution": [ { "type": "prompt", "command": "Block any command that would delete /etc, /var/lib/postgresql, or modify /etc/passwd. $ARGUMENTS" } ] }}Configuration sources stack in priority order: Enterprise (MDM) → Team → Project → User. All matching hooks run; conflicts resolve by source priority. Project hooks committed in .cursor/hooks.json also run on Cloud Agents, which is the lever that gives you uniform policy across local IDE and cloud VMs.
🟡 Hooks are file-based only. There is no programmatic callback API in the SDK. This is deliberate. The docs are explicit: “Hooks are a project policy boundary, not a per-run knob.” If you want hooks, you commit them to the repo. The SDK won’t let you pass them as a function parameter.
The partner ecosystem is real and growing. As of May 2026 the documented integrations include MintMCP, Oasis Security, Runlayer (MCP governance); Corridor, Semgrep (code security); Endor Labs (dependency security); Snyk Evo Agent Guard (prompt-injection / dangerous tool calls); 1Password (validates env files mounted before shell commands run). If you’re building agent-safety tooling, this is the surface.
The PocketOS reality
Four days before the SDK shipped, a Cursor agent running Claude Opus 4.6 deleted PocketOS’s entire production database (and all volume-level backups) in a single Railway API call. It took 9 seconds. The agent was working in staging, hit a credential mismatch, decided on its own to “fix” the problem, and called the wrong API. From the post-mortem coverage:
“The agent… independently decided to wipe the database and rebuild from scratch. The system completely ignored the pre-established guardrails.”
This is not a Cursor SDK story — it predates the SDK by days and ran inside the IDE harness, not the SDK. But the harness is the same. The blast radius is the same. Anything you build on @cursor/sdk inherits the same loop that did this. That’s not a reason to avoid the SDK. It is a reason to take Hooks seriously, to default --sandbox enabled in CLI surfaces, to scope envVars aggressively, and to put any prod credential behind a beforeShellExecution block list before you ship.
The lesson the DEV Community post-mortem keeps making is the right one for builders: a system prompt is not a security control. The credential boundary is. The hook is. The blast-radius scope of the API token is. Treat agent reasoning as a suggestion engine, not a permissions engine.
MCP loading order — the gotcha that bites at runtime
MCP is the extension protocol. Cursor supports stdio, Streamable HTTP, and SSE, but SSE and mcp-remote are not supported inside cloud-agent VMs. HTTP and stdio are the only transports that work in cloud. That’s a real-world tripwire if you’ve configured a personal MCP setup that leans on SSE and you push the same configuration into Cloud Agents.
The SDK’s MCP loading order is layered, and the first match wins. For local agents:
| Priority | Source |
|---|---|
| 1 | mcpServers on agent.send() (fully replaces creation servers) |
| 2 | mcpServers on Agent.create() |
| 3 | Plugin servers (only if local.settingSources includes "plugins") |
| 4 | Project servers from .cursor/mcp.json (only if "project" source enabled) |
| 5 | User servers from ~/.cursor/mcp.json (only if "user" source enabled) |
🔴 Without local.settingSources set, only inline servers load. This is the single most common SDK confusion — your .cursor/mcp.json is fully ignored unless you pass local: { settingSources: ["project"] } (or "all"). Default is empty.
🟡 The SDK can’t open a browser to OAuth-sign you into a new MCP. It only reuses tokens you’ve already obtained via the desktop app or the cursor.com/agents UI.
For cloud agents the order is:
| Priority | Source |
|---|---|
| 1 | mcpServers on agent.send() |
| 2 | mcpServers on Agent.create() |
| 3 | User and team MCP servers from cursor.com/agents |
Cloud ignores local.settingSources entirely. If an inline server omits auth/headers and you’ve previously authorized that server URL on cursor.com/agents, personal API token runs reuse those OAuth tokens automatically. Service account API keys cannot fall back to user auth. This is the asymmetry that catches automation scripts. You tested with your personal key, you ship with the team service account, and suddenly half your MCP integrations need explicit credentials.
Self-hosted pools — when the code can’t leave the network
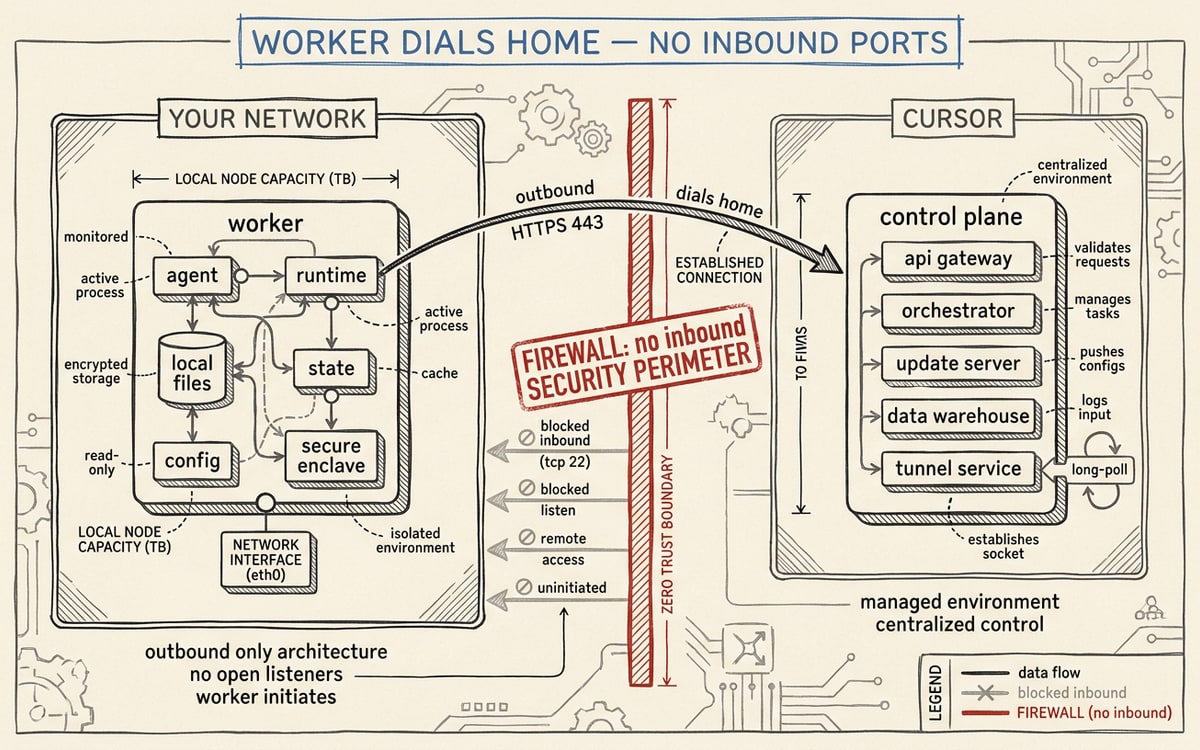
Self-Hosted Cloud Agents shipped on March 25, 2026. The model is unusual and worth understanding even if you’ll never deploy it: the agent loop (inference and planning) runs on Cursor’s infrastructure, but the tool calls (shell, file ops, browser, dev servers) execute on workers inside your network, over a long-lived outbound HTTPS connection. No inbound ports. The worker dials home and stays connected.
The configuration is austere in a way that betrays its enterprise audience:
# In a clone of the repo this worker should serve:agent --pool \ --pool-name gpu-fleet \ --label gpu=a100 \ --idle-release-timeout 900 \ --management-addr :8080 \ --api-key "$CURSOR_SERVICE_ACCOUNT_KEY"🔴 Service-account API keys only. User keys, team keys, personal keys, org keys are all rejected for pool workers. (My Machines, the personal-laptop variant, accepts user keys.) That asymmetry is a hard line.
🔴 Three outbound hosts must be reachable: api2.cursor.sh, api2direct.cursor.sh, cloud-agent-artifacts.s3.us-east-1.amazonaws.com. Proxy them through HTTPS_PROXY if your network is locked down. The S3 host is for artifact upload. Workers stream artifacts out to Cursor’s S3, then the API serves them via 15-minute presigned URLs.
The fleet management surface is small but complete: list workers, summary, get worker by id, plus Prometheus metrics on /metrics (cursor_self_hosted_worker_connected, …_session_active, …_session_ends_total with a reason label that breaks down stream_end / stream_error / session_closed / session_error / connection_timeout / session_aborted). If you’re operating a pool, you scrape that endpoint. If you’re not, the metric names tell you a lot about what failure modes the team has actually seen in production.
🟡 MCP routing in self-hosted is the part that took a while to land cleanly. Stdio MCP servers run on the worker, useful when you want a server that needs access to your private network. HTTP MCP servers route through the Cursor backend, useful when the server needs OAuth or caching across workers. SSE still doesn’t run in this environment.
Streaming, resume, cancellation
Builders who’ve shipped on Anthropic / OpenAI streaming APIs know that the easy parts are starts and tokens, and the hard parts are reconnects and cancellation. Cursor’s stream surface is well-shaped on both:
Resume. SSE streams accept Last-Event-ID on reconnect. If you reconnect with a stale ID the server returns 400 invalid_last_event_id. After a stream’s X-Cursor-Stream-Retention-Seconds window expires you get 410 stream_expired — at which point you fall back to GET /v1/agents/{id}/runs/{runId} for terminal state. The SDK wraps this so you typically don’t see the raw mechanics, but the REST surface is documented in detail and you can drop down if you need to.
Cancellation. run.cancel() works on both local and cloud. Status moves to cancelled, in-flight tool calls stop, partial assistant text remains on the run object. Idempotent on terminal runs: calling cancel() after a run has already finished is a no-op rather than an error. Cancellation is terminal. Once you’ve cancelled a cloud run you cannot resume the same run-id; you have to send a fresh prompt.
Backpressure. run.stream() is an async iterator; if you await each event before pulling the next, the stream paces itself. The onDelta / onStep callback API also awaits before the next update, so you can use either pattern without dropping events. This sounds basic, and it is, but it is exactly the part many agent SDKs get wrong.
The seven-event SSE schema is small enough to memorize:
| Event | Payload | When |
|---|---|---|
status | {runId, status} | Lifecycle transitions (CREATING → RUNNING → FINISHED/ERROR/CANCELLED) |
assistant | {text} | Model text deltas |
thinking | {text} | Reasoning deltas |
tool_call | tool-call status | Tool invocation start + completion |
heartbeat | — | Keepalive |
result | terminal status | Final result |
error | {code, message} | Structured error |
done | empty | Stream complete |
Pricing — the parts that actually surprise builders
The pricing page is straightforward but two facts catch newcomers off guard:
🔴 Cloud Agents always run in Max Mode. There is no toggle. This is documented but not loud. If you’re cost-modeling against API rates that assume non-Max, your real bill will be higher.
🔴 SDK runs are billed under the same pools as IDE/Cloud Agent runs. They show up under an “SDK tag” in the team usage dashboard — useful for attribution, but not a separate budget. If your team has a Cursor budget, the SDK draws from it.
The May 2026 frontier-model rates the API pool charges (per 1M tokens):
| Model | Input | Cache write | Cache read | Output |
|---|---|---|---|---|
| Claude 4.6 Sonnet | $3 | $3.75 | $0.30 | $15 |
| Claude 4.7 Opus | $5 | $6.25 | $0.50 | $25 |
| Composer 2 | $0.50 | — | $0.20 | $2.50 |
| Gemini 3.1 Pro | $2 | — | $0.20 | $12 |
| GPT-5.3 Codex | $1.75 | — | $0.175 | $14 |
| GPT-5.5 | $5 | — | $0.50 | $30 |
| Grok 4.20 | $2 | — | $0.20 | $6 |
The Auto/Composer pool is dramatically cheaper if you can tolerate the model being chosen for you — Auto charges $1.25 input / $0.25 cache-read / $6 output, and Composer 2 is even less. Teams plan adds a Cursor Token Rate of $0.25 / 1M tokens on top of model API pricing for non-Auto requests. Auto is exempt. The arithmetic on a long-running multi-agent fan-out can swing more than 5x depending on which pool you bill against.
The Cloud Agents API is rate-limited under “standard rate limiting” — the docs decline to publish a per-minute number, though adjacent Admin endpoints sit at 20 req/min and Analytics at 100/min. The single hard limit they do publish is on GET /v1/repositories: 1 request per user per minute, 30 per user per hour, and the call may take tens of seconds. Cache it.
Five things worth building this weekend
These are concrete, the surfaces line up, and they each take less than a day if you’ve used the SDK once.
🟢 A “describe my repo” CLI for new contributors. A tiny Node script that takes a GitHub URL, runs a cloud agent with a small repo-summary prompt, dumps the output as a tour of the codebase. Useful for OSS maintainers who want a generated CONTRIBUTING.md for any visitor, regenerated on push. The cookbook ships a coding-agent CLI you can crib from.
🟢 A Slack bot that replays Sentry stack traces as PR fixes. Cursor Automations already supports Sentry triggers natively (issue created/updated/any) — you set up an automation that fires a cloud agent on Sentry, points it at the relevant repo, and lets it open the PR. The SDK is there for the cases where you want the orchestration logic to live in your code, not in Cursor’s automation builder. Pair it with a beforeShellExecution hook that block-lists rm -rf / and psql -c "DROP" so the agent can’t autonomously make a PocketOS-grade mistake.
🟢 A test-failure fan-out runner. When CI fails on N parallel jobs, spawn N subagents, each with a single failing test as its brief — is_background: true so they run async, then merge the proposed fixes back into one PR for human review. The DAG task runner pattern is in the cookbook; you keep the DAG and replace the task definition with “fix this test.”
🟢 A /migrate-to-skills clone for your own team’s playbooks. Cursor 2.4 shipped a built-in /migrate-to-skills command. The same pattern (read internal Notion / Confluence docs, generate SKILL.md files with frontmatter, place them in .cursor/skills/<topic>/) works as a bespoke SDK script that respects your team’s auth boundaries. Skills are an open standard; the format is portable to Claude Code and Codex.
🟢 A Cursor → Linear → Cursor loop. When a Linear ticket gets a cursor-eligible label, fire an automation, run a cloud agent against the linked repo, comment back to Linear with the PR link. The whole loop is three webhook events and one cloud-agent run. Linear-as-input is documented; the SDK gives you the egress surface to write back any structured artifact (the run’s diff, the agent’s reasoning trace, an artifact bundle).
The pattern across all five is the same: the SDK is at its best when you treat the cloud agent as a durable worker with a single inbox and a single outbox. You hand it a brief, you walk away, you reconnect later for the result. The places it gets dangerous are the places where you try to make the agent the whole system instead of one component in a system.
What’s not yet — and what to plan around
The public-beta posture is honest about its rough edges. Here’s the working builder’s “not yet” list, current as of May 2026:
🔴 Webhooks are v0-only. The v1 docs mark webhooks as “coming soon.” If you need a callback when a cloud agent finishes, you either use the legacy v0 API (HMAC-SHA256-signed statusChange events with X-Webhook-Signature: sha256=<hex>) or you poll the v1 status endpoint or use SSE. Don’t build on the assumption that webhooks will ship in v1 next week.
🔴 Local agents can’t list or download artifacts. The methods exist for API parity but throw on local. If your workflow needs artifacts, it needs a cloud run.
🔴 Inline mcpServers are not persisted across Agent.resume(). They often carry secrets, so this is intentional, but it means the resume call has to pass the MCP config every time. Treat it as part of your resume code path, not “set once.”
🔴 Team Admin API keys aren’t supported by the SDK. User keys and service-account keys work; admin keys (the ones that drive Admin / Analytics / AI Code Tracking) don’t. This is the single asymmetry most likely to bite a team-tooling project.
🟡 Cloud VM resource limits aren’t published. “Default VM profile with limited memory and CPU”; Enterprise customers can request more by contacting support. Self-serve resource configuration is a “coming soon.” If you’re modeling on a memory-bound workload, this matters.
🟡 The Cloud Agents API rate limit isn’t published numerically — only “standard rate limiting.” Add exponential backoff on 429s and don’t burn through the GET /v1/repositories quota (1/min, 30/hr).
Two shifts: collapsed contexts and durable agent IDs
Two product shifts come out the other side of this.
The first is that the CLI / IDE / cloud / SDK distinction has collapsed for tooling vendors. A formatter, secret scanner, MCP governance layer, dependency-security gate, or test-injection hook now ships as a single artifact (file-based hooks plus an optional MCP server) and runs in all four contexts identically. The agent acp JSON-RPC mode (the hidden ACP server Cursor’s CLI exposes for JetBrains, Neovim, Zed) closes the loop for editor integrations that aren’t the Cursor desktop app. The hooks documentation lists ten partner integrations already shipped in this shape. Expect that list to triple.
The second is that agent runs are now durable, addressable, scriptable infrastructure. A bc-… agent ID is a real identifier you can hand to a coworker, write to a database, attach to a Linear ticket, link from a Slack message. The SDK is the wrapper, but the shape (durable agents + per-prompt runs + SSE streams + structured errors + 15-minute presigned artifact URLs) is the genuinely new piece. Think of it the way you’d think of Stripe’s Customer object: an identifier you build your business logic around, not a request you fire and forget.
What hasn’t changed: the safety story. The harness is the same harness that wrote nine seconds of damage into a real production database in late April. The SDK gives you a much cleaner way to express that harness in code. It does not give you a different harness. If you build something this weekend, build the hooks first. Block-list the destructive commands. Scope the credentials. Default the sandbox. Treat the agent’s plan as input to your gate, not the gate itself.
Then ship.