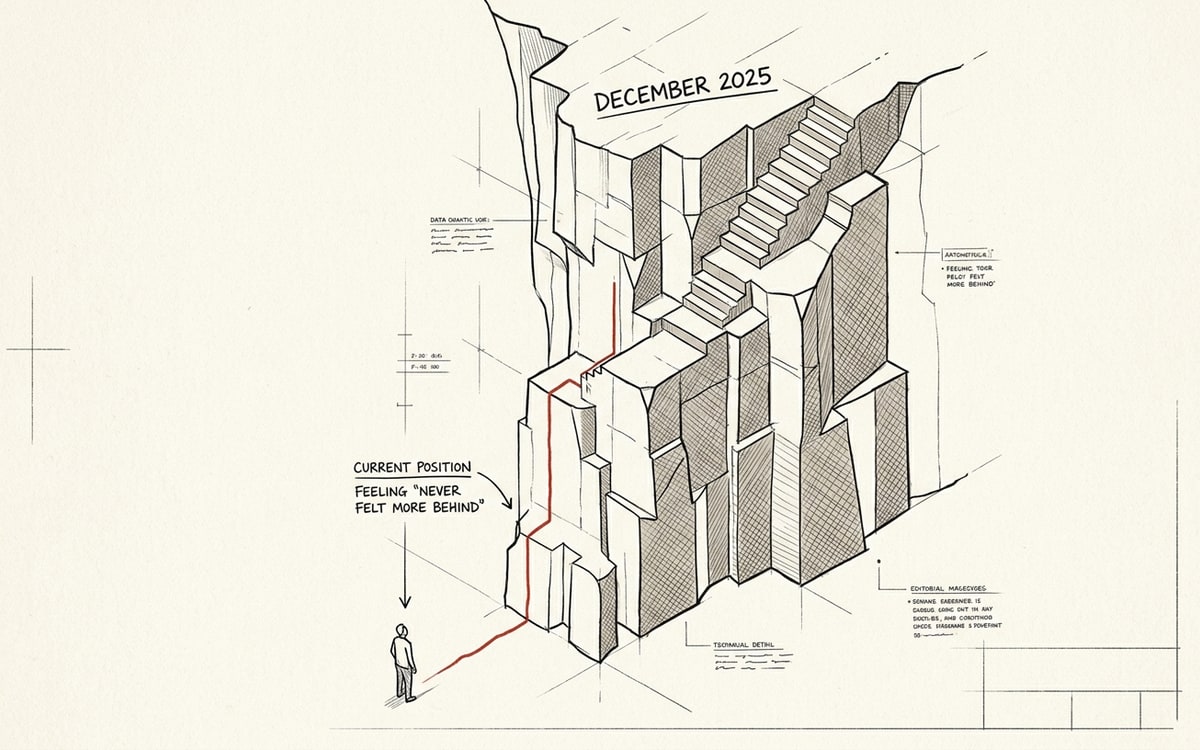
“I have never felt more behind as a programmer”
The framing line of Andrej Karpathy’s opening conversation at Sequoia’s AI Ascent 2026, across the table from partner Stephanie Zhan in the same Sequoia office where he co-founded OpenAI, was that he, the person who coined “vibe coding,” now feels behind. “A lot has changed,” Zhan posted afterward. “Last year, he coined vibe coding. This year, he’s never felt more behind as a programmer.”
The reason isn’t that he forgot how to write code. It’s that the floor under everyone moved while he was on holiday. “I was on a break,” he said of December 2025. “I just started to notice that with the latest models, the chunks just came out fine. I kept asking for more and it just came out fine. I can’t remember the last time I corrected it.” Then he started pulling at the thread, and his side-projects folder filled up.
For an industry that has been compounding monthly releases for two years, the diagnosis is unusually specific: December 2025 was a phase change. Anyone whose mental model of LLM-assisted coding is calibrated to mid-2025 is, per Karpathy, working from priors that no longer apply. That’s the frame this entire post is sitting inside.
Software 1.0 → 2.0 → 3.0, restated
Karpathy has been refining the Software 1.0 / 2.0 / 3.0 framing for two years. He gave the canonical version at YC’s AI Startup School in June 2025, in a talk titled “Software Is Changing (Again)” that has 2.4 million views. The AI Ascent 2026 conversation is where he stress-tested it against working agents.
The taxonomy, side by side:
| Software 1.0 | Software 2.0 | Software 3.0 | |
|---|---|---|---|
| What humans write | Explicit code | Datasets + objectives | Prompts (context windows) |
| The “program” is | Source files | Trained weights | The text in the context window |
| Search method | Manual logic | Gradient descent | LLM inference |
| Most-predictive task feature | Specifiability (can you spec it?) | Verifiability (can you score it?) | Promptability (can you describe it?) |
| Canonical artifact | A .sh install script | A trained model checkpoint | A README block you paste into your agent |
| Where it runs | CPU on structured data | GPU on parameters | LLM on the digital information space |
Two examples broke Karpathy’s mental model and now serve as the canonical 3.0 worked examples.
Example 1 — the Open Code install. Installing a cross-platform CLI is normally a 1.0 problem: you write a shell script, and it balloons as it tries to handle every OS, every shell, every package manager. The actual install for Open Code is a different artifact: a block of text you copy and paste into your agent, which inspects your environment and figures out the install itself. “The agent has its own intelligence that it packages up and then it kind of like follows the instructions and it looks at your environment, your computer and it kind of like performs intelligent actions to make things work and it debugs things in the loop,” Karpathy said. The “install script” became a prompt.
Example 2 — Menu Gen. This is the most useful pedagogical artifact in the talk because Karpathy lived through both versions. In April 2025, he vibe-coded a small web app called MenuGen that lets you upload a restaurant-menu photo, OCRs the dish names, and uses an image generator to produce a picture of each dish. The app worked. He shipped it on Vercel. He wrote a detailed post-mortem about how most of the pain was wiring up DNS and Stripe rather than the actual code.
Then, on stage, he described the moment that made him realize the whole app shouldn’t exist:
“I saw the Software 3.0 version of this… literally just take your photo, give it to Gemini and say ‘use Nano Banana to overlay the things onto the menu.’ Nano Banana basically returned an image that is exactly the picture of the menu that I took, but it actually put into the pixels — it rendered the different things in the menu. And this blew my mind because actually all of my Menu Gen is spurious. It’s working in the old paradigm. That app shouldn’t exist.”
Nano Banana, Google DeepMind’s image-editing model launched mid-2025, collapses the entire app into one model call. The OCR loop, the image-gen loop, the layout, the deploy: none of it is needed. The model does the whole job.
The Menu Gen test — is my product a 1.0 wrapper around a 3.0 capability? — is the question every operator should be running over their roadmap.
The December 2025 phase change
Karpathy has been mapping the gradient continuously. His 2025 LLM Year in Review, published December 19, identified six paradigm shifts. The one most relevant to the Sequoia conversation is the first: Reinforcement Learning from Verifiable Rewards (RLVR) as a new dominant training stage. “At the start of 2025, the LLM production stack in all labs looked something like this: 1. Pretraining … 2. Supervised Finetuning,” he wrote. By year-end, RLVR had been bolted on as a third stage, and verifiable domains (math, code, puzzle-shaped tasks with checkable answers) were the ones moving fastest.
Coding agents got the most concentrated RLVR, and the December step-change Karpathy described on stage is the surface effect: large blocks of generated code that work the first time, the user trusting the system enough to stop reading every diff. He stressed this is not the same product anyone evaluated in mid-2025. “A lot of people experienced AI last year as ChatGPT-adjacent thing, but you really had to look again and you had to look as of December because things have changed fundamentally,” he said.
That re-evaluation imperative is the most actionable line in the talk. If your agentic-coding priors are six months old, they’re stale.
Vibe coding raised the floor; agentic engineering raises the ceiling
Karpathy coined “vibe coding” on February 2, 2025, in a tweet that has since made it into Wikipedia as a software-development practice and into Simon Willison’s commentary within four days. The original definition: “a new kind of coding … where you fully give in to the vibes, embrace exponentials, and forget that the code even exists.”
Fifteen months later, on the Sequoia stage, he refined the framing into a two-tier model:
| Vibe coding | Agentic engineering | |
|---|---|---|
| What it does | Raises the floor | Preserves the ceiling |
| Who it’s for | Hobbyists, designers, PMs, anyone | Professional engineering teams |
| Quality bar | Whatever the model gives you | Same as before — security, correctness, taste, architecture |
| Hand-off mode | Trust the agent end-to-end | Co-author detailed specs first |
| Output target | Side-projects, throwaways, demos | Production-grade software |
| Speed-up | ”Forget the code even exists” | Well above 10x (Karpathy’s stage estimate) |
| Failure mode | Floor moves; ceiling doesn’t | Silent invented architectures (see Menu Gen Stripe bug) |
The line that separates them, in Karpathy’s words:
“Agentic engineering is about preserving the quality bar of what existed before in professional software. So you’re not allowed to introduce vulnerabilities due to vibe coding. You are still responsible for your software just as before — but can you go faster?”
He went further on the magnitude: “People used to talk about the 10x engineer. I think this is magnified a lot more — 10x is not the speed-up you gain. It does seem to me like people who are very good at this peak a lot more than 10x.” He didn’t quantify the new multiple. The implication is that the ceiling on individual engineering throughput, with full agentic tooling and a real spec, is moving in a way that “10x engineer” no longer captures.
This is the talk’s clearest message to engineering leaders: vibe coding is the gateway drug; agentic engineering is the craft your team actually has to develop. The two require different playbooks, different specs, different review processes, and very different hiring loops.
Jagged intelligence — and why the car wash is the new strawberry
The 2024 example of LLM jaggedness was: how many R’s are in “strawberry”? The 2026 example, courtesy of Karpathy, is the car wash:
“The new one is: I want to go to a car wash to wash my car and it’s 50 meters away. Should I drive or should I walk? And state-of-the-art models today will tell you to walk because it’s so close. How is it possible that state-of-the-art Opus 4.7 will simultaneously refactor a 100,000-line codebase or find zero-day vulnerabilities and yet tells me to walk to this car wash? This is insane.”
The line is funny. The framework underneath it isn’t. In “Verifiability,” Karpathy laid out the explanation:
- Frontier labs train via massive RL environments with verifiable rewards — math problems, code that passes tests, puzzles with correct answers.
- Capability peaks in those verifiable circuits, sometimes “beyond the ability of top experts.”
- Capability lags in domains that are not easily verifiable: “creative, strategic, tasks that combine real-world knowledge, state, context and common sense.”
Onstage, he added a second axis: even within the verifiable space, the labs have to care. He cited the GPT-3.5 → GPT-4 chess jump as evidence: “A huge amount of data of chess made it into the pre-training set, and just because it’s in the data distribution, basically the model improved a lot more than it would just by default. So someone at OpenAI decided to add this data and now you have a capability that just peaked a lot more.” The model didn’t generally get better at chess; it got the chess data.
Stated as a one-liner: jaggedness ≈ verifiable × the lab cared.
That’s a 2×2 you can run any task through:
| Lab cared | Lab didn’t care | |
|---|---|---|
| Verifiable task | 🟢 Capability peaks (refactor 100k-line codebase, find 0-days, GPT-4 chess) | 🟡 Latent capability — fine-tune lever available to founders (the entire verifiability thesis) |
| Not verifiable task | 🟡 RLHF / judge-ensemble bolt-ons; capability is “OK” | 🔴 The car-wash zone — common-sense, taste, real-world state, embodied judgement |
The practical consequence is that there’s no manual telling you which quadrant any given prompt is in. “You have to actually explore this thing that they give you that has no manual,” Karpathy said. “And it works in certain settings but maybe not in some settings … If you’re in the circuits that were part of the RL, you fly. If you’re in the circuits that are out of the data distribution, you’re going to struggle.”
For builders, that turns capability-mapping into a workflow. You ship into your problem, you find the cliff, you decide whether to back off, route around it, or fine-tune your way through.
Verifiability is the founder’s master variable
The natural follow-up: if labs own the obvious verifiable domains, what’s left for founders?
Karpathy’s answer is that verifiability is the lever you can pull yourself. He drew a clean line in his November 2025 essay:
- Software 1.0 “easily automates what you can specify.”
- Software 2.0 “easily automates what you can verify.”
If you can construct an environment that is, in his words, “resettable, efficient, and rewardable,” you can RL it. The fine-tuning lever exists for everyone, not just frontier labs. “If you have huge amount of diverse data sets of RL environments, you can use your favorite fine-tuning framework and pull the lever and get something that actually works pretty well,” he said.
Onstage, Zhan tried to get him to name a domain. He demurred (“sorry, I don’t mean to vape post on the stage”), but the founder play is unambiguous from the structure of the argument:
| Step | Action | What you own | What the lab owns |
|---|---|---|---|
| 1 | Pick a domain with construct-able verifiers the labs won’t bother with | The domain | Base model capability |
| 2 | Build a diverse RL environment dataset | The environments | Pretraining corpus |
| 3 | Pull the fine-tune lever yourself | The fine-tuned weights | The fine-tuning framework |
| 4 | Compound the data flywheel | The verifier + the env + the data | A commoditized base model |
The takeaway in one line: the moat is the verifier and the environment, not the base model.
He went further: “I do think that ultimately almost everything can be made verifiable to some extent … even for things like writing or so on, you can imagine having a council of LLM judges and probably get something reasonable.” The frontier of “verifiable” is itself moving. What’s not RL-able today is becoming RL-able tomorrow as judge ensembles improve.
Ghosts, not animals
The other piece of furniture in Karpathy’s mental model, and one that traveled widely on its own, is the Animals vs Ghosts framing he published October 1, 2025, after Rich Sutton’s appearance on the Dwarkesh podcast.
Sutton, author of The Bitter Lesson, the canonical text in frontier-lab circles, argues for an architecture closer to a Turing-style “child machine”: no pretraining, learning from raw experience interacting with the world. LLMs break a lot of his principles. Karpathy’s response was not to defend LLMs as bitter-lesson-pilled, but to reframe what they are:
“Today’s frontier LLM research is not about building animals. It is about summoning ghosts. You can think of ghosts as a fundamentally different kind of point in the space of possible intelligences. They are muddled by humanity. Thoroughly engineered by it. They are these imperfect replicas, a kind of statistical distillation of humanity’s documents with some sprinkle on top.”
The follow-up essay, The space of minds, pushed harder: animal intelligence is one specific point in a vast space, shaped by evolutionary pressures (innate, continuous, embodied), and we shouldn’t be surprised that ghosts (statistical distillations of internet text plus RL-bolted appendages) are jagged in different ways.
On the Sequoia stage, Karpathy was honest about its operational value: “I’m not sure it actually has like real power. I think it’s a little bit of philosophizing.” But the mindset it produces is the deliverable. Don’t anthropomorphize. Don’t try to motivate the model. Don’t yell at it. Be suspicious of its outputs, especially in places where the data distribution thins out. The framing is a discipline, not a knob.
You’re a director now, not a typist
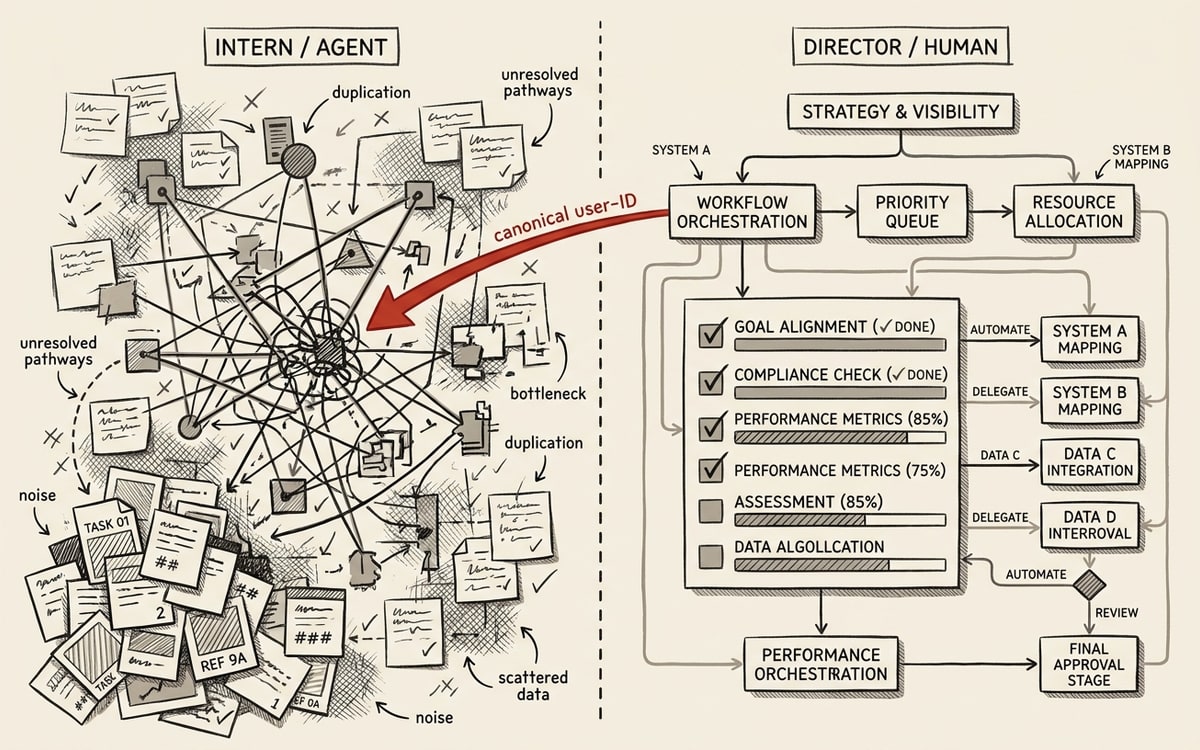
Karpathy’s working metaphor for agents is the intern — but a very specific kind. “The agents are kind of like these intern entities,” he said. “You still have to be in charge of the aesthetics, the judgment, the taste, and a little bit of oversight.”
He gave a real failure case from Menu Gen that should be required reading for anyone shipping agentic features. The app supports Google sign-in and Stripe payments. The agent, without being asked, invented an architecture where credits purchased via Stripe got attached to the user account by matching email addresses between Google and Stripe. A user’s Google email and their Stripe email can be different (Stripe’s email is whatever they typed at checkout). When they were, the funds detached from the user. There was no canonical user ID; the agent had silently introduced a foundational design bug that worked on the happy path and broke under any realistic divergence.
“Why would you use email addresses to try to cross-correlate the funds? They can be arbitrary. You can use different emails. Like this is such a weird thing to do.”
The lesson is not “agents make mistakes.” The lesson is that the mistake category is architectural: the spec didn’t say “every user has one canonical ID and everything ties to it,” so the agent invented a plausible-looking workaround. “I think people have to be in charge of this spec, this plan,” Karpathy said. He’s also lukewarm on plan mode as a substitute: “I would I mean obviously it’s very useful, but I think there’s something more general here where you have to work with your agent to design a spec that is very detailed.”
The hand-off pattern that emerges:
| Hand off to the agent | Keep on the human | |
|---|---|---|
| API trivia | ✓ — keep_dim vs keep_dims, dim vs axis, reshape vs permute vs transpose | |
| Boilerplate scaffolding | ✓ — install scripts, CRUD endpoints, fixtures, routine refactors | |
| Underlying mental model | ✓ — tensor views vs storage, what’s a copy vs an alias | |
| Architectural invariants | ✓ — canonical user IDs, security model, data-flow rules | |
| Aesthetic / taste | ✓ — Karpathy: agent-generated code is “bloaty… awkward abstractions… gross” | |
| Spec authorship | ✓ — write the detailed spec with the agent, before any code | |
| Choosing what’s worth building | ✓ — direction-setting, the Menu Gen test |
“I don’t remember this stuff anymore,” Karpathy said of the API-trivia column. “This is the kind of details that are handled by the intern.” But the right column is non-negotiable: “You still have to know there’s an underlying tensor, there’s an underlying view, and then you can manipulate the view of the same storage.”
The honest part is that taste is currently broken in the agent. Karpathy admitted that when he reads agent-generated code, “sometimes I get a little bit of a heart attack because it’s not like super amazing code necessarily all the time and it’s very bloaty and there’s a lot of copy paste and there’s awkward abstractions that are brittle and like it works but it’s just really gross.” He pointed to his attempts to get models to simplify his nanoGPT-style training code — they couldn’t. “You feel like you’re outside of the RL circuits … it’s not like light speed.” Aesthetic compression isn’t in the reward.
Hiring also has to change to match. Karpathy proposed a new interview loop:
“Give me a really big project and see someone implement that big project. Like let’s write, say, a Twitter clone for agents, and then make it really good, make it really secure, and then have some agents simulate some activity on this Twitter, and then I’m going to use 10 Codexes 5.4x for X-high to try to break your website that you deployed and they’re going to try to basically break it and they should not be able to break it.”
That’s the new agentic-engineering interview. Big project, hardened, agent red-team. Leetcode is the 1.0-paradigm artifact.
Agent-native infra is the platform shift
Karpathy’s pet peeve for the entire talk was that the world is still written for humans:
“Everything is still fundamentally written for humans and has to be moved around. They still have docs that are fundamentally written for humans. This is my favorite pet peeve. Like I don’t … why are people still telling me what to do? Like I don’t want to do anything. What is the thing I should copy paste to my agent?”
The Open Code install (“paste this text into your agent”) is, in this frame, not a clever README trick — it’s an early example of an emerging primitive: the agent-payload README. Whoever rewrites SDKs, install flows, dashboards, deploys, and DNS configuration around “what’s the prompt I hand my agent?” wins the next layer.
His own benchmark for “agent-native enough”:
“I would hope that — Menu Gen — I could give a prompt to an LLM, build Menu Gen, and then I didn’t have to touch anything and it’s deployed in that same way on the internet.”
The post-mortem of the original Menu Gen showed how far that goal is from reality today: he spent more time wiring DNS and Stripe through dashboards than writing the application. Closing that gap (agent-first sensors, actuators, and data structures, with no clicking through human-facing menus) is the founder thesis.
This is consistent with the larger Sequoia AI Ascent 2026 thesis: partners Pat Grady, Sonya Huang, and Konstantine Buhler framed long-horizon AI agents as a $10 trillion opportunity. The agent-native infra layer is where that capital has to land before agents can compound. Karpathy is naming the gap; whoever fills it owns a platform.
”You can outsource thinking. You cannot outsource understanding.”
The talk closed on education, which is Karpathy’s other day job. He founded Eureka Labs in July 2024 explicitly to build AI-native education — “we are building a new kind of school that is AI native.” Zhan asked what’s still worth learning deeply when intelligence is cheap.
His answer was a tweet he keeps re-reading:
“You can outsource your thinking, but you can’t outsource your understanding.”
He elaborated on what that means in practice. Even with full agentic tooling, “I’m still part of the system. Information still has to make it into my brain. I feel like I’m becoming a bottleneck of just even knowing what are we trying to build, why is it worth doing, how do I direct my agents.” Direction-setting requires understanding, and understanding still has to live in a human.
His personal stack for keeping that bottleneck open is his LLM Wiki, an idea-file approach he published as a public gist on April 4, 2026. Every article he reads gets piped into a personal knowledge base. He then queries it for new projections — synthetic-data generation over his own corpus. “Anytime I see a different projection onto information, I always feel like I gain insight,” he said. “Tools to that effect, I think, are incredibly interesting and exciting.”
The implication for individual operators is the cleanest takeaway in the entire talk: the bottleneck of the next decade isn’t typing speed; it’s understanding well enough to direct. A personal LLM knowledge base is a defensive moat against being out-thought by people running better-instrumented brains.
Karpathy’s argument, end to end
Karpathy has been the most internally consistent narrator of the LLM era. Read end-to-end, his last fifteen months are one continuous argument, not a sequence of takes:
| Date | Artifact | Core idea it added |
|---|---|---|
| Feb 2, 2025 | Vibe coding tweet | Coined the term — “give in to the vibes, forget the code exists” |
| Apr 27, 2025 | Vibe coding MenuGen post-mortem | What breaks when a 1.0-shaped app meets a 3.0 world (DNS + Stripe friction) |
| Jun 17, 2025 | Software Is Changing (Again) — YC talk | The 1.0 / 2.0 / 3.0 framing, canonized |
| Oct 1, 2025 | Animals vs Ghosts | LLMs are not animals; they’re statistical ghosts of human text |
| Nov 17, 2025 | Verifiability | The master variable: 1.0 = specifiable, 2.0 = verifiable |
| Nov 29, 2025 | The Space of Minds | Animal intelligence is one point in a much bigger space |
| Dec 19, 2025 | 2025 LLM Year in Review | Six paradigm shifts; December = the phase change |
| Apr 4, 2026 | LLM Wiki gist | Personal knowledge base as the human moat |
| Apr 30, 2026 | AI Ascent 2026 conversation | The argument lands as operating advice for builders |
Karpathy posted his own three-theme recap of the Sequoia conversation hours after it went up, and the structure of that recap is the same structure of the talk: paradigm-defining examples, jaggedness, agent-native economy.
Fireside chat at Sequoia Ascent 2026 from a ~week ago. Some highlights:
The first theme I tried to push on is that LLMs are about a lot more than just speeding up what existed before (e.g. coding). Three examples of new horizons:
The second (ongoing) theme is trying to explain the pattern of jaggedness in LLMs … You’re either in the data distribution (on the rails of the RL circuits) and flying or you’re off-roading in the jungle with a machete, in relative terms.
Last theme is the agent-native economy. The decomposition of products and services into sensors, actuators and logic … how we can make information maximally legible to LLMs, some words on the quickly emerging agentic engineering and its skill set.
— @karpathy April 30, 2026
The Sequoia stage is where each of those threads pays off as a single playbook.
The advice, compressed:
- Re-evaluate your AI tooling priors as of now. Mid-2025 calibration is stale.
- Run the Menu Gen test on your roadmap. Which of your apps are 1.0 wrappers around 3.0 capabilities? Either pivot to the 3.0-native version or own a layer the model can’t.
- Treat agentic engineering as a discipline, not a vibe. Co-author detailed specs with the agent before any code. Define canonical IDs, security invariants, architectural rules explicitly — agents will silently invent the wrong ones if you don’t.
- Build a personal knowledge base. Pipe every meaningful artifact you read into it. Query for new projections. This is the human moat.
- Refactor hiring away from puzzles toward big-project + agent-red-team simulations. The 10x engineer multiple no longer captures what the top end of the distribution does.
- Pick a verifiable domain the labs won’t prioritize. Build the RL environments. Pull the fine-tune lever yourself. Verifier + environment is the moat.
- Write your docs, install flows, and SDKs for agents first. The “copy-paste this to your agent” install is the new README. Whoever ships the agent-native infra layer wins the next platform shift.
- Stay suspicious. Don’t anthropomorphize ghosts. Don’t expect aesthetic taste from a model that wasn’t rewarded for it.
The car wash is funny because it’s a 50-meter problem inside a model that just refactored 100,000 lines of code. That gap is where every operator working with agents lives now. Karpathy’s framing is the most useful map of that terrain published in the last twelve months.