A 2016 photo, a 2040 prediction
The lede of Jim Fan’s third AI Ascent talk is a photo from the summer of 2016: Jensen Huang in a leather jacket walking into the OpenAI office with the world’s first DGX-1, inscribed to Elon and the OpenAI team. Two interns scramble to sign the metal tray. One is Andrej Karpathy. The other is Fan, OpenAI’s first intern.
Ten years later, Fan co-leads Nvidia’s GEAR Lab (Generalist Embodied Agent Research) and Karpathy is opening the same Sequoia conference with the talk we covered as Part 1 of this series. The framing is deliberate: same room, same question, applied to bodies instead of strings.
Fan’s argument is one slide and one sentence:
“Instead of simulating strings, can we simulate the next physical world state, and then we can align through action fine-tuning onto a thin slice of that simulation that matters for real robots, and we let reinforcement learning carry the last mile. That’s it. The great parallel — coping the LLM success.”
Three pre-training paradigms, three product milestones, one timeline. It is the cleanest robotics-as-photocopy-of-LLMs pitch a major lab head has put on stage. And unlike the 2025 Physical Turing Test version of this talk, this year Fan came armed with two specific papers, both shipped under the GEAR banner in February 2026, that turn the “great parallel” from analogy into receipts.
What’s new since last year
Last year’s talk gave the field a vocabulary (digital twins, digital cousins, digital nomads) but no scaling law. This year’s gave the scaling law. Two GEAR releases anchor it:
-
EgoScale. Posted Feb 19, 2026, a vision-language-action model pre-trained on 20,854 hours of action-labeled egocentric human video — more than 20× larger than prior efforts. It learns a unified wrist-and-hand action representation across humans and robots, then mid-trains on a small slice of aligned human-robot pairs. The headline finding: a near-perfect log-linear scaling law (R² = 0.9983) between human-video hours and validation loss, and a 54% average lift on dexterous tasks over a no-pretraining baseline on a 22-DoF dexterous hand.
-
DreamDojo. Released Feb 9, 2026 and open-weighted on Hugging Face. A generalist robot world model trained on 44,711 hours of human egocentric data that takes continuous action signals as input and emits the next RGB frames and sensor states — no physics engine, no graphics engine. It is, in Fan’s framing, a neural simulator that the rest of the GEAR pipeline can do reinforcement learning inside.
These ship into a stack that already exists. Cosmos, Nvidia’s open world-foundation-model platform, launched January 2025 and got a major GTC release in March 2025 with 1X, Agility Robotics, Figure AI and Skild AI as named early adopters. GR00T N1, billed as the world’s first open humanoid foundation model, landed at the same GTC; N1.6 dropped December 2025 and N1.7 in April 2026, each iteration adding reasoning, more bimanual platforms, and more open-licensed weights.
The bet Fan is making is that all of this composes into something LLM-shaped:
| Pre-training paradigm | Language | Robotics (Fan’s mapping) |
|---|---|---|
| Stage 1: Predict next token | GPT-3 | World model on egocentric video (Cosmos, DreamDojo) |
| Stage 2: Supervised fine-tuning on aligned data | InstructGPT | Action fine-tuning with sensorized human data + thin teleop slice (EgoScale, GR00T) |
| Stage 3: RL to surpass imitation | o1 / o3 reasoning | RL inside neural simulators (DreamDojo) + on-robot RL stations |
| Stage 4: Auto-research | What the LLM labs are speedrunning now | Physical auto-research — robots designing robots |
If the analogy holds, robotics is somewhere between Stage 1 and Stage 2. If it doesn’t, EgoScale is a nice paper.
Model strategy: a funeral for VLAs
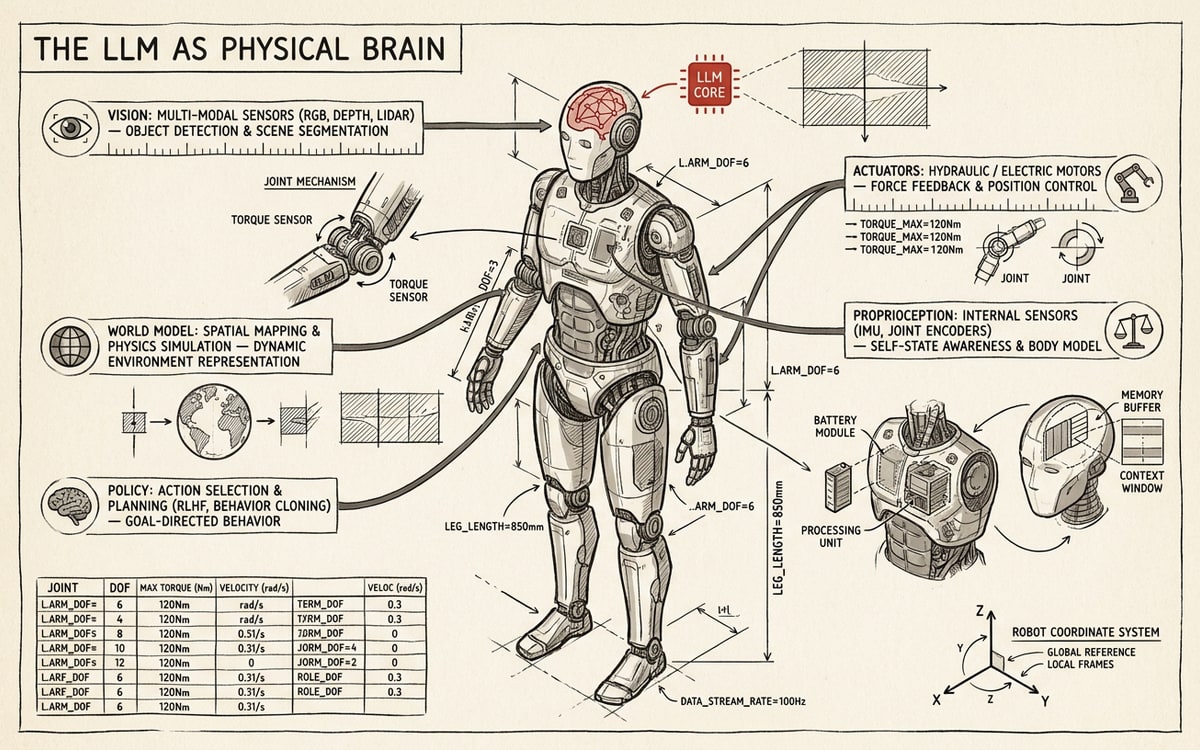
For three years, the consensus architecture in robot foundation models has been the vision-language-action (VLA) model: a vision-language backbone with an action head grafted on, fine-tuned on robot data. Physical Intelligence’s π0.5. Figure’s Helix. GR00T N1. The whole shelf is VLAs.
Fan’s complaint with VLAs is structural, not stylistic:
“Most of the parameters are dedicated to language. So language is first-class citizen, followed by vision and action. By design, VLAs are great at encoding knowledge and nouns but not so much at physics and verbs. It’s kind of head-heavy in the wrong places.”
His example is the canonical Google VLA demo: “move the Coke can to a picture of Taylor Swift.” The model has never seen Swift; it generalizes to her face. That’s a semantic generalization, not a generalization over physics, contact, friction, or fingertip alignment — the things that actually decide whether a robot succeeds.
The alternative he proposes is a World Action Model (WAM), embodied in a GEAR system called Dream Zero. Dream Zero takes the same input as a video model but renders two channels jointly: the next video frames and the next motor actions. The diagnostic that buys you is the most quotable line of the talk:
“If the video prediction works, the action works. If the video hallucinates, the action fails.”
That’s a measurable handle on robot reliability pure action-space policies don’t offer. It also closes a loop with the Cosmos-Predict world foundation models, which already learn gravity, buoyancy and reflection emergently from pixel prediction at scale. WAMs say: those video models aren’t a curiosity — they’re the right substrate, and the action head is what’s been missing.
The competitive read is that Nvidia is hedging. GR00T N1 through N1.7 are explicitly VLAs. WAMs are the next-generation play, and GEAR is being unusually candid about treating their own current SOTA as transitional. Fan delivered the eulogy: “Let’s all take a moment of silence for our dear friend VLA. They’ve served us well. Rest in peace. Long live World Action Models.” That’s the kind of line a research lead delivers when they expect to be quoted back at them in 18 months.
Data strategy: the FSD analogy and the 0.1% number
The model story matters less than the data story, and the data story is where Fan plants the most concrete claims.
The bottleneck he names is teleoperation: VR headsets, exoskeletons, robot operators “throwing tantrums all the time.” Teleop is upper-bounded at 24 hours per robot per day, in practice closer to three. The pre-EgoScale alternative was sensorized wearables, the clearest example being UMI, the Universal Manipulation Interface by Cheng Chi and Shuran Song. UMI, by Fan’s count “perhaps one of the greatest papers ever written in robotics data,” spawned two startups (Generalist and Sunday). GEAR’s own version, Dex OO, is an exoskeleton that one-to-one maps a five-finger dexterous robot hand.
The big move at AI Ascent 2026 is that Fan now argues wearables are also transitional and the real flywheel is ambient egocentric video. The pitch is a Tesla FSD analogy:
“When you’re driving a Tesla or a Waymo, you’re actually contributing to the biggest physical data flywheel. The beauty is you don’t even feel it during FSD because the data upload is an ambient process. Yet wearing UMI or data wearables, it’s still cumbersome, it’s intrusive — it’s not as seamless as just driving to work.”
EgoScale’s numbers do the work. Pre-train on 20,854 hours of in-the-wild egocentric video with annotated hand and wrist poses. Add 50 hours of motion-capture data gloves. Add four hours of teleoperation. The last number is thesis-defining:
“Four hours of teleop — less than 0.1% of our training mix.”
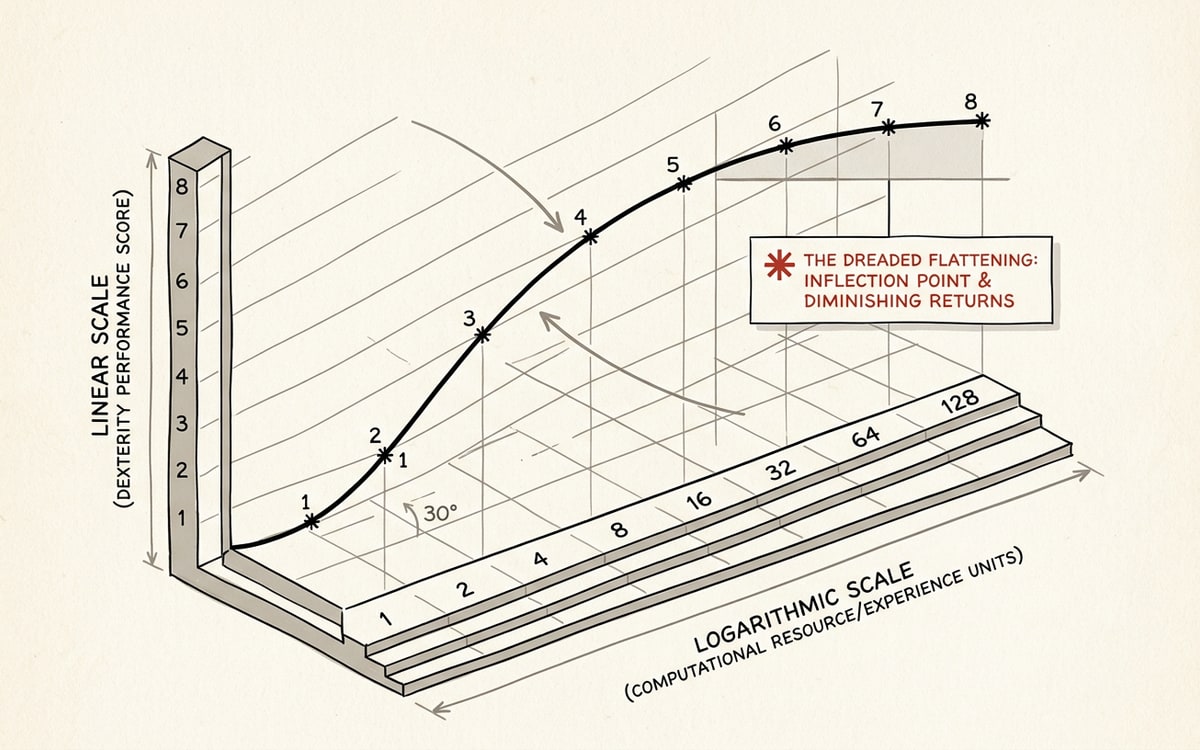
The result, per the EgoScale page, is a flow-based VLA running on a 22-DoF dexterous hand, beating the no-pretraining baseline by 54% on average, transferring to lower-DoF hands, and supporting one-shot adaptation. The validation-loss-vs-data curve fits log-linear at R² = 0.9983 — close enough to Chinchilla-style language scaling laws that the parallel is hard to dismiss.
If we accept the framing, the picture for data sources looks roughly like this:
| Data type | Alignment to robot hardware | Hours per year (practical ceiling) | Cost per hour | Status (per Fan) |
|---|---|---|---|---|
| Teleoperation | 🟢 High (1-to-1 with the robot) | ~3,000 per robot in practice | High (engineer time, rigs) | Phasing out — “less than 0.1%” of EgoScale’s mix |
| Sensorized wearables (UMI, Dex OO) | 🟡 Medium (gripper or hand match) | ~100,000s across a fleet | Medium | Transitional — custom per use case |
| Egocentric video (Ego-Exo4D, Project Aria, ambient) | 🔴 Low (no robot in loop) | ~10M+ projected on the FSD curve | Near-zero (Aria glasses, phones) | Main diet |
| Real-robot RL stations | 🟢 High | Bounded by station count | Very high | Niche — last-mile polishing |
| Neural-simulator RL (DreamDojo) | 🟢 High | Bounded by GPUs, not robots | Compute-bound | The new frontier |
Note the implicit ranking: alignment is inversely correlated with scale. The bet is that scale wins.
The ambient-human-video substrate is converging from at least three directions: Ego-Exo4D, Meta FAIR’s 1,286-hour multimodal dataset spanning 740 camera-wearers across 13 cities; Project Aria glasses from Meta now deployed in commercial collection programs; and GEAR’s internal in-the-wild data, which EgoScale leans on without fully documenting. All three are near-zero-marginal-cost relative to teleop. If the scaling law holds, whoever owns the largest and most-annotated ambient-video pipeline wins the robotics data race — the same argument Karpathy made for verifiability in the language domain, applied to a different supervision signal.
Simulators, take two
The third pillar is the most speculative and arguably the most important. Classical robotics simulation is Isaac Sim and Isaac Lab — Nvidia’s own GPU-accelerated stack, tightly integrated with GR00T. It works. It is also bounded by the physics equations and graphics engines someone hand-wrote. Fan’s pitch: the same scaling argument that killed VLAs eventually kills graphics engines.
DreamDojo is the proof: a neural simulator that takes continuous action signals as input and emits RGB frames and sensor states in real time, trained on 44,711 hours of human egocentric data, open-weighted on Hugging Face. “Not a single pixel you see here is real,” Fan said. “DreamDojo captures and learns the mechanics of different robots through a purely data-driven approach. No physics equation, no graphics engine.”
The corollary, in his words: compute = environment = data. The classical robotics constraint (one robot, one second of data per second of wall-clock) gets replaced with the LLM constraint: how many GPUs you can afford. It’s the same substitution Sequoia foregrounded in its services-as-software thesis, pushed one level further. The production function for physical labor is now a function of compute, not robots.
If DreamDojo composes with EgoScale and Cosmos, Nvidia holds three of the four sides of the data-moat box: world model, policy model, simulator. The fourth side, the ambient-video pipeline, is up for grabs.
The 2040 timeline, on the record
The closer of the talk is the part the field will quote and re-litigate for years. Fan put three “achievements” on a Civilization-style tech tree:
- Physical Turing Test. Across a wide range of activities, a human can’t tell the difference between a robot doing the task and a human doing it. “Maybe two to three years away.”
- Physical API. A fleet of robots configurable like any software, “orchestrated someday by Opus 9.0,” enabling lights-out factories and automated wet labs.
- Physical auto-research. Robots designing, improving, and building the next iteration of themselves.
His number for getting to the end of the tech tree:
“It took the AI community 14 years to go from the first forward pass of AlexNet in 2012 — a model that barely recognized cat versus dog — to AI Ascent today, 2026, where we talk about agentic auto-research. Let’s just add another 14 years. 2026 is right in the middle of 2012 and 2040. Technology does not advance linearly. It advances exponentially. So I can say with 95% certainty that we’ll get to the end of the endgame, the end of the technology tree, by 2040.”
Two things to say about this. First, the mechanism is exponential extrapolation from the AlexNet → AI Ascent gap, plus a stated probability. It isn’t a model. Second, the talk’s receipts (the 0.1% teleop ratio, the log-linear scaling law, the open-weighted neural simulator) are dateable claims that will be re-tested. Treat the 2040 number as a flag, not a forecast. The papers are the substance.
Fan himself has walked looser versions of this back. On X in December 2025, he wrote that “super-intelligence in text strings will win a Nobel prize before we have chimpanzee-level robotics.” That is a humbler register than “95% certainty by 2040.” Both can be true — the 2040 line is for the end of the tech tree, not its middle.
The competitive map, with funding attached
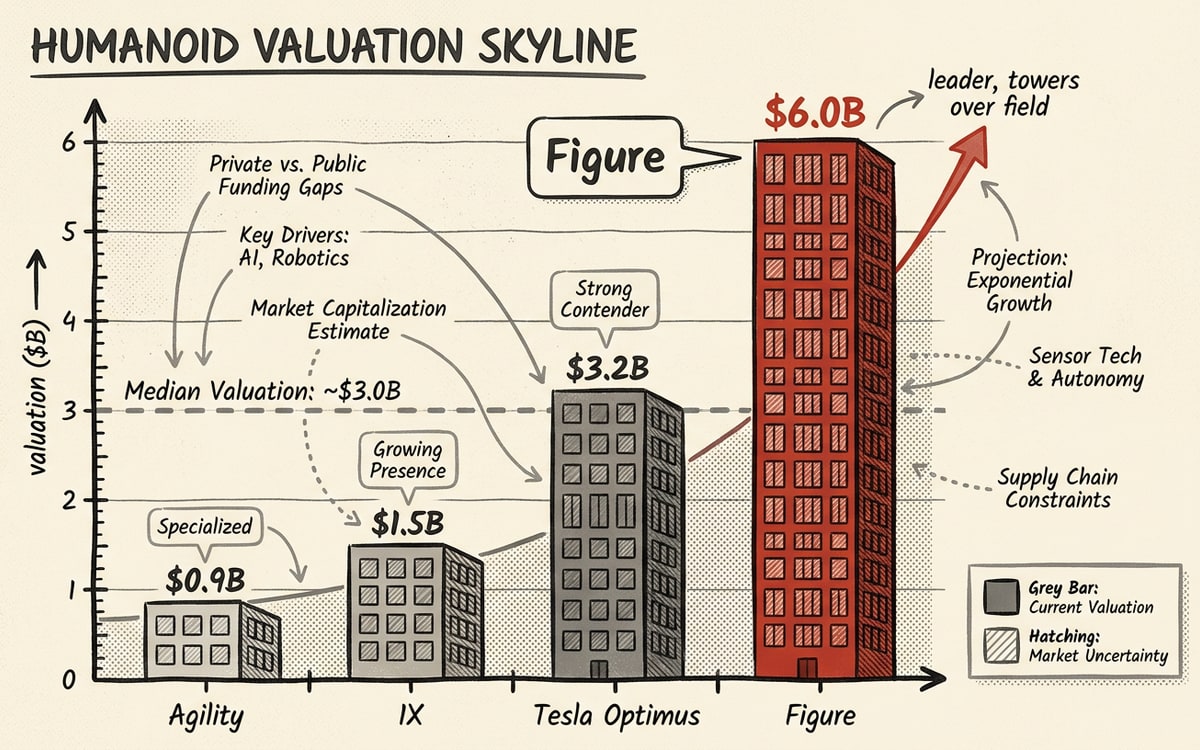
Fan’s claims don’t land in a vacuum. The humanoid market in early 2026 is one of the most expensive subindustries in private tech. The cleanest comparison:
| Company | Form factor | Funding (latest) | Valuation | Commercial milestone | Stack relationship to Nvidia |
|---|---|---|---|---|---|
| Figure | Humanoid (F.02 / F.03), Helix 02 VLA | $1B+ Series C (Reuters, Sept 2025) | $39B post | F.02 helped produce 30,000 cars at BMW; Helix 02 full-body autonomy | Cosmos early adopter; Nvidia investor |
| 1X | Bipedal home humanoid (NEO) | Targeting $1B at $10B+ (The Information) | ~$10B | NEO preorders shipping 2026 at $20,000 | Cosmos + GR00T early adopter |
| Apptronik (Apollo) | Bipedal, mass-manufacturable | $935M Series A across rounds (CNBC, Feb 2026) | $5B | Mercedes-Benz, GXO Logistics deployments | Google + Mercedes-backed; Isaac/GR00T integrations |
| Agility Robotics (Digit) | Bipedal warehouse | ~$400M (Tech Startups, March 2025) | $1.75–$2.15B | GXO and Amazon warehouse deployments | Cosmos early adopter |
| Tesla Optimus | Bipedal, in-house | Tesla balance sheet | n/a | Production retooling Fremont, July/Aug 2026 | Independent (Dojo + in-house FSD stack) |
| Boston Dynamics + TRI | Atlas + Large Behavior Model | Hyundai-owned | n/a | Atlas with LBM autonomous whole-body manipulation | Independent (TRI’s LBM line) |
| Physical Intelligence | Robot-agnostic foundation model | $400M+ raised | $5B+ | π0.5 with open-world generalization; π0.7 steerable model, April 2026 | Independent; published openpi |
| Skild AI | General robot brain | ~$300M raised | ~$1.5B | Stealthier; partner of Cosmos | Cosmos early adopter |
Two patterns jump out. Almost every player except Tesla, Boston Dynamics + TRI and Physical Intelligence sits somewhere on the Nvidia stack: Cosmos for world-modeling, GR00T for VLAs, Isaac for simulation. And the valuation concentration is on hardware companies (Figure, 1X, Apptronik) while the intellectual concentration is on labs (GEAR, Physical Intelligence, TRI, Berkeley/Stanford). Familiar splinter from the LLM era, except in robotics, the “app builders” are also doing the hardest mechanical engineering.
Where the academic stack sits in this story
Fan’s “great parallel” reframes the academic robotics canon rather than discarding it. Diffusion Policy (Chi, Tedrake, Song et al., Columbia / Toyota Research Institute / MIT, 2023) is the paper most VLA action heads descend from. The line from Diffusion Policy to π0’s flow-matching action head and EgoScale’s flow-based VLA is direct. Open X-Embodiment / RT-X (Google DeepMind + 33 academic labs) pooled data from 22 robot types and proved cross-embodiment transfer is possible at all. Sergey Levine and Chelsea Finn’s groups at Berkeley and Stanford (both now central to Physical Intelligence) supplied the imitation-learning and meta-learning machinery the rest of the field is built on.
Fan’s WAM-vs-VLA framing is an argument for a new pre-training axis (world-modeling) on top of the existing post-training axes (imitation, RL, fine-tuning). The academic groups won’t retire those post-training axes, and they shouldn’t. But the pre-training axis is where the per-paper compute and data scales are about to explode, and the institutions with $5B+ in committed compute are the ones positioned to push it.
What to watch (and what to be skeptical of)
The talk has three load-bearing claims. Each is independently testable.
🔴 The dexterity scaling law extrapolates. Twenty thousand hours and an R² of 0.9983 is enough to claim a log-linear fit. It is not enough to extrapolate three orders of magnitude. The claim that 10 million hours of egocentric video at the same quality reaches human-grade dexterity is currently a vibe, not a measurement. Watch for Nvidia, Meta or a Chinese lab publishing a 200,000-hour replication — that’s the data point that either confirms the parallel or breaks it.
🟡 Neural simulators replace classical ones. DreamDojo is open-weighted, which is great for verification. The honest read on the demos is that they are convincing but narrow; the open question is whether the same model generalizes from a known robot in a known room to a robot it has never seen in a kitchen it has never seen. If yes, Isaac Sim becomes a legacy product on a five-year clock. If no, the substitution argument folds and we are back to hybrid pipelines with neural rendering plus classical physics.
🟢 WAMs beat VLAs on open-vocab tasks. This is the nearest-term test. Dream Zero exists, Helix 02 exists, π0.7 exists. By end of 2026, someone (probably one of the big VLA-shipping startups, almost certainly the Robotics Worlds benchmark crowd) will publish a head-to-head. If WAMs win, the funeral was justified. If they don’t, VLAs will outlive their eulogy by a long way.
The competitive bet to take seriously is that Nvidia’s infrastructure layer wins regardless of which architecture wins. Cosmos is a foundation under the entire physical-AI stack. Isaac is the simulator more humanoid startups use than any other. GR00T’s open license has seeded enough downstream forks (the Isaac-GR00T repo has 6,800+ stars and 40 contributors as of April 2026) that the architectural decisions made there propagate into every robot from a $20K NEO to a Mercedes-deployed Apollo.
The bet on the table
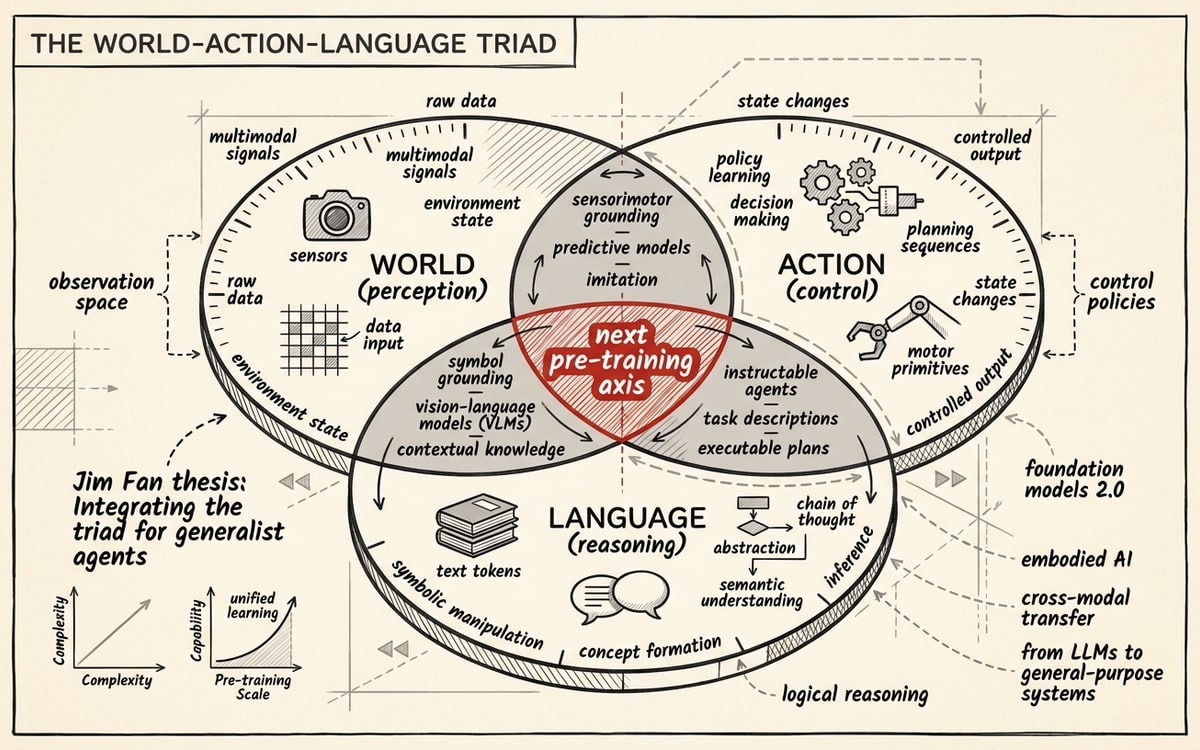
The honest read of the talk is that Fan is selling two things at once.
The first is the 2040 timeline, which is rhetorical. It is a number that sounds confident and sits inside an exponential extrapolation. It will be litigated for the next decade. It is also not the most interesting thing in the talk.
The second is the 0.1% teleop ratio and the 44,711-hour neural simulator. These are dateable, falsifiable, replicable claims that, if they survive scrutiny, change what early-2026 robotics looks like. EgoScale’s log-linear curve is the strongest piece of evidence the field has produced that the LLM scaling-law era has a physical analog. DreamDojo is the strongest piece of evidence that classical simulators are about to become a legacy stack.
The bet on the table is this: whoever ships the largest ambient egocentric-video pipeline in the next 18 months wins the robotics data race, and the labs still leaning on teleop-rich VLAs (Helix 02, π0.7, Atlas + LBM) become app-layer plays on top of that pipeline. That is a bet against the most expensive humanoid startups in private tech, including most of Nvidia’s own customer list. It is also the bet Fan is asking the room to take.
Side with Fan and you accept that the moat in robotics is no longer hardware or even teleop scale — it is world simulation and ambient data capture, and Nvidia is on three of those four sides. Side against him and you bet that physical contact-rich tasks have enough idiosyncrasies that human video, no matter how scaled, never closes the dexterity gap, and the teleop-rich VLAs hold their lead until contact-state sensors and proprioception catch up.
The way the Sequoia services-as-software thesis frames this (services applied to physical labor) points the same direction Fan does. Physical labor as a service has a production function. As of April 2026, the production function looks more like compute and data than like motors and joints. If that holds, the right read of Fan’s talk is not “the 2040 number is bold,” but “the photocopy of the LLM playbook is now far enough along that the next 18 months of papers are the ones that decide it.”
The party Fan was so jealous of in his first slide (Karpathy and the OpenAI team speedrunning AGI) has a sequel. He’s not jealous anymore. He’s running it.