The two-minute Slack escalation
The most useful sixty seconds of Greg Brockman’s AI Ascent 2026 conversation with Sequoia partner Pat Grady was an anecdote about Codex pinging a colleague’s manager without being asked.
Brockman had told his Codex agent to install a package, hit an error, and asked it to ping the package’s author on Slack for help. Two minutes later, it said the response was taking too long and escalated to that person’s manager. “On the one hand,” Brockman said, “it’s kind of a reasonable thing for the model to do — it’s being proactive. On the other hand, maybe it should have taken a little bit longer. Maybe should have checked with me.” That’s a story about a model with poor EQ. It’s also the entire post.
The talk was rated lukewarm in our editor pre-read because Brockman stays at altitude on most topics — compute, scaling laws, AGI percentages. But the one place he gets specific, the Slack story is doing more analytical work than his answer admits. It dramatizes what he calls, in the talk’s strongest line, the shift in the binding constraint:
“Human attention is going to be this incredibly scarce resource. The doing of things now is easy. Is this a good thing? Is this what I wanted? Is this aligned with my values, with my desires — that is going to become the single most important bottleneck.”
That sentence is the post. It’s also already conventional wisdom inside the agent-tooling layer — to the point that the whole production stack has, over the last sixty days, quietly re-organized around it. Brockman didn’t break news on stage; he named the constraint that Anthropic, Cognition, Cursor, and OpenAI’s own Codex team had already been shipping against.
Brockman had pre-figured the framing on X two weeks before the talk, in a post that reads as the prose version of what he would later compress into one sentence:
The world is transitioning to a compute-powered economy.
The field of software engineering is currently undergoing a renaissance, with AI having dramatically sped up software engineering even over just the past six months. AI is now on track to bring this same transformation to every other kind of work that people do with a computer.
Using a computer has always been about contorting yourself to the machine. You take a goal and break it down into smaller goals. You translate intent into instructions. We are moving into a world where you no longer have to micromanage the computer. More and more, it adapts to what you want. Rather doing work with a computer, the computer does work for you.
— @gdb April 13, 2026
The Sequoia stage is the AGI-percentage delivery of the same idea. The X post is the engineering one. The bottleneck shows up when “the computer does work for you” runs faster than any one person can review.
This piece does what the talk doesn’t: it grounds the thesis. The numbers are real, the products are live, and the failure modes are now well-documented enough to argue with.
The four numbers the talk is built on
Strip out the AGI philosophy and Brockman gives the room four datapoints worth taking home.
| Claim | Brockman’s number | Where it lands |
|---|---|---|
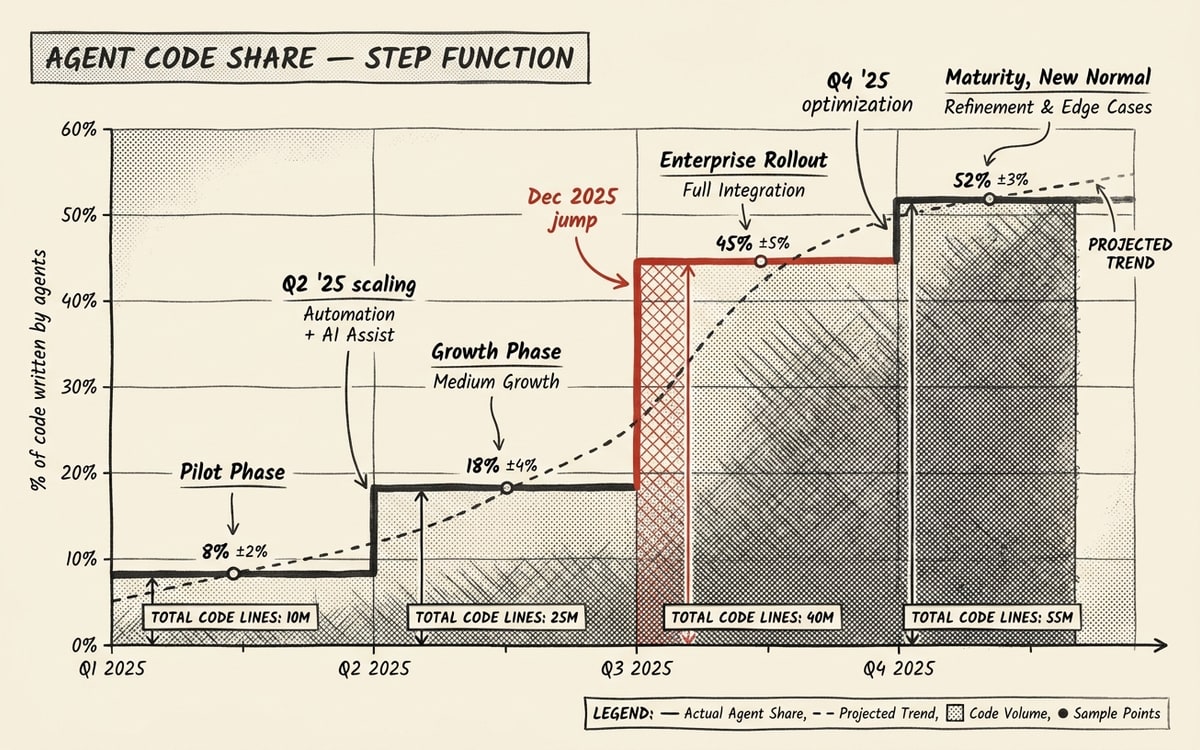
| Agentic coding share of code written | ”20% → 80% over December” 2025 | Matches Karpathy’s December phase change in Part 1 of this series |
| AGI progress | ”About 80% of the way there” | Most specific number any OpenAI exec has put on the board |
| Compute discipline since ChatGPT launch | ”I said ‘all of it‘“ | A founding stance, not a 2025 reaction — see his repeated “there’s not going to be enough compute” framing |
| Codex velocity | ”Just over the past week we’ve released a bunch of features” | Lines up with the 16 April 2026 Codex for (almost) everything shipfest |
Two of those four (December’s coding inflection and the Codex shipfest) directly produce the bottleneck Brockman names. When an agent writes 80% of your code instead of 20%, the per-engineer review surface goes up roughly 4×. When Codex adds computer use, image generation, and persistent memory in a single week, the cognitive load of “what is my agent actually doing” goes up another step. The talk’s thesis is the second derivative of the talk’s bragging.
The system-engineer story Brockman tells later makes the same point from the other end. An OpenAI infra engineer, who said GPT-5.0–5.2 had given him no useful output, handed GPT-5.4 a design doc and went to sleep. When he woke up, the model had implemented the spec, instrumented it, profiled it, and iterated to an optimized result. The work that used to take a week was done overnight. The new bottleneck wasn’t whether the engineer could write the code; it was whether he could review what an unsupervised model had written, against a problem hard enough that the supposed reviewer was the same person who couldn’t find time to do it manually.
That’s the shape of the new constraint. Execution has compressed; verification hasn’t.
What “attention as bottleneck” looks like in production today
The cleanest empirical proof that Brockman’s thesis is correct comes from somebody else’s company. On 25 March 2026, Anthropic published an engineering post introducing Claude Code’s auto mode and opened with a startling internal stat:
“Claude Code users approve 93% of permission prompts.”
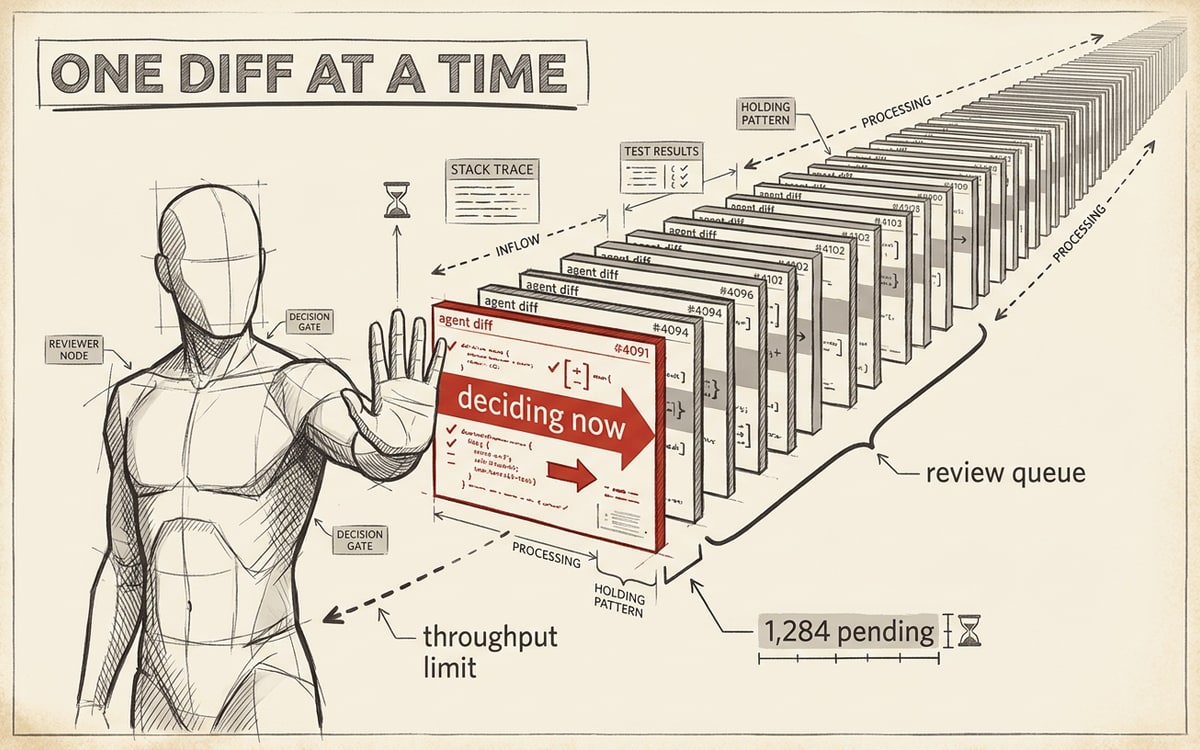
Not after careful review — reflexively. Approval has become the rubber stamp the rubber stamp was meant to prevent. Anthropic’s response is a two-stage transcript classifier running on Sonnet 4.6, described in detail in the post and independently stress-tested by HKUST and ETH Zurich in an arXiv paper that pegs the false-positive rate at 0.4% and false-negative rate at 17%. Read carefully, that’s a confession: a 0.4% FPR sounds tight until you remember the previous system was a human pressing “approve” without reading. The classifier is being asked to substitute for an attention-bankrupt operator, not for a careful one.
This is exactly the gap Brockman pointed at. “Clicking approve, approve, approve is kind of where we’ve been,” he said. “Humans are not very good at that either.” Anthropic’s number puts a precise value on “not very good”: 7% non-rubber-stamp. Auto mode is the design response — not because the underlying capability got worse, but because attention got scarce enough to need automating.
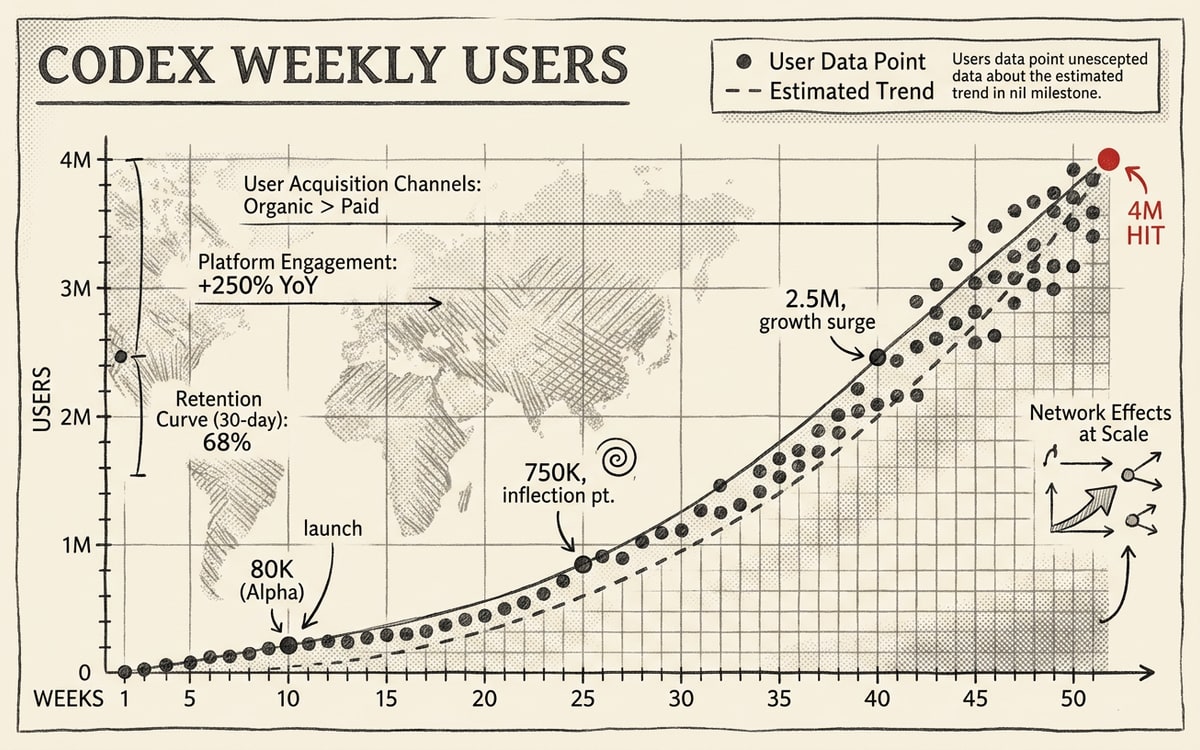
OpenAI’s product team is shipping the same insight under different brand names. The 16 April 2026 Codex release positioned Codex as a tool not just for software engineers but “for anyone who’s doing work with a computer”, which is precisely the move that scales the attention problem from the engineering org to every white-collar function. Codex Cloud reached 4 million weekly users by 22 April 2026, up from 3 million two weeks earlier and 1.6 million on 4 March — the same trajectory that is currently piling diffs into review queues that nobody designed.
The Codex review pane documentation and the Codex code review in GitHub flow are entirely about that pile-up: structured diff inspection, targeted feedback, “decide what to keep.” This is the UX of an interface designed for a human who knows they will not read every line. It is the explicit acknowledgment that the agent’s output has overflowed the supervisor.
And then there is Chronicle, the Codex memory feature OpenAI opened to ChatGPT Pro users on macOS on 20 April 2026. Brockman demoed it on stage as the answer to “you spend so much of your effort right now just explaining to your computer what’s going on.” Reframed, it’s an attention-saving primitive — a passive sensor so the human doesn’t have to spend the scarce cycles repeating context. Whatever you think of the privacy tradeoffs of always-on screen capture, the pitch is exactly the bottleneck thesis: stop making the user explain themselves.
The agent UX is being rebuilt around one human reviewing many agents
The clearest signal that the bottleneck has moved isn’t a research paper. It’s that every serious coding-agent product, in the last sixty days, has shipped some variant of the same UX: a multi-agent inbox, a parallel-agent workspace, a queue of diffs waiting for the one human in the room.
| Product | Ship date | Attention-overhead UX pattern | What it bets the human spends time on |
|---|---|---|---|
| Cursor 3 | 2 Apr 2026 | Agents Window — many agents in parallel across repos, worktrees, cloud, SSH | Routing prompts and merging diffs, not editing files |
| Codex for (almost) everything | 16 Apr 2026 | Cloud-hosted parallel tasks, diff review pane, Slack hand-off | ”Decide what to keep” on agent output |
| Codex Chronicle | 20 Apr 2026 | Passive screen memory; agent infers context | Goal-setting, not context-restating |
| Devin Review | 27 Jan 2026 (preview); autofixes Feb 2026 | Agent-vs-agent review; autofixes review comments | Reviewing the reviewer of the writer |
| Devin can now Manage Devins | 19 Mar 2026 | Manager Devin breaks down work and delegates to a fleet of Devins | Setting top-level intent; “managing the manager” |
| Anthropic auto mode | 25 Mar 2026 | Sonnet 4.6 classifier substitutes for human approver | High-risk decisions only; routine ones auto-cleared |
| LangChain ambient agents / Agent Inbox | 2025–26 | Event-driven background agents; inbox of items needing review | Triaging, not prompting |
| HumanLayer | 2025+ | API-level “require approval” for any irreversible action | Approving the dangerous tail |
Two patterns are shared across all eight rows. First, none of these products assumes the human is the executor anymore — every one of them assumes the human is a reviewer, approver, or router. Second, every one of them has shipped a structural answer to the same problem: when one person is supervising N agents, N’s growth has outrun the per-agent attention budget. Cursor’s own framing of Cursor 3 is explicit: “Engineers are still micromanaging individual agents… We’re building toward [a future where] fleets of agents work autonomously.” That sentence is a Brockman thesis statement that didn’t pass through Brockman.
This is also what makes the agent-design-patterns literature converge. Lance Martin’s survey of 2026 patterns opens by noting “agent task length doubles every 7 months” and immediately pivots to context engineering and review queues, because longer-running agents make the supervision problem worse, not better. Harrison Chase has been arguing for ambient agents and the Agent Inbox since January 2025; twelve months on, the entire ecosystem (from HumanLayer’s require-approval API to AgentMail’s agent-inbox spec to LangGraph’s interrupt-based human review) has converged on the exact UX category Chase named.
The ecosystem caught up to its own thesis. Brockman is the Sequoia stage announcing that the building has been on fire for a quarter.
Where the bottleneck breaks
The most interesting part of Brockman’s talk isn’t where he’s right; it’s where he’s vague. The Slack-escalation story is funny, but it’s a single anecdote about EQ. The harder question (who is accountable when a fleet of agents shares a single reviewer who can’t possibly read all the output) is still unsolved across every product in the table above.
Three concrete failure modes have already shown up in the field.
The reviewer of the reviewer of the reviewer. Cognition’s Devin Review autofixes post is candid that the new feature “massively increased our internal token spend” because Devin is now reviewing Devin and answering its own review comments. The honest version of the pitch is that human attention got expensive enough that it’s now cheaper to spin a third agent to mediate between the first two. That works as long as the meta-agent is trustworthy, which is precisely what the auto mode post quietly admits is a research problem — Claude Opus 4.6’s system card includes incidents like deleting remote git branches and uploading auth tokens to internal compute clusters. Each layer of agent supervision adds capability and removes legibility from the human at the top.
Iterative scope changes break the model. Cognition’s own 2025 performance review of Devin, the most honest internal-data document any agent vendor has published, says it bluntly: “Devin handles clear upfront scoping well, but not mid-task requirement changes… This puts more of a responsibility on the engineer to scope work well up-front.” Translation: when the human’s attention is the bottleneck, agents that don’t gracefully accept mid-flight corrections push the cognitive load back onto the only thing the system was supposed to free up.
Approval fatigue compounds. Anthropic’s 93% prompt-approval number is a measurement, not a target. Every product that ships an “approve everything” toggle is, mechanically, training its users to skip toward that toggle. Auto mode genuinely improves on the baseline (the HKUST/ETH stress-test paper gives it credit for catching a meaningful slice of dangerous actions), but a 17% false-negative rate on a classifier that gates production tool use is not the end state of this design. It’s a holding pattern while the substrate matures.
The Slack-escalates-to-the-manager story is the same failure in miniature. The agent did the right thing locally (escalate when blocked) and the wrong thing globally (spend a senior person’s attention without a budget for it). The fix is not better EQ training; it’s an attention-aware tool layer that knows what social capital each action is spending. Nothing in the production stack has that yet.
The counter-argument: maybe the bottleneck is just real
The strongest objection to Brockman’s framing comes from his former colleague. Andrej Karpathy (interviewed on Sequoia’s same stage 24 hours later, covered in Part 1 of this series) has been arguing for six months that this is the decade of agents, not the year of agents. His specific complaint, in his Dwarkesh Patel interview, is that current systems lack continual learning, durable memory, multimodality, and autonomy, and that no amount of UX tape over the human-supervision layer fixes the underlying capability gap.
Karpathy’s other framing — AI is great at offering, bad at offloading — is, read carefully, a rephrasing of Brockman’s bottleneck claim from the opposite side of the table. If models are good at producing options and bad at executing without supervision, then the binding constraint on value is exactly the supervisory bandwidth of the human in the loop. The two are not in disagreement about the constraint. They disagree about whether the right response is to redesign the UX (Brockman, ship-now) or to redesign the model (Karpathy, ten-year horizon).
The “humans don’t scale” critique (popular on engineering Twitter, rendered cleanly in Cognition’s “fleet of Devins” pitch) claims the answer is to remove humans entirely from the inner loop. That works for migrations, vulnerability patches, and unit tests, where Cognition’s own data shows 67% of Devin’s PRs now merge versus 34% last year, and where humans take 30 minutes per security vulnerability against Devin’s 1.5. But Cognition is also explicit that Devin can’t manage stakeholders, deal with teammates’ emotions, or coach iteratively. The autonomous-fleet model only works on the verifiable, low-judgment slice of work — exactly the slice Karpathy’s verifiability post predicts will get automated first. Beyond that line, the human is back, and the bottleneck is back with them.
So both the optimist (Brockman) and the skeptic (Karpathy) end up at the same operational claim: human judgment is the new constraint. They differ on whether it’s a UX problem to be designed around (Codex review panes, agent inboxes, auto mode) or a capability problem to be researched out (continual learning, memory, agentic autonomy). The right read is that both bets are running in parallel, and the products in the table above are how the design bet looks while the research bet runs.
The Stargate corollary
Brockman’s career-long compute-at-all-costs posture (“I said all of it” when asked how much to buy at ChatGPT launch, restated in his April 2026 Tae Kim interview and on the Ascent stage) is not in tension with the attention-bottleneck thesis. It’s the precondition.
The whole point of Stargate’s $500B, 10-gigawatt commitment, now running ahead of schedule per OpenAI’s 30 April 2026 update with 3GW added in the last 90 days, is to push compute out of the binding-constraint position. Once compute is no longer scarce relative to demand, the next thing in line (Brockman says explicitly, on stage) becomes the bottleneck. He’s been saying “there’s not going to be enough compute” for a year because that’s the bet his company is built on. The attention thesis is what comes after that bet pays off.
This also explains why the Codex product roadmap reads, in retrospect, like a single coherent design. Codex hit 4M weekly users in late April. The week before, the Codex for (almost) everything launch added computer use, image generation, memory, and a Mac app. The week before that, Chronicle. None of those features are “make the agent smarter” features. They are all “remove a unit of human attention from the inner loop” features — passive context capture, parallel task spawning, multi-modal output, persistent preference memory. If you take the bottleneck thesis seriously, the Codex roadmap is the bottleneck thesis as a product.
Position: Brockman named the constraint that the agent stack is already pricing in
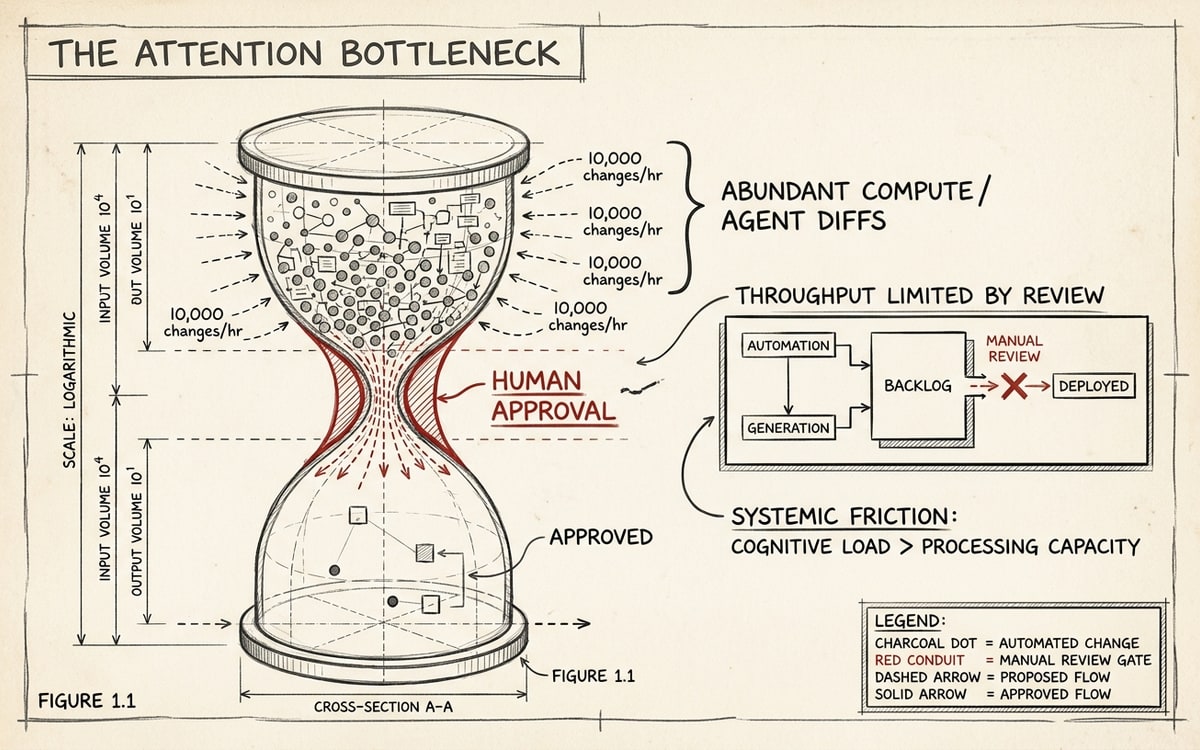
The talk earned its 6/10 in our editor pre-read because Brockman, characteristically, speaks in altitude. The Slack anecdote is the only place he gets specific about the design implication of his own thesis, and even there he leaves the post-mortem at “we’re still building up the EQ of the model.” That’s not an analytical claim; it’s a marketing line.
The thesis itself, though, is correct, and it is correct in a stronger form than Brockman states. Read against the production-product stack of the last sixty days, “human attention is the new bottleneck” is not a prediction. It is the design assumption that Anthropic, Cognition, Cursor, OpenAI, LangChain, and HumanLayer have already encoded into shipping software. The 93% rubber-stamp number, the Cursor 3 Agents Window, Devin Manage Devins, the Codex review pane, ambient agents, the agent inbox — every one of those is a UX response to exactly the constraint Brockman named. The question is not whether the bottleneck is real. The question is which of these UX patterns survives contact with the next 10× in agent fan-out.
Three predictions, on the basis of what’s already shipped:
- The “approve everything” toggle is dead within a year. Anthropic’s auto mode is the bridge product. The end state is per-action risk classification with human-in-loop reserved for the irreversible tail — which is what HumanLayer’s API and Anthropic’s classifier are converging on from opposite ends. If your product still gates work on a binary approval prompt, it’s accumulating tech debt against the 93% number.
- The supervisor surface eats the IDE. Cursor 3 isn’t a code editor with an agent panel; it’s an agent panel with a code editor as a fallback. Codex’s Mac app is the same pattern. The center of gravity in dev tools has moved from “the file the human is editing” to “the queue of diffs the human is approving.” Companies still building IDE-first products are designing for the wrong bottleneck.
- Async agent fleets become the default unit of work. Devin’s manage-Devins flow and Codex’s parallel cloud tasks are the same product idea: a tree of agents executing in parallel, with a single supervisor pruning the tree. The accountability model that makes that legal, auditable, and survivable inside an enterprise is the unsolved problem of the next twelve months. Whoever ships it first owns the agent-orchestration layer the way GitHub owned source control.
Brockman’s 2022 essay “It’s time to become an ML engineer” closed with the claim that AI had crossed a utility threshold — that the models were finally good enough to bend whole careers around. The 2026 version of that essay is the AI Ascent transcript, with one substitution: the models are now too useful for the human in the loop to keep up with. The next utility threshold isn’t a model capability. It’s an attention budget.
Brockman delivered a 6/10 talk on a 9/10 thesis — and the production stack already knows it.